Pulse · technologymagazine.com
technologymagazine.com ·
Visa Opens European Testbed for AI Shopping Agents
Mathieu Altwegg, Visa's Head of Product and Solutions Europe, explains why the launch is a European testbed for AI agent checkouts
Read moreThe top stories in the fields you follow, at 08:00 your time.
Mathieu Altwegg, Visa's Head of Product and Solutions Europe, explains why the launch is a European testbed for AI agent checkouts
Read more Pulse · techtimes.com
AI agents acting outside authorization were seen by 77% of organizations using or exploring AI, a Nov. 19 Salt Security poll of 500 US and UK executives found, and 92% would still allow independent agent action. Five earlier surveys range from 24% to 65%, but respondents, sponsors and definitions
Read more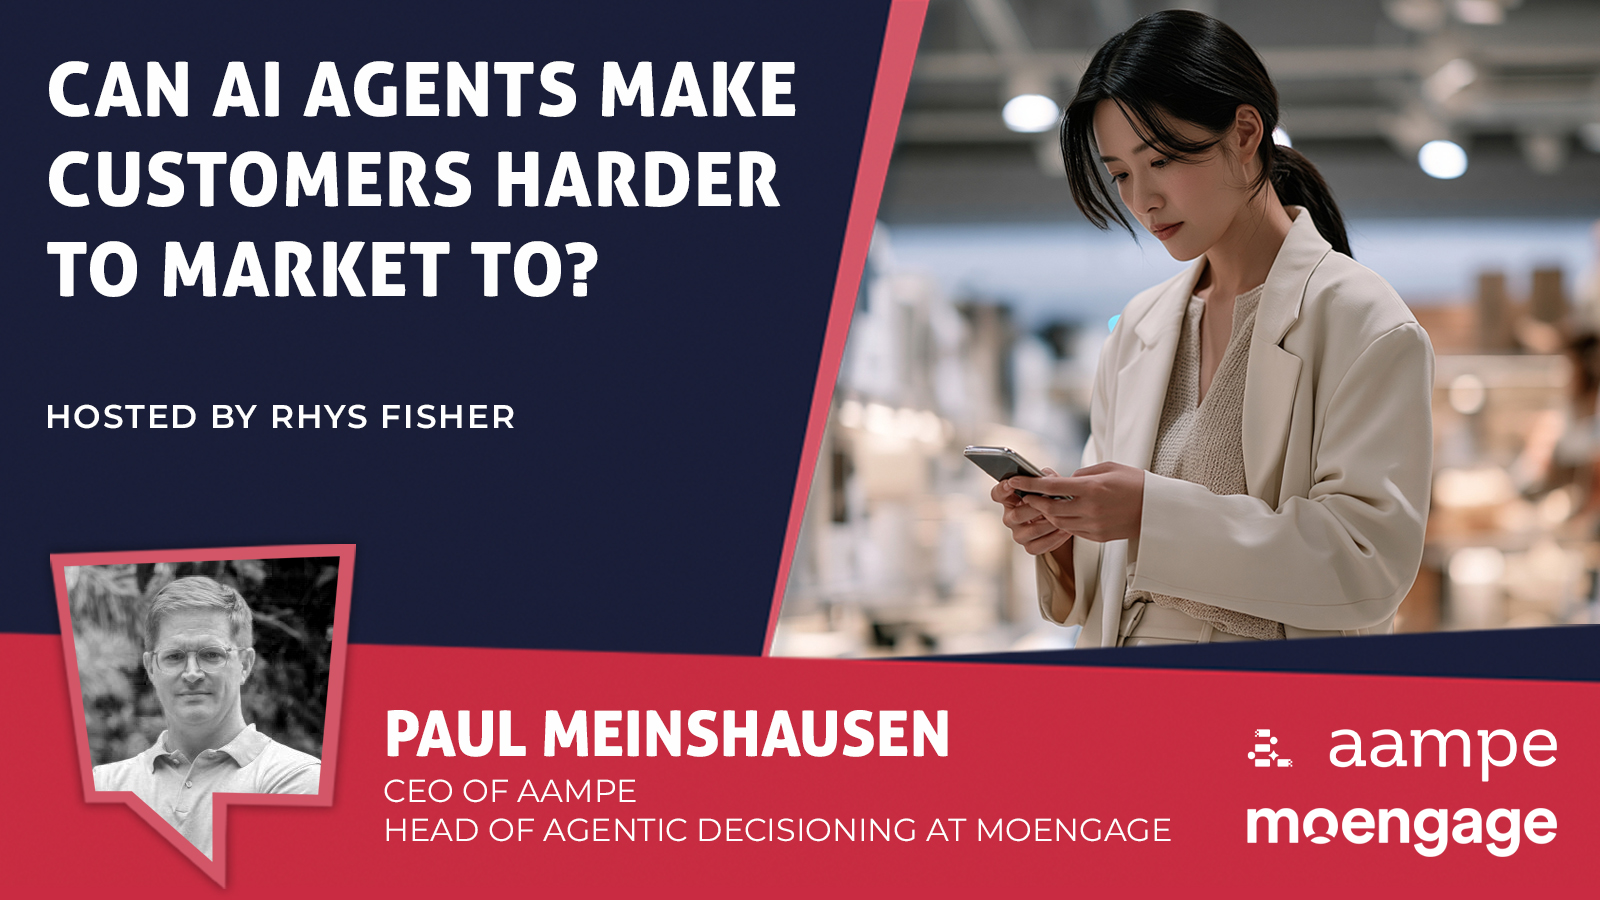 Pulse · cxtoday.com
Customers are using AI agents to review brand messages. MoEngage's Paul Meinshausen explains why marketing must learn from responses, not just send more.
Read moreBy Casey Hall and Sophie Yu SHANGHAI, Nov 20 (Reuters) - A flurry of US measures targeting China's access to advanced AI chips further pummelled Chinese technology stocks this week, as investors weigh whether Washington's latest curbs will slow Beijing's ambitions or accelerate its drive for technological self-sufficiency.
Read more Pulse · streamlinefeed.co.ke
Stack Overflow's survey shows near-universal AI adoption but only 6.6% trust it for important decisions, as productivity evidence stays contested.
Read moreApple is venturing into the field of autonomous AI agents, and they are targeting its release on the Mac next year based on job listings.
Read more Pulse · techbuzz.ai
Developers report losing satisfaction as AI assistants automate the craft of coding
Read more Pulse · note.com
Using generative AI for work is no longer anything special. On the other hand, from the perspective of managing Macs, the question of whether it is safe to input this information into cloud-based AI is always present.
Read more Pulse · analyticsinsight.net
Good morning, tech fam; here are some quick updates for you to catch up on! What's New Today: The US has approved 879,000 AI chips made by NVIDIA and AMD for Ch
Read moreClaude vs. ChatGPT: Discover 5 key differences in writing, coding, AI tools, features and pricing to help you decide which chatbot is right for you.
Read moreDiffusion distillation accelerates image and video generation by compressing a pretrained teacher's iterative sampling process into a few network evaluations. Distribution-based methods achieve this by matching the student's output distribution to the teacher's. This matching is often driven by reverse-KL objectives, whose mode-seeking bias favors dominant teacher modes at the expense of diversity across samples. We introduce Posterior Matching Distillation (PMD), a new member of the distribution-based distillation family that combines mode-covering posterior sampling with any-step generation. At zero population loss, PMD recovers the teacher's full posterior of clean images at each trained noise level. Its stochastic student supports any-step sampling budgets within the trained timestep grid without further training. To learn these posteriors, PMD matches exponentially reweighted averages of student samples conditioned on a fixed noisy state to corresponding teacher posterior means. Under Gaussian corruption, exponentially tilted posterior mean is a single teacher evaluation at a shifted input. We prove that, matching tilted means over an open neighborhood uniquely identifies…
Reinforcement learning (RL) post-training substantially improves the visual quality, text rendering, and compositional accuracy of diffusion transformers. Because capabilities such as rendering requested text or composing multiple objects are inherently prompt-dependent, a natural hypothesis is that improving them requires learning complex, input-dependent transformations. To isolate how much of these gains an input-independent shift explains, we probe each RL-tuned model with a deliberately simple parameterization: a fixed set of steering vectors added to the block outputs of the frozen base model. On SD3.5-M, these vectors hold 65x fewer parameters than the RL-tuned LoRA (0.29M against 18.8M). We fit them to match the velocity predictions of public RL-tuned checkpoints, with no reward in the objective. Although the vectors are identical for every prompt, token, and sampling seed, they recover 90.0-96.3% of the reward gains of six RL-tuned image models, and 89.8% and 111.9% on two RL-tuned video models. Initialized at zero and trained with online RL, the vectors alone exceed the reward gains of weight-based RL on text rendering (OCR) and human preference (PickScore) on SD3.5-M.…
Recent AI agents can generate playable games, but these games are not necessarily engaging. Mastery is a key source of engagement, yet designing for it requires extensive human play and tuning. We propose PlayCraft, an automated framework that uses a vision-based agent to play games and draws on its detailed play experience to revise them for mastery. Starting from an initial game, PlayCraft alternates between playing and crafting. In the playing stage, a player agent watches the game screen, uses the controls, and pursues the game objective over repeated episodes while retaining memory. After each episode, it reports its progress, outcomes, decisions, and reflections. In the crafting stage, a crafter agent uses these reports to revise the game. It estimates player abilities, predicts performance at different proficiency levels, and compares those predictions with a target learning progression. It diagnoses the game and addresses the gaps by giving players meaningful opportunities to improve through better decisions and execution. We evaluate games in fresh runs with player agents across three intelligence settings, measuring learning gain and learning slope. Compared with the…
Hybrid architectures have become mainstream among open-weight language models. Their global-attention and bounded-state layers maintain heterogeneous caches whose demands vary with context length and concurrency. We present TideCache, a serving system on CPU--GPU superchips with three components for allocating GPU memory among caches and managing their residency across GPU and host memory. The Transparent Cache Pool redistributes physical pages among cache components behind fixed virtual addresses, preserving cache layouts and backend interfaces. The Cache Streamer uses computation intervals provided by bounded-state layers to prefetch the next global-attention layer's prefix into GPU slots shared across global-attention layers, reducing GPU residency while overlapping layer-wise transfers with computation. Generated KV remains resident. The Request Scheduler selects resident or streamed execution and triggers capacity adjustments according to request size and queue state. Together, they let HBM released by streaming accommodate other cache components and additional requests. Implemented in SGLang and evaluated on GB300 and GH200 across seven model/platform configurations,…
Videos reveal how the world changes, but rarely the actions that cause those changes. Latent action learning recovers such supervision from visual transitions, yet often learns the underlying dynamics largely from scratch. We ask whether a pretrained video generator can instead provide the prior for both inverse and forward dynamics. We introduce O$^{2}$LaF, built on a simple principle: one prior, two dynamics. We initialize both models from the same pretrained video DiT and adapt them to their distinct roles: a feed-forward transition encoder with learnable action queries for inverse dynamics, and a causal, action-conditioned video generator for forward dynamics. By controlling information access and optimizing both dynamics end-to-end through a compact bottleneck, O$^{2}$LaF learns transferable actions from unlabeled videos. Across navigation and robotic manipulation, O$^{2}$LaF sets a new state of the art in few-shot action probing and enables stronger zero-shot action transfer across visual contexts and embodiments. Beyond generative video priors, we further extend our framework to predictive representation priors such as V-JEPA2, achieving competitive performance. Our…
High-dimensional Bayesian optimisation (HDBO) is an increasingly crowded field with new methods proposed at every major conference, making it ever harder to answer a deceptively simple question: "Which method is currently state-of-the-art?" In this paper, we question the…
Large language models (LLMs) increasingly support Web-based services that must balance response quality and inference cost across heterogeneous requests. Conventional routing selects one model per prompt, while fixed ensembles cannot adapt their composition and cost to…
Stochastic bilevel optimization provides a general framework for many machine learning applications, such as hyperparameter learning, data reweighting, language model alignment, and actor-critic reinforcement learning. However, most existing bilevel optimization methods treat…
In quantum systems, physical quantities of interest can be expressed as expectation values of a probability distribution, which allows their estimation by Markov Chain Monte Carlo (MCMC) methods. This approach, an instance of Quantum Monte Carlo (QMC), plays a central role in…