Pulse · marktechpost.com
Latest in AI and developer tools
The top stories in the fields you follow, at 08:00 your time.
 Pulse · unite.ai
Dallas-based 4Minds announced on November 12, 2026 that it raised $15 million in a Series A at a $500 million post-money valuation to advance its contextual AI platform and reach more enterprises, including highly
Read moreNov 12 (Reuters) - Applied Materials forecast first-quarter revenue above Wall Street expectations on Thursday, betting that strong demand for advanced AI chips will continue to fuel spending on its semiconductor manufacturing equipment.
Read more Pulse · travel.yahoo.com
Booking with an AI agent may seem convenient and potentially cost-saving, but consumer advocates say it's not the best approach for protecting your travel plans.
Read more Pulse · nbcnews.com
Critics say that Chinese companies' ability to access computing power remotely via other countries in Southeast Asia presents a major workaround to U.S. chip restrictions.
Read more Pulse · news.lavx.hu
Security teams faced a mix of mass exploitation attempts, espionage campaigns, and major takedowns this week, from 59 Linux kernel bugs to new backdoors, browser spyware, and AI-assisted phishing. The incidents show how attackers combine stolen access, trusted tools, and automation to stay inside networks longer.
Read moreThe airline points to a number of risks it says AI agents can pose, including exposing passengers' sensitive information and potentially violating FAA and DOT regulations
Read more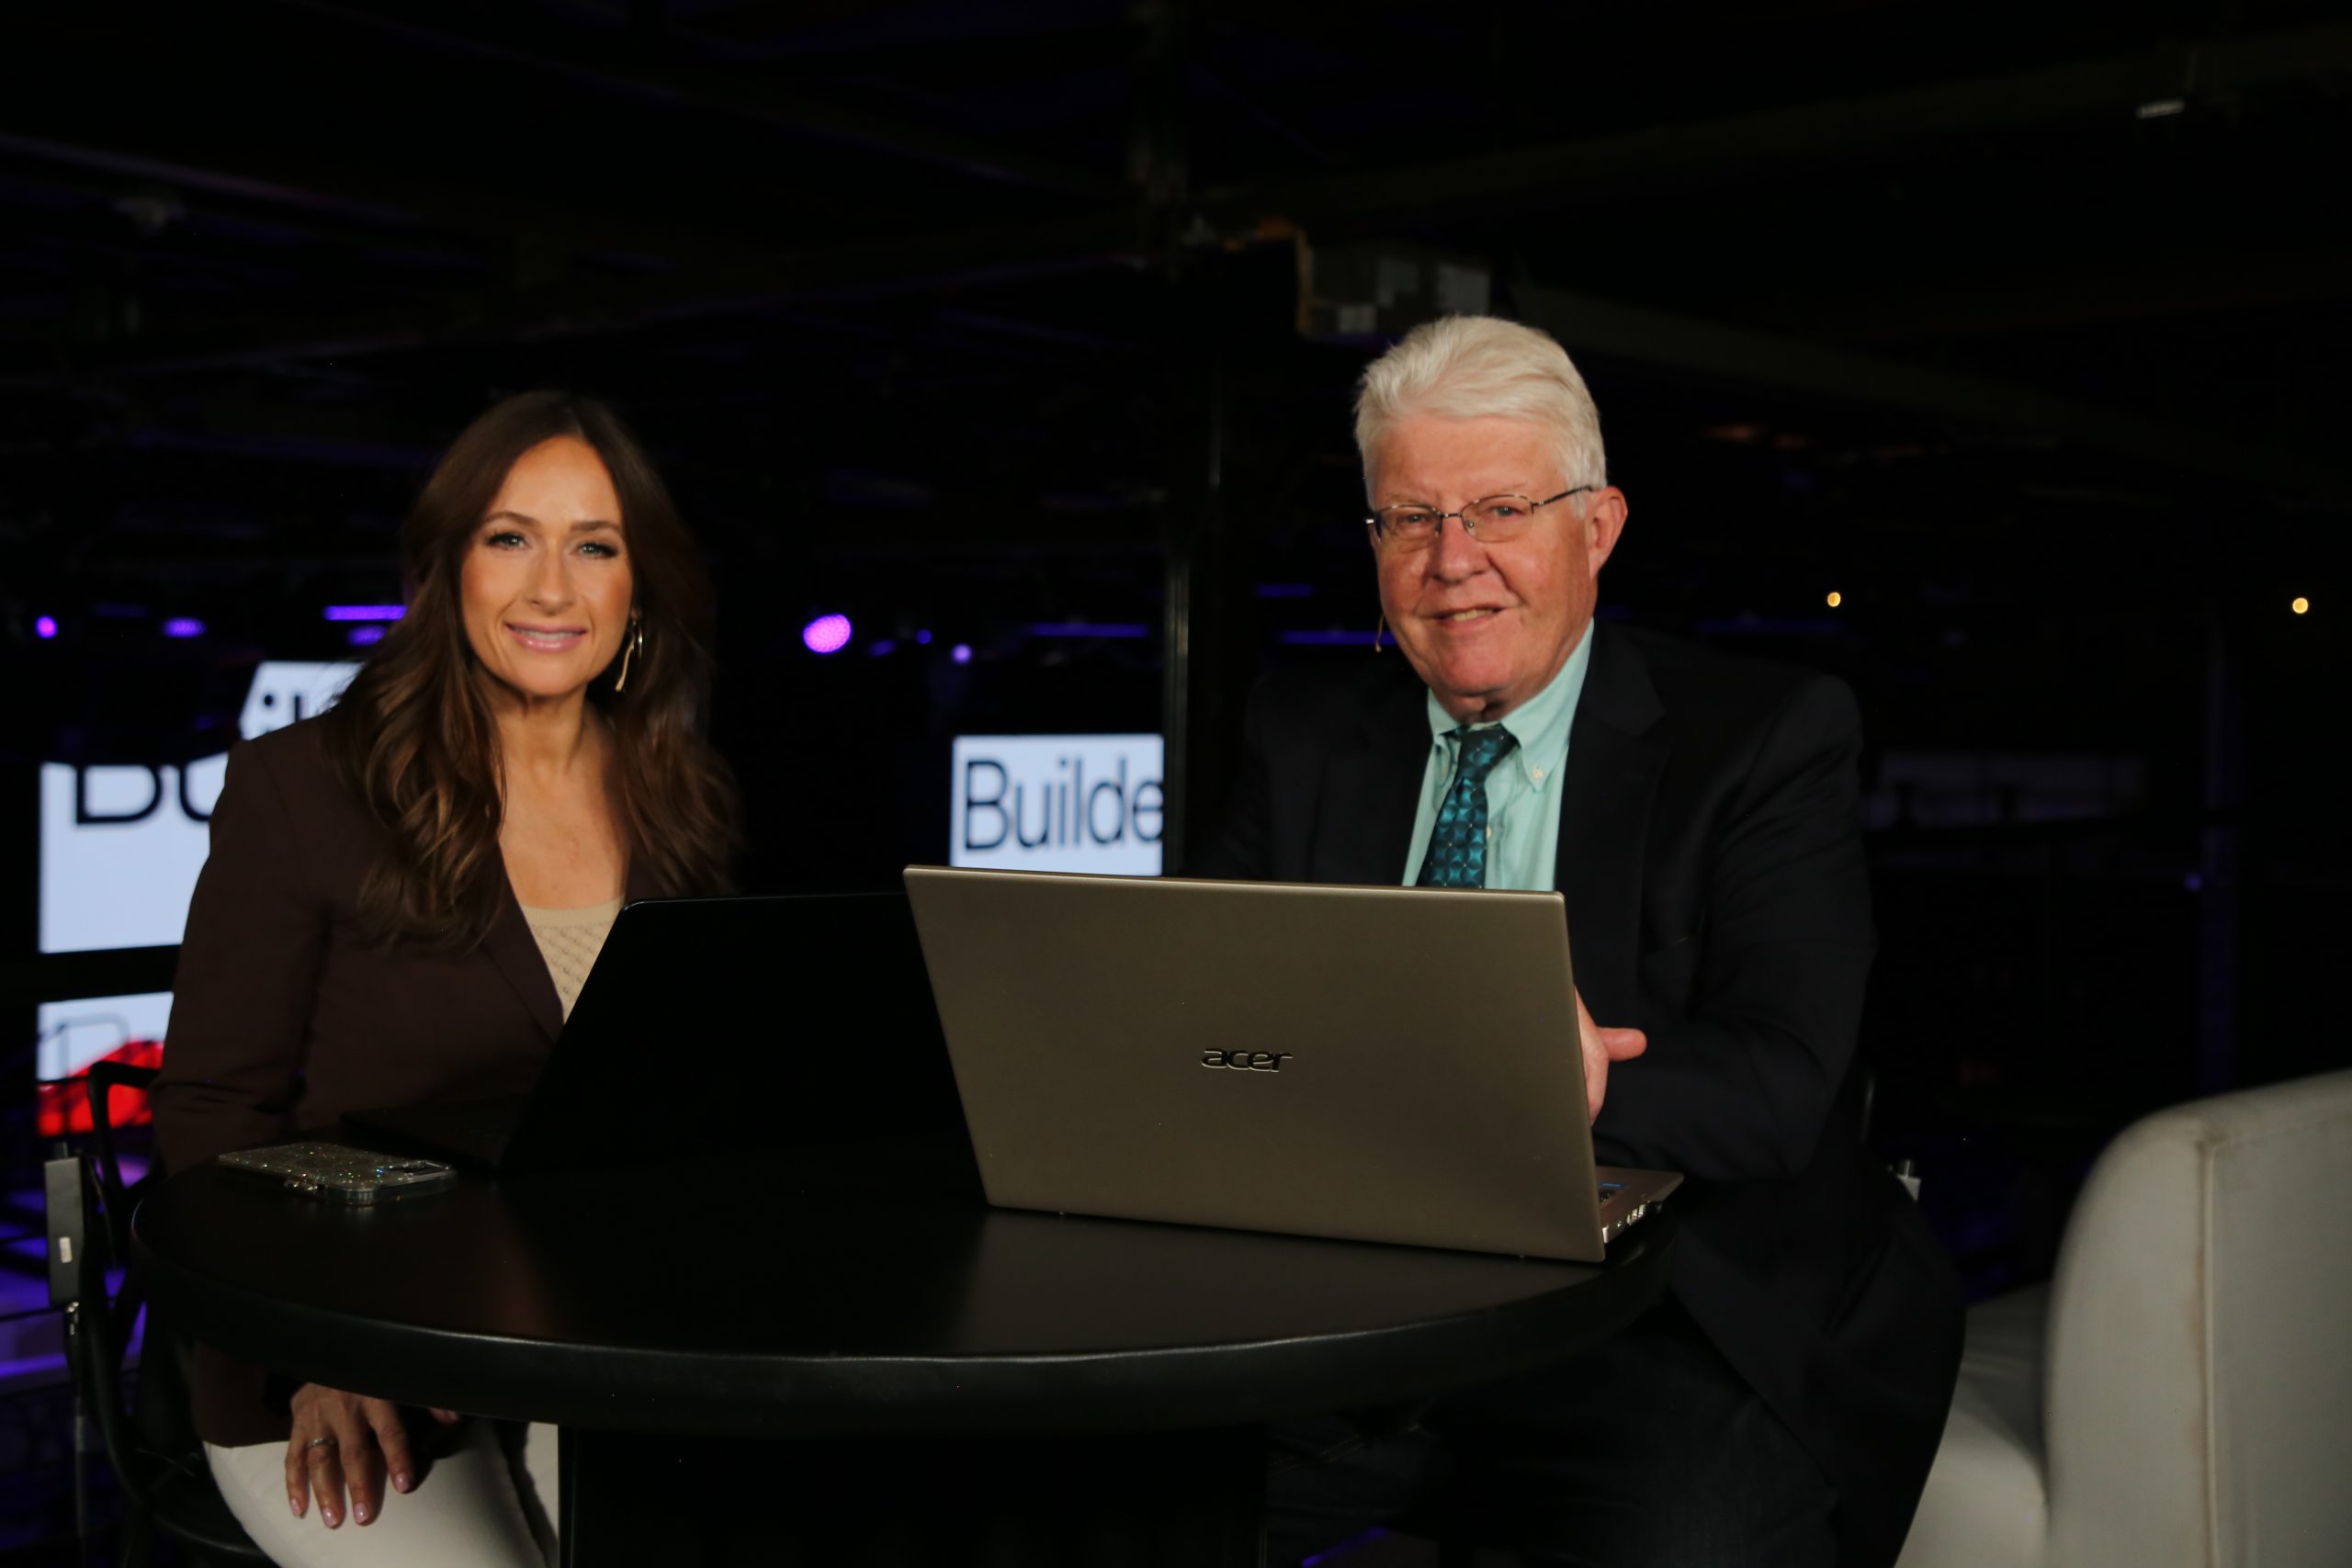 Pulse · siliconangle.com
Block Builderlab Launch Event 2026 showed AI agents working as named, auditable teammates backed by open-source code and firm security controls.
Read more Pulse · cnbc.com
AI agents can save you time, but an expert says decisions involving your health, wealth and privacy still need human input.
Read moreFoundation models pretrained on large natural-image collections are increasingly adapted for medical image segmentation, in the expectation that they will replace models trained for each task. Most comparisons, however, use data from the training distribution and a single task-specific baseline whose configuration is rarely justified, and therefore provide limited evidence of performance at new clinical sites. It also remains unclear how much of a foundation model must be adapted, and what determines this. We adapted a foundation model, DINOv2, with strategies ranging from tuning only its bias terms to full fine-tuning, and compared it with U-Nets and ResU-Nets trained from scratch. Experiments covered colonoscopy, breast ultrasound and dermoscopy, with testing on held-out data from the training source and on independent datasets from other institutions. The adapted foundation model generalised better on every external dataset. Within the training distribution, the task-specific models remained competitive when training data were abundant, and delineated boundaries more precisely, while the foundation model more often missed small lesions. Only a small fraction of the foundation…
DeepLearning (DL)-based Computer-Aided Diagnostic (CAD) systems have shown great promise in supporting clinicians, but their performance heavily depends on the availability of large, well-annotated datasets. In medical lesion detection, the scarcity of comprehensive, stan dardized annotations and the heterogeneity of existing datasets limit the development of robust foundation models. In this work, we introduce a novel approach to building a multi-domain foundation model for le sion detection by integrating diverse medical image datasets annotated for both anatomical structures and abnormalities. We first propose a student-teacher training strategy to effectively combine datasets with heterogeneous label spaces, mitigating catastrophic forgetting, and im proving feature learning. In addition, building on our previously pro posed example-based EM-DETR framework, we adapt it to jointly learn from multiple domain-specific datasets, enabling fine-grained, example driven detection across modalities. Our model achieves state-of-the-art (SOTA) results, with image-level AUC scores exceeding previous SOTA by 1% point on four key findings in CXRs. We achieve a leading mAP50 in CXRs and…
We present TorchCurves, a PyTorch library that treats vector-valued parametric curves as learnable primitives. Its central operation maps batches of scalar inputs to points on curves represented in B-spline or Legendre polynomial bases, with differentiation through both inputs and coefficients. Curve coefficients can be optimized jointly with the surrounding model or produced by another network. The library provides trainable modules, reusable basis modules, and a functional interface, supporting applications ranging from continuous feature embeddings to Kolmogorov-Arnold networks and functional regression. Its implementation combines classical evaluation algorithms with vectorized PyTorch operations, emphasizing readability and maintainability without custom hardware kernels. Timing experiments compare curve evaluation against NumPy and SciPy and KAN training against EfficientKAN across a range of problem sizes. The results illustrate where this generality remains computationally practical and where overhead is substantial. Library is available on GitHub at https://github.com/alexshtf/torchcurves.
Reinforcement learning with verifiable rewards (RLVR) produces rich training experience, yet outcome rewards reduce each attempt to a single number and leave most of this information unused. Training-time scaffolds, such as strategies or hints added to the prompt during training, offer a natural way to turn this information into guidance, but their design and adaptation are largely left to humans and tailored to specific domains. We introduce AutoScaffold, a unified AI-for-AI framework that turns a student's training experience into adaptive scaffolds, with minimal domain-specific information and no human intervention during training. A frozen teacher periodically examines this experience, diagnoses bottlenecks, and designs scaffolds in two forms: (i) strategies shared across a class of tasks and (ii) hints for individual hard tasks, adjusting the content and amount of support as the student learns. The scaffolds are removed at evaluation. We apply the same framework to ALFWorld, search-based QA, mathematical reasoning, and GPU kernel generation. When evaluated without scaffolds, students trained with AutoScaffold outperform those trained with the corresponding RL baselines in…
LLM agents are increasingly used for open-ended, data-driven scientific discovery, yet most of them evaluate hypotheses pointwise, testing an empirical claim $h$ only against its complement $\neg h$. When evidence rejects $h$, the agent learns that one explanation is unlikely but not which alternative the evidence supports. To recover that alternative, we introduce Contrastive Discovery, which replaces the single hypothesis with a contrast set, a scientific question paired with mutually exclusive and collectively exhaustive competing explanations. Each experiment is scored by how its evidence redistributes belief across the set, and the question is resolved when belief concentrates on one explanation. Because contrast sets change only the unit an agent proposes and scores, an existing agent can use them to re-evaluate evidence it has already collected or to guide its search. Across six domains, $89\%$ of the pointwise candidates with the largest belief shifts are rejections. On the same evidence, contrast sets resolve $73\%$ of these candidates to a specific alternative. When contrast sets guide search, the agent resolves $67\%$ more questions than pointwise surprisal under the…
AI Instruction-following TTS with decoupled voice design
AI Parameter-efficient video diffusion adaptation with point supervision
AI Learning dexterous robotic control from human videos
AI Cross-model LLM inference acceleration via attention map reuse