Figma introduces Figma Specs, code layers in open beta, MCP integrations, and Payload CMS features to help AI agents adhere to brand design system rules.
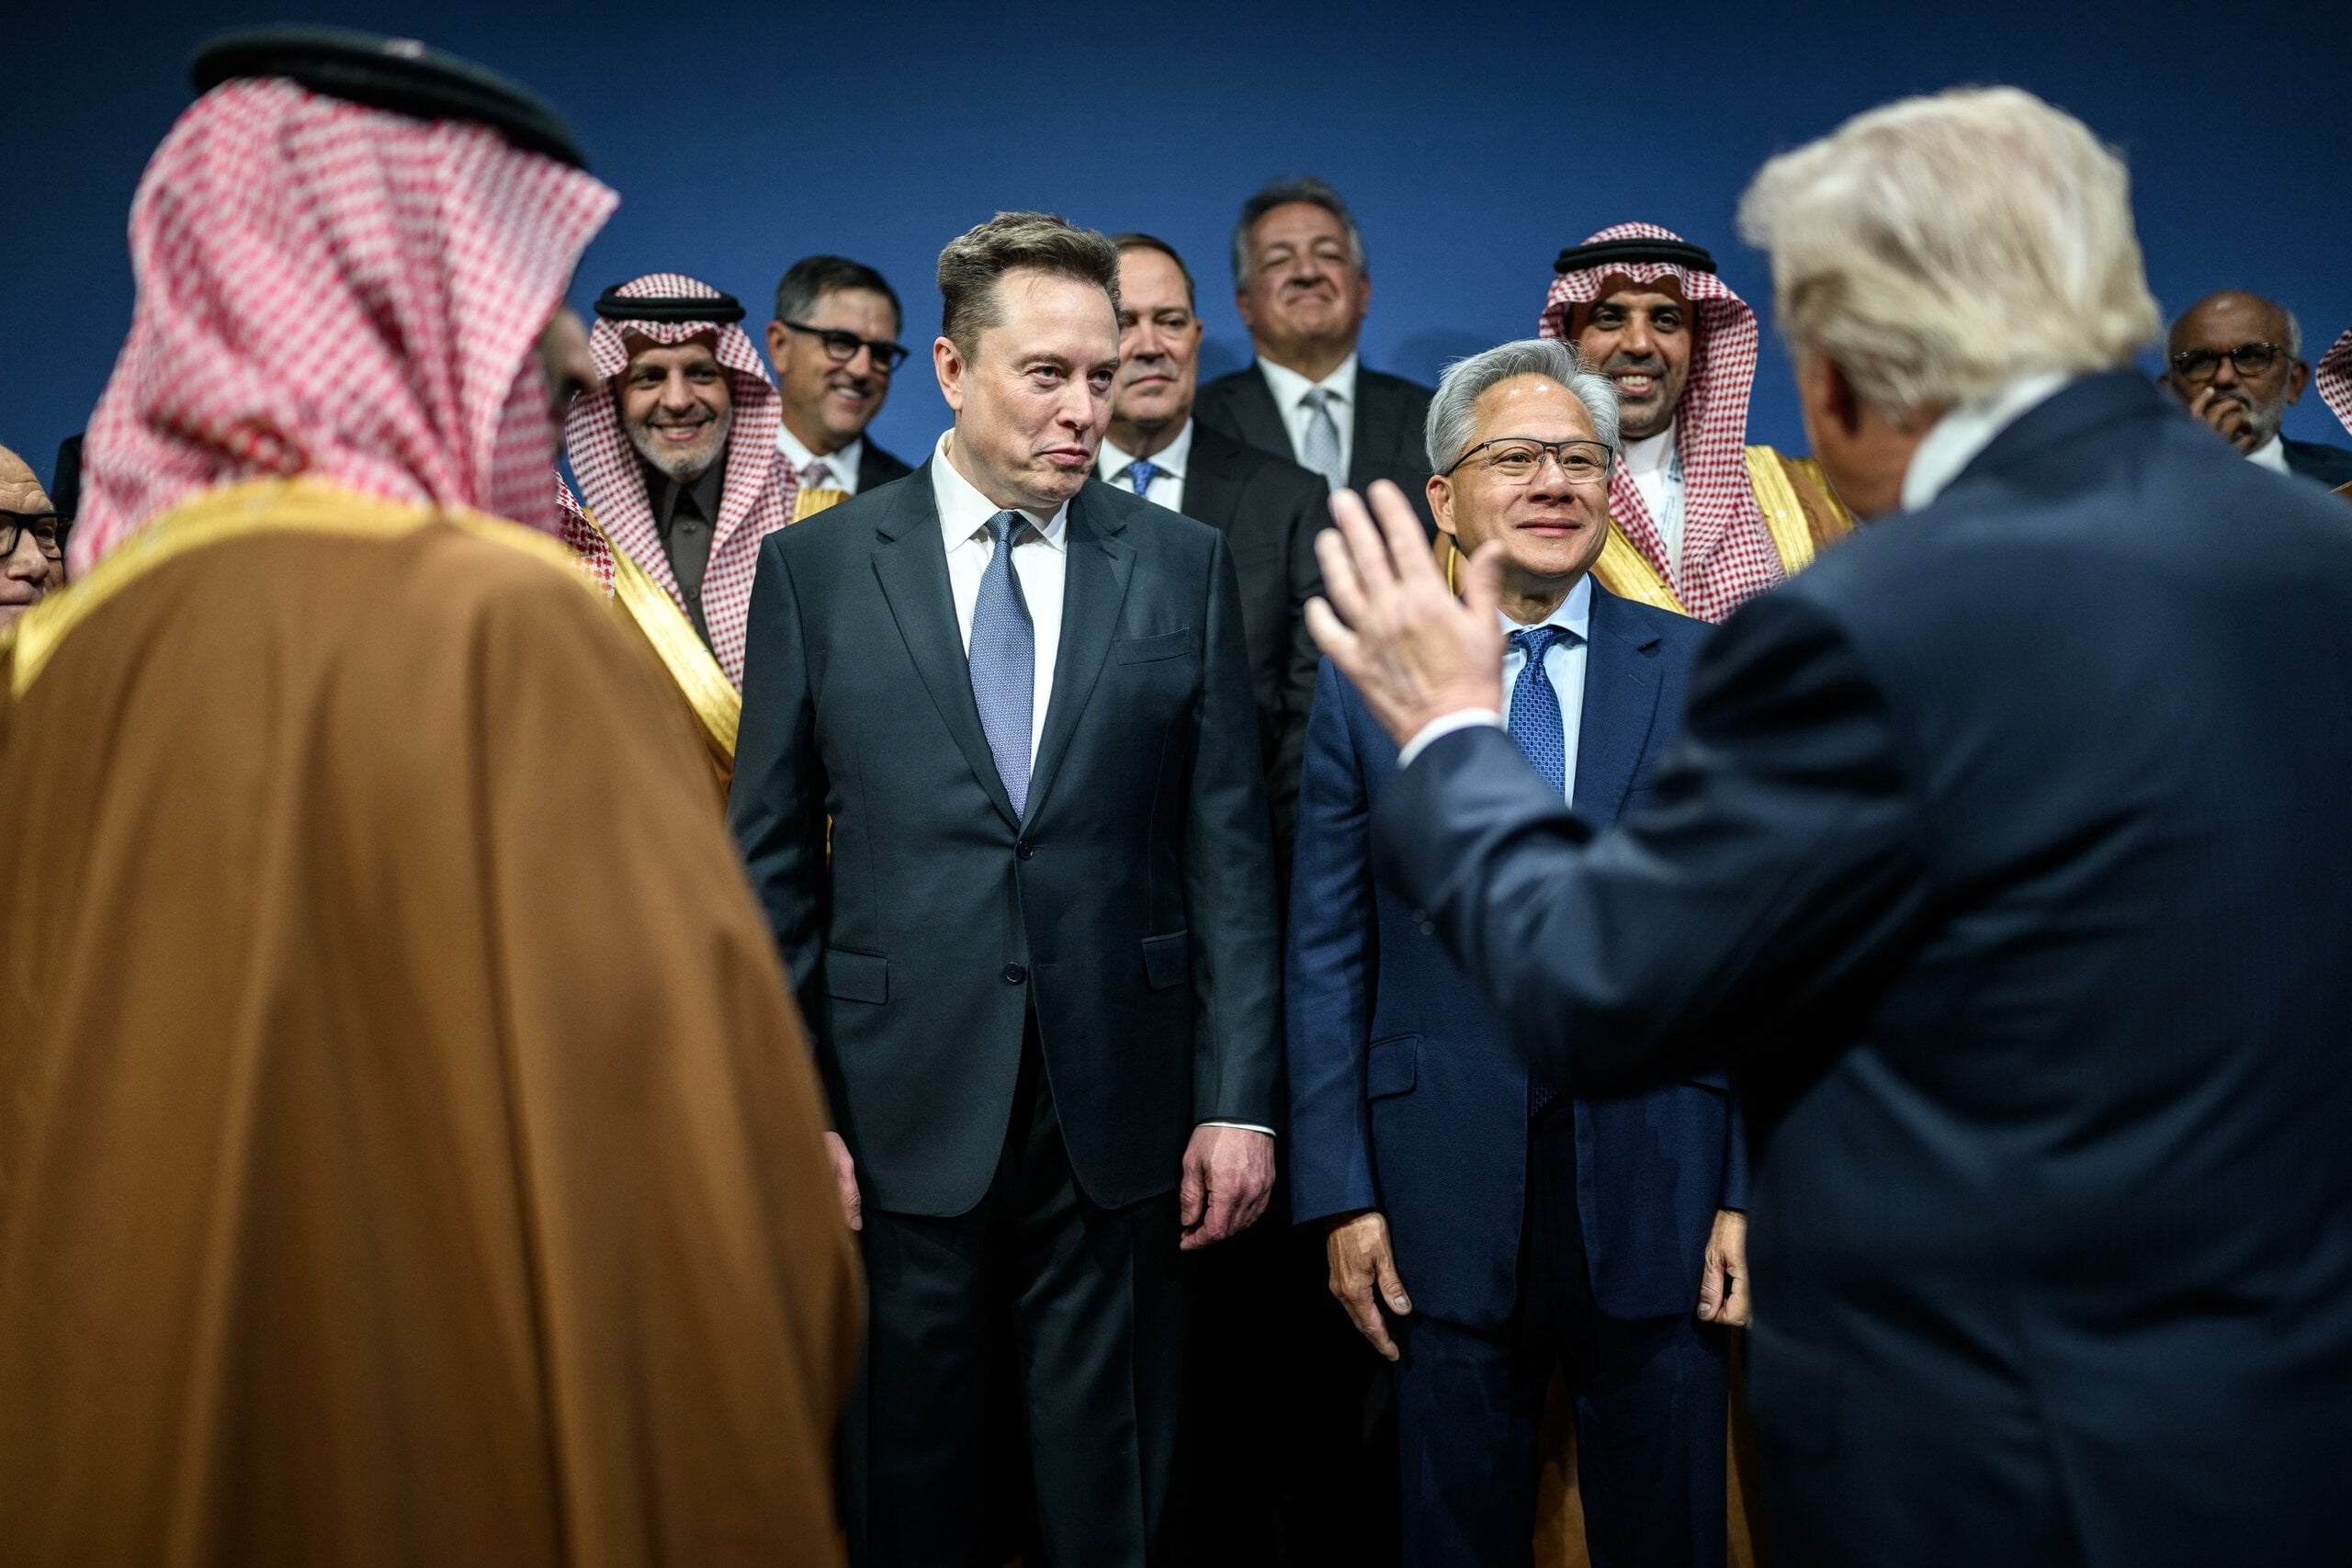
Elon Musk's comments during SpaceX's Q3 earnings call about rapidly expanding AI computing capacity sparked a premarket rally in chip stocks including NVIDIA, Intel, and SanDisk. Musk expects to increase SpaceX's AI compute power to 2.5-3 gigawatts by year-end and add up to 13 gigawatts in 2027, signaling strong future demand for AI chips. Despite this, the rally's sustainability remains uncertain as Musk leases compute capacity on spot market rates without long-term contracts. The market will…
Many companies cannot say what their AI agents did yesterday. Two former Doppel engineers built an open-source tool that records what agents do, and a Wall Street trading firm discovered them while testing it on its own machines. Asymptote Labs just raised $5.5M to turn that record into real-time defense.
SpaceX just told investors its AI compute pays back faster than almost anyone expected, and now Michael Burry is betting that confidence will crack. Two earnings reports in the coming weeks will decide who is right.
One quote from Elon Musk sent chip stocks surging in premarket trading, but whether that momentum signals a real turning point or just a brief relief rally is what the rest of October will decide.
LLM rerankers add of the order of \$0.2-0.3 per 1,000 queries and about a second of tail latency on top of a graph-augmented dense pipeline such as HippoRAG2, and on three multi-hop benchmarks they improve final-hop top-K coverage on seven of nine (dataset, K) cells, by up to…
Vision-Language-Action (VLA) models have emerged as a powerful paradigm for embodied intelligence, but fine-tuning them with reinforcement learning (RL) remains constrained by the cost of real-world robot interaction. Model-based reinforcement learning (MBRL) reduces this cost…
Large language model code generation benchmarks primarily evaluate well-resourced languages like Python and Java, where models benefit from abundant training data. They provide limited evidence about reasoning in unfamiliar computational models: deriving arithmetic from a…
Reinforcement learning (RL) has become a key technique for improving the reasoning and agentic abilities of large language models (LLMs). Although FP8 quantization can accelerate RL training, maintaining stability throughout an FP8 RL pipeline remains challenging. While…