Pulse · xda-developers.com
xda-developers.com ·
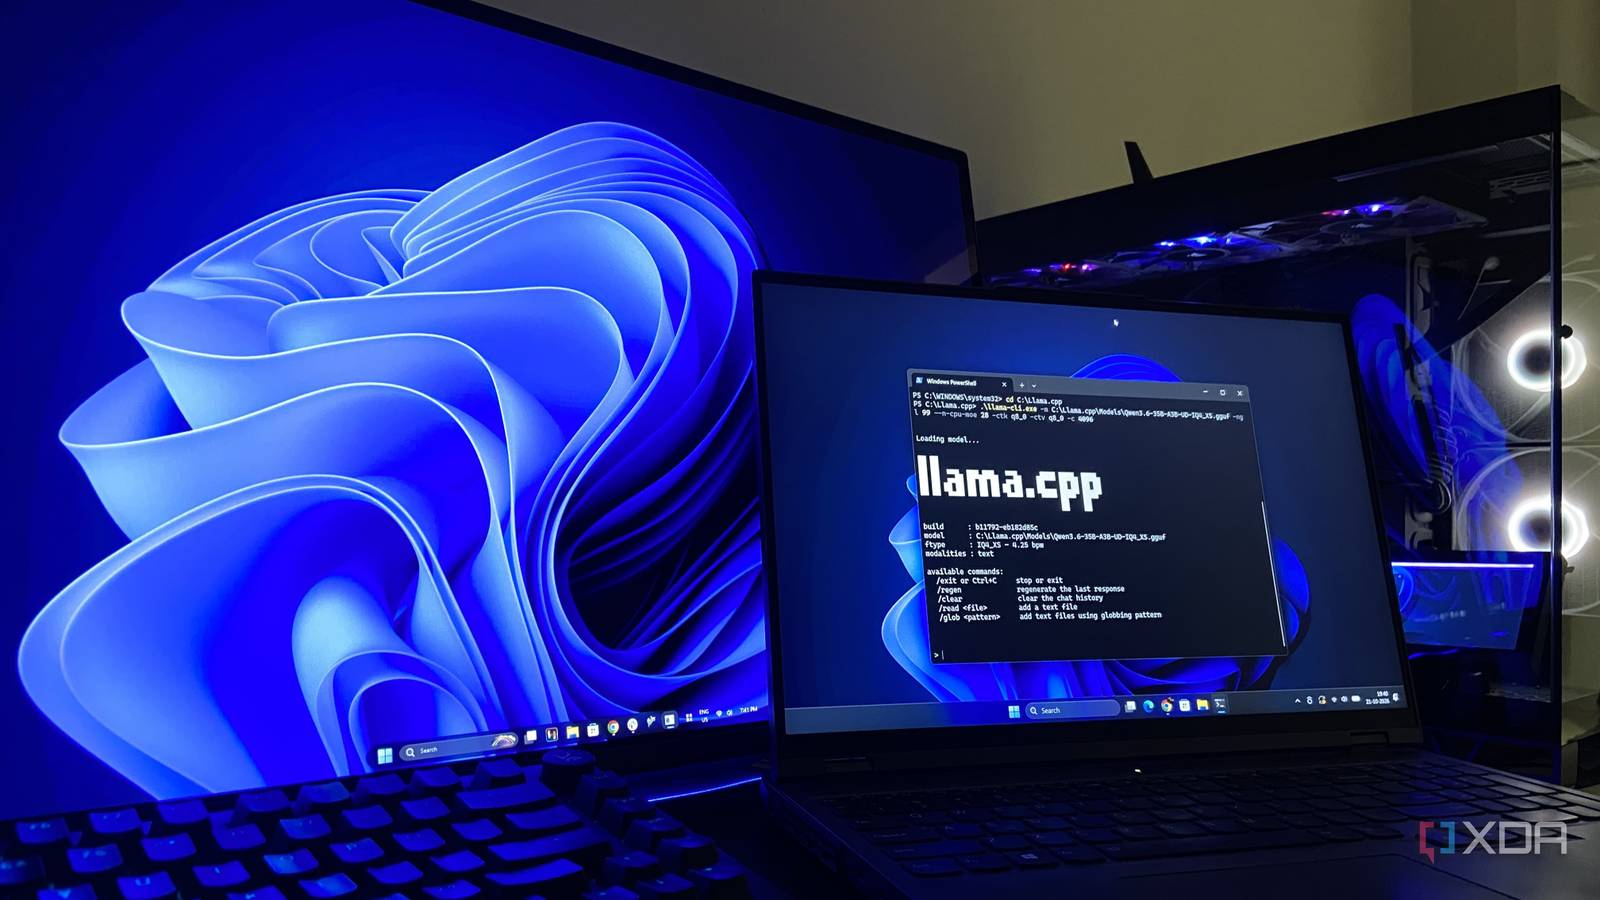
I changed one llama.cpp flag, and my 8GB laptop GPU now runs a 35B model faster than I can read
8GB of VRAM isn't the bottleneck, your settings probably are
Read moreThe top stories in the fields you follow, at 08:00 your time.
8GB of VRAM isn't the bottleneck, your settings probably are
Read moreDeepSeek-V4.1-Flash-1017 is a minor update to DeepSeek-V4.1-Flash, delivering substantial improvements across reasoning, coding, agentic tasks, and visual benchmarks. Alongside these gains, the model reduces task execution time and output length, enabling users to complete…