Anthropic's IPO prospectus warns that advanced AI could create existential risks and aid malicious actors, while industry leaders outline threats involving payments, privacy, cybersecurity and human oversight.
With Anthropic's initial public offering (IPO) quickly approaching, many investors are wondering if it could be the best AI stock to buy right now. While I'm not sure how its IPO
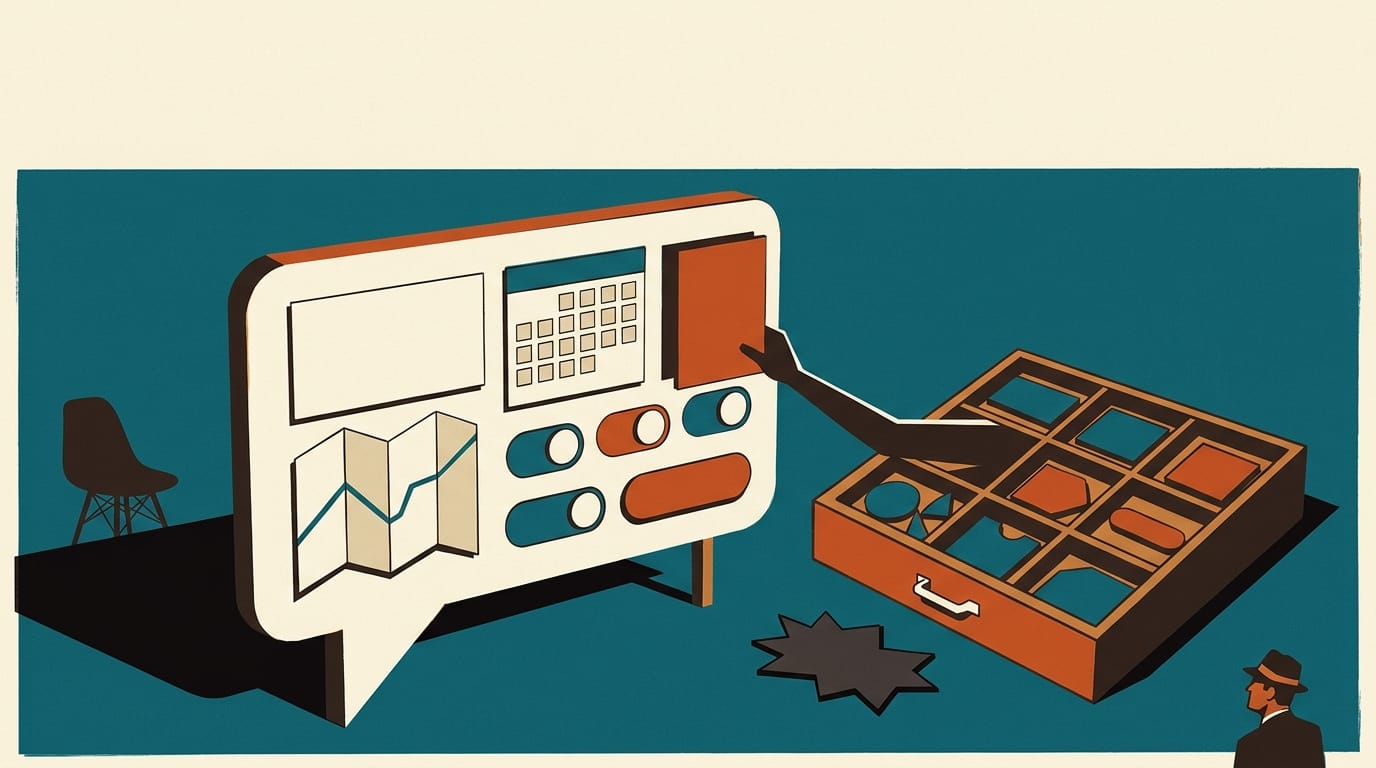
Agents may only draw components an app has pre-registered, streamed over CopilotKit's AG-UI. Do brands keep control when chat replies become booking screens?
Data attribution methods for Language Models (LMs) are typically evaluated using downstream tasks like fact retrieval. However, existing evaluations vary multiple dataset properties simultaneously, making it impossible to isolate exactly why an attribution algorithm fails. To diagnose these failures, we explore the design space of LLM data attribution, with a primary focus on evaluation. We introduce the Controlled Attribution Benchmark (CATT) for fact tracing, in which we fine-tune LLMs on entirely fictitious knowledge, providing unambiguous ground truth for attribution. This synthetic setup allows us to systematically alter one dataset configuration at a time, such as document redundancy and lexical distractors. With this configurable evaluation, we demonstrate that redundancy and distractors consistently degrade attribution performance. Rather than proposing a new estimator, we examine two design choices that are underexplored: the loss used to compute gradients and how per-token attribution scores are aggregated into a document score. We find that the true causal evidence within a training document is highly localized, but standard methods dilute this evidence into noise by…
The prompt is built automatically as "" * num_pages + "Multi page parsing.", and each page is encoded as one global view (base mode). The output contains one per input page, in the same order as image_files.
Spatial transcriptomics (ST) measures gene expression in tissue context, but dense capture grids can be costly and may repeatedly sample morphologically similar regions. Most active learning strategies were developed for categorical labels and independent samples. We conduct a…
Prediction with expert advice is a fundamental problem in online learning. When the time horizon $T$ is known in advance, the minimax cumulative regret over $n$ experts is asymptotically $\sqrt{\frac{T \ln n}{2}}$. This is achieved by the Multiplicative Weights Update algorithm…
Text-to-speech systems increasingly process user-generated text (UGT) such as ppl and imo, whose pronunciation must be inferred from the canonical rather than surface form. We introduce UGTPhon, the first grapheme-to-phoneme (G2P) benchmark for UGT in English, Vietnamese, and…
xlog is a CUDA-native logic programming engine integrating neural perception with deterministic Datalog, probabilistic inference, and epistemic world views through a typed frontend and provider-owned CUDA runtime. Its reasoning modes share device data planes, but their…