A survey in Artificial Intelligence Review categorises narrative theory-driven large language model methods and finds generation tasks lag behind understanding tasks.
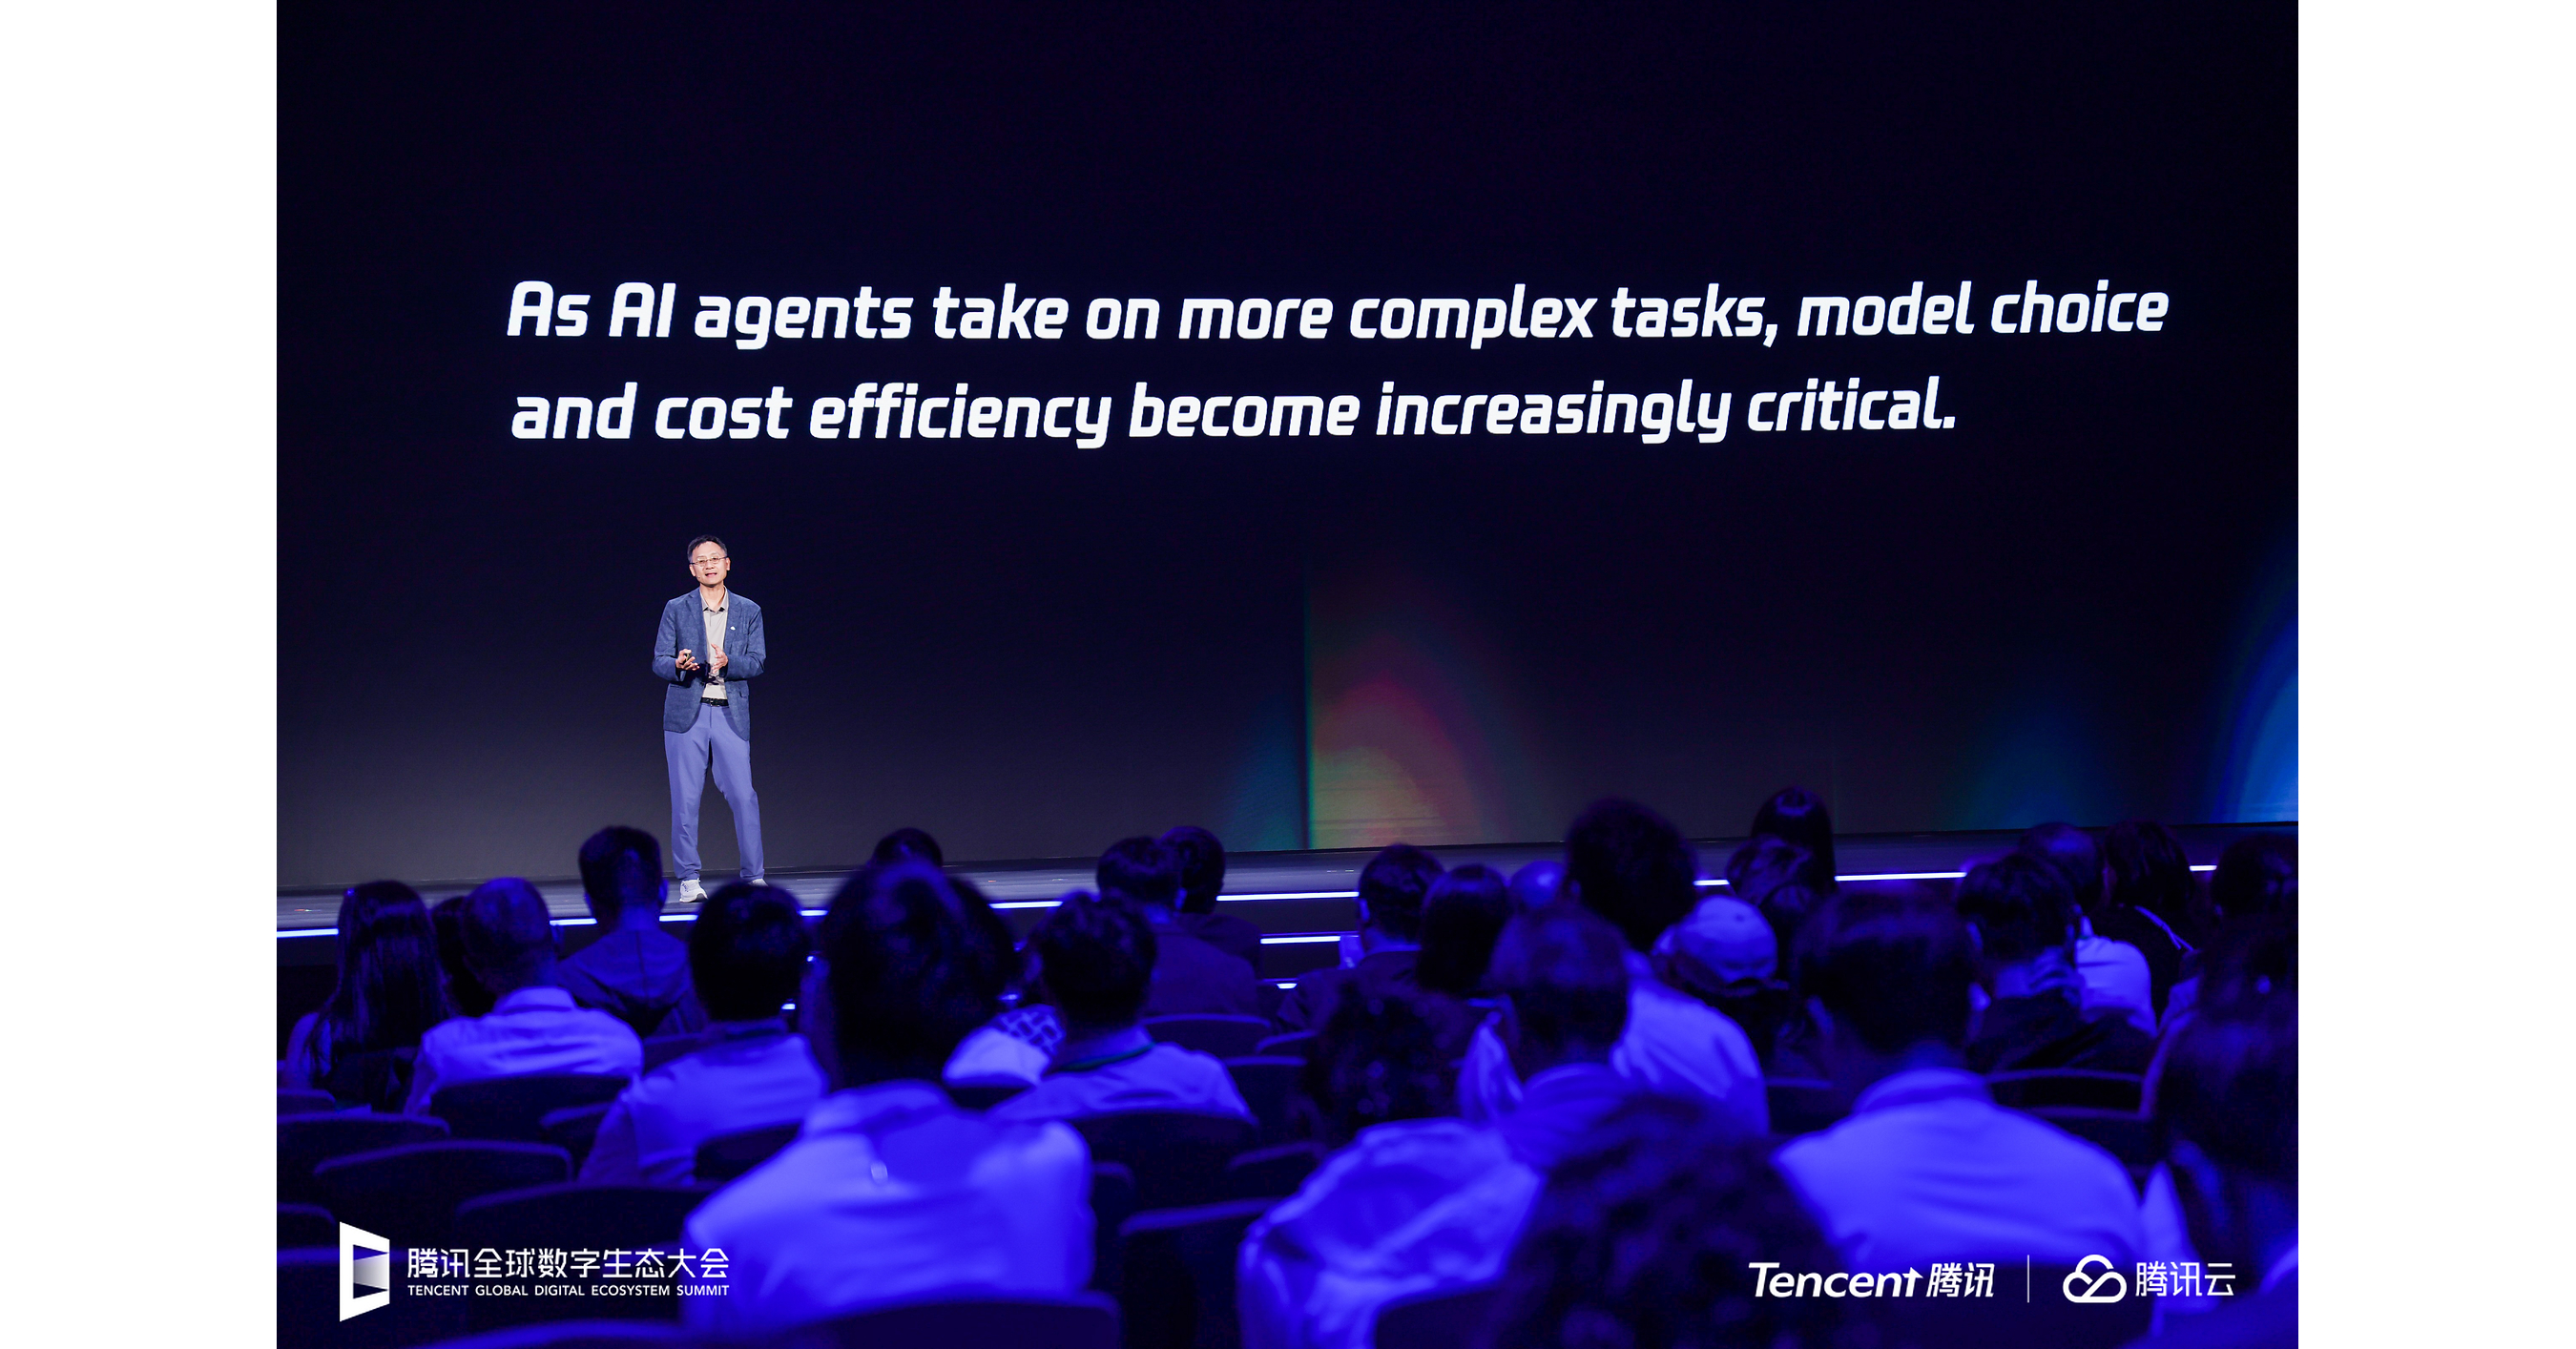
Tencent today unveiled the enterprise capabilities of its AI office productivity agent, WorkBuddy and previewed the upcoming general release of its Hy4 model and Hy4 Flash at the 2026 Tencent Global Digital Ecosystem Summit. Tencent Cloud's active overseas customer base has also doubled over the past year, while international demand for its AI products and services has grown by triple digits.
SHENZHEN, China, Oct. 30, 2026 /PRNewswire/ -- Tencent today unveiled the enterprise capabilities of its AI office productivity agent, WorkBuddy and previewed the upcoming general release of its Hy4 model and Hy4 Flash at the 2026 Tencent Global Digital ...
/PRNewswire/ -- Tencent today unveiled the enterprise capabilities of its AI office productivity agent, WorkBuddy and previewed the upcoming general release of...
Data attribution methods for Language Models (LMs) are typically evaluated using downstream tasks like fact retrieval. However, existing evaluations vary multiple dataset properties simultaneously, making it impossible to isolate exactly why an attribution algorithm fails. To diagnose these failures, we explore the design space of LLM data attribution, with a primary focus on evaluation. We introduce the Controlled Attribution Benchmark (CATT) for fact tracing, in which we fine-tune LLMs on entirely fictitious knowledge, providing unambiguous ground truth for attribution. This synthetic setup allows us to systematically alter one dataset configuration at a time, such as document redundancy and lexical distractors. With this configurable evaluation, we demonstrate that redundancy and distractors consistently degrade attribution performance. Rather than proposing a new estimator, we examine two design choices that are underexplored: the loss used to compute gradients and how per-token attribution scores are aggregated into a document score. We find that the true causal evidence within a training document is highly localized, but standard methods dilute this evidence into noise by…
In Nanbeige4.3, we take a foundational step toward pushing the boundaries of lightweight agents. Our strategy centers on building a high-capacity teacher agent first, which will subsequently anchor the distillation of advanced agentic capabilities into smaller models.
Ryan is joined by Charity Majors, co-founder and CTO at Honeycomb, for a conversation about applying the concept of immutable infrastructure to software development to treat code like cattle instead of pets, shifting the paradigm of system specifications to accommodate the…
Zero-shot multimodal anomaly detection commonly assumes that RGB and point cloud modalities are equally reliable and can contribute uniformly to anomaly localization. We challenge this assumption. Using a set of recently proposed stringent metrics that penalize false anomaly…
Postoperative acute kidney injury (AKI) after major non-cardiac surgery carries substantial morbidity, yet early intraoperative risk stratification remains difficult. In this retrospective cohort study, we propose SynerT, a waveform-only hybrid temporal backbone that combines a…
Time Series Foundation Models (TSFMs) promise a paradigm shift toward zero-shot forecasting by eliminating task-specific training. However, existing works often overlook trade-offs between predictive accuracy and probabilistic calibration. This paper presents a benchmark study…
Graph Incremental Learning has garnered increasing attention as dynamic graph data continues to emerge across diverse fields. Conventional approaches primarily address catastrophic forgetting by preserving node-related knowledge through replay or distillation techniques;…