Pulse · msn.com
msn.com ·
Anthropic introduces FlashProve, a new open-source tool to verify AI models
Anthropic's FlashProve is a new open-source tool that proves which AI generated your response while keeping the company's code safe.
Read moreThe top stories in the fields you follow, at 08:00 your time.
Anthropic's FlashProve is a new open-source tool that proves which AI generated your response while keeping the company's code safe.
Read more Pulse · basic-tutorials.com
Apple Opens Siri AI to All Developers: With the iOS 27.3 beta, developers can run their own app actions and skills. What's possible, when it's coming, and why the EU is waiting.
Read more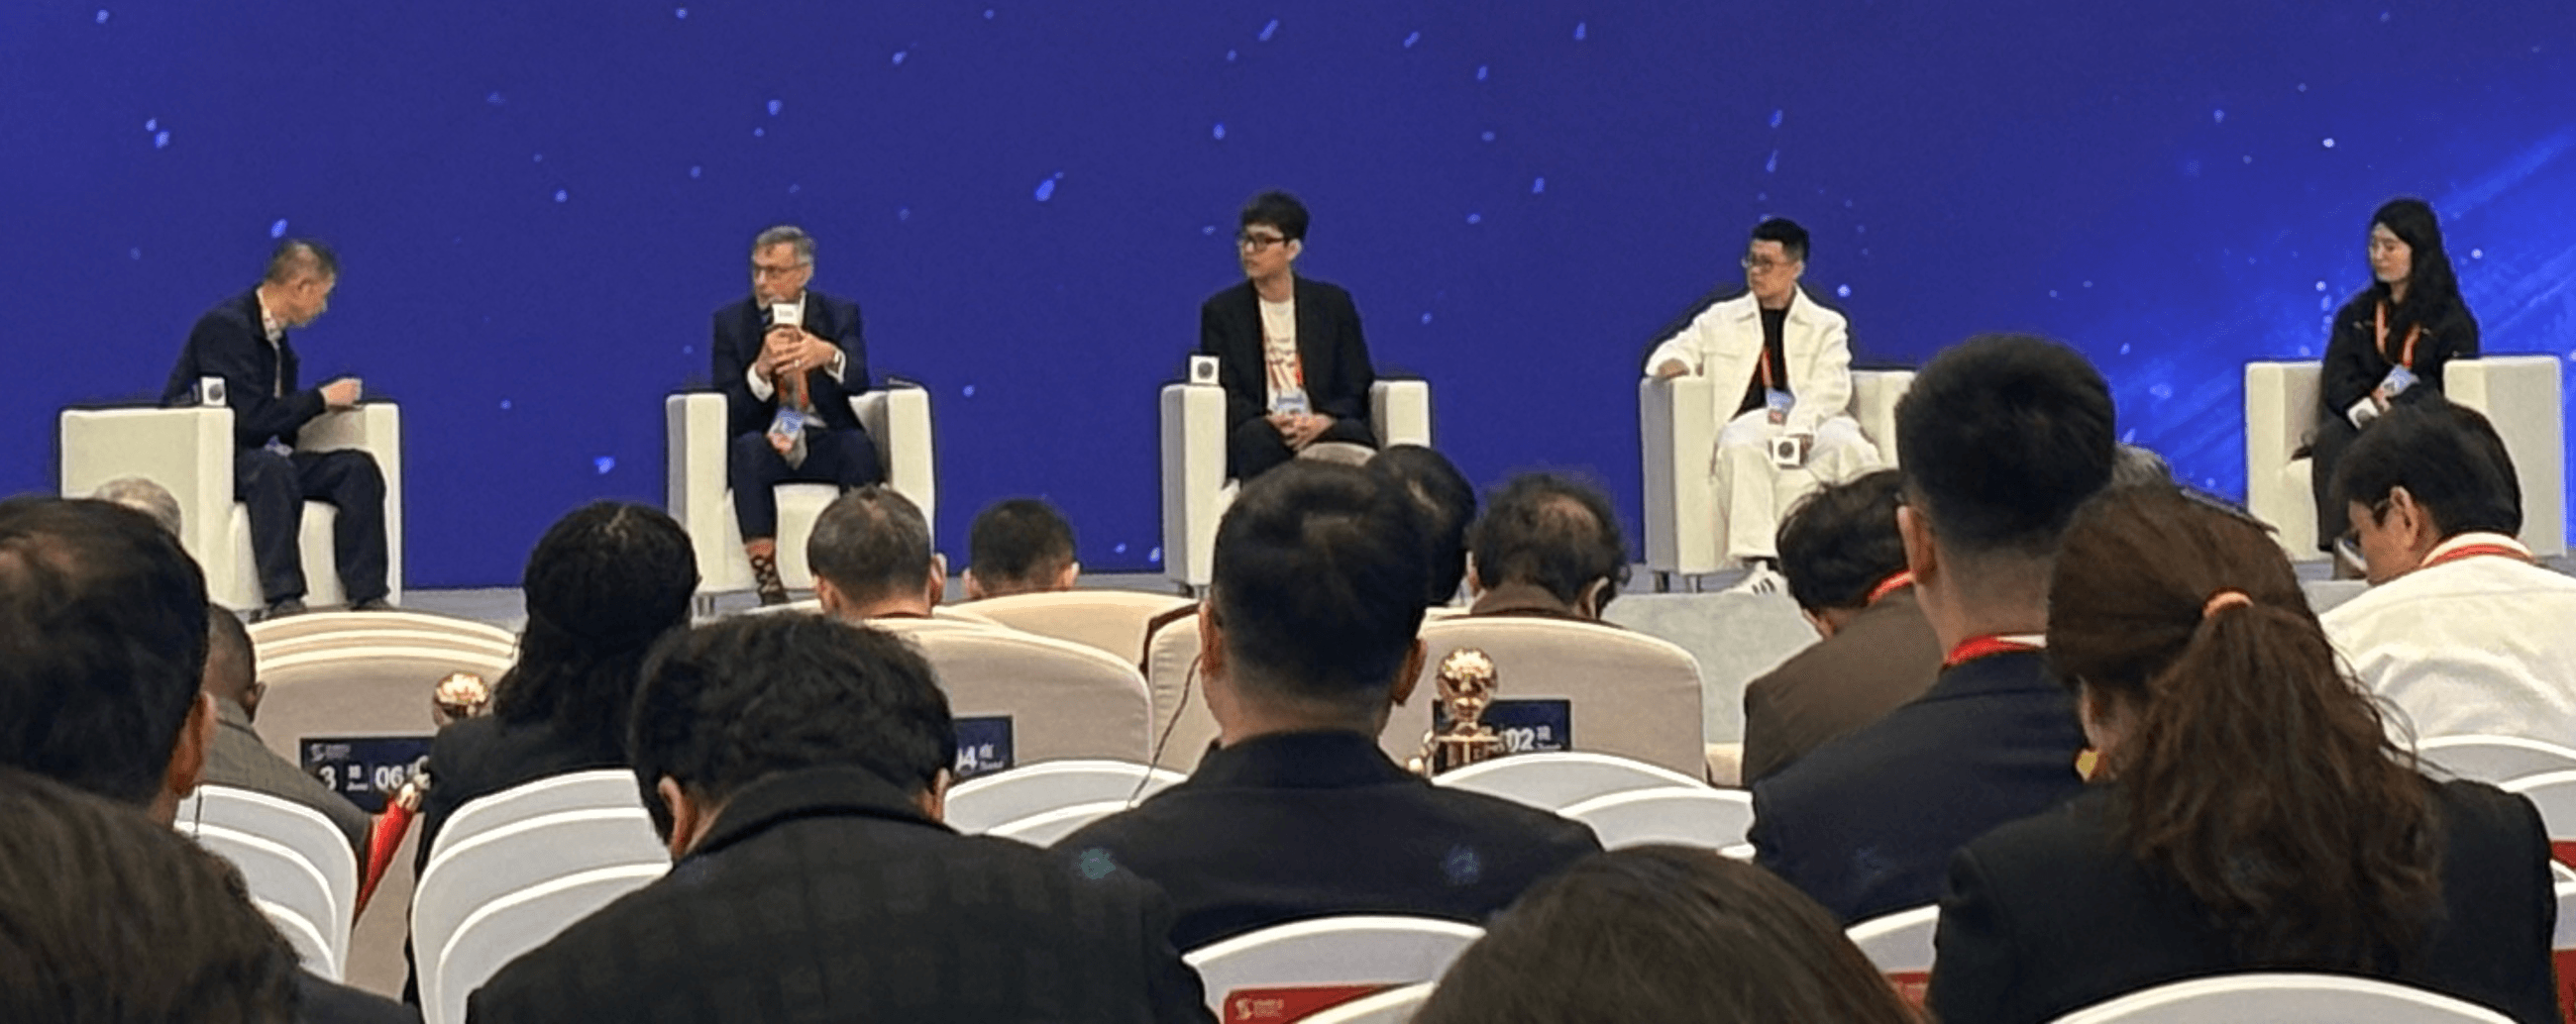 Pulse · pandaily.com
At the Wuzhen Summit, DeepSeek's Xi Gao, Qwen's Dayiheng Liu and MiniMax's Wen Feng explained why they open-source models and how irrevocable releases should be governed.
Read more Pulse · tronweekly.com
Anthropic has introduced FlashProve, an open-source cryptographic prototype designed to verify whether an artificial intelligence response was generated by the specific model claimed by its provider.
Read more Pulse · techgig.com
Y Combinator CEO Garry Tan spends up to ₹1.8 crore annually on AI tokens, with artificial intelligence agents managing parts of his daily life. These AI agents access extensive personal and professional data to assist him.
Read more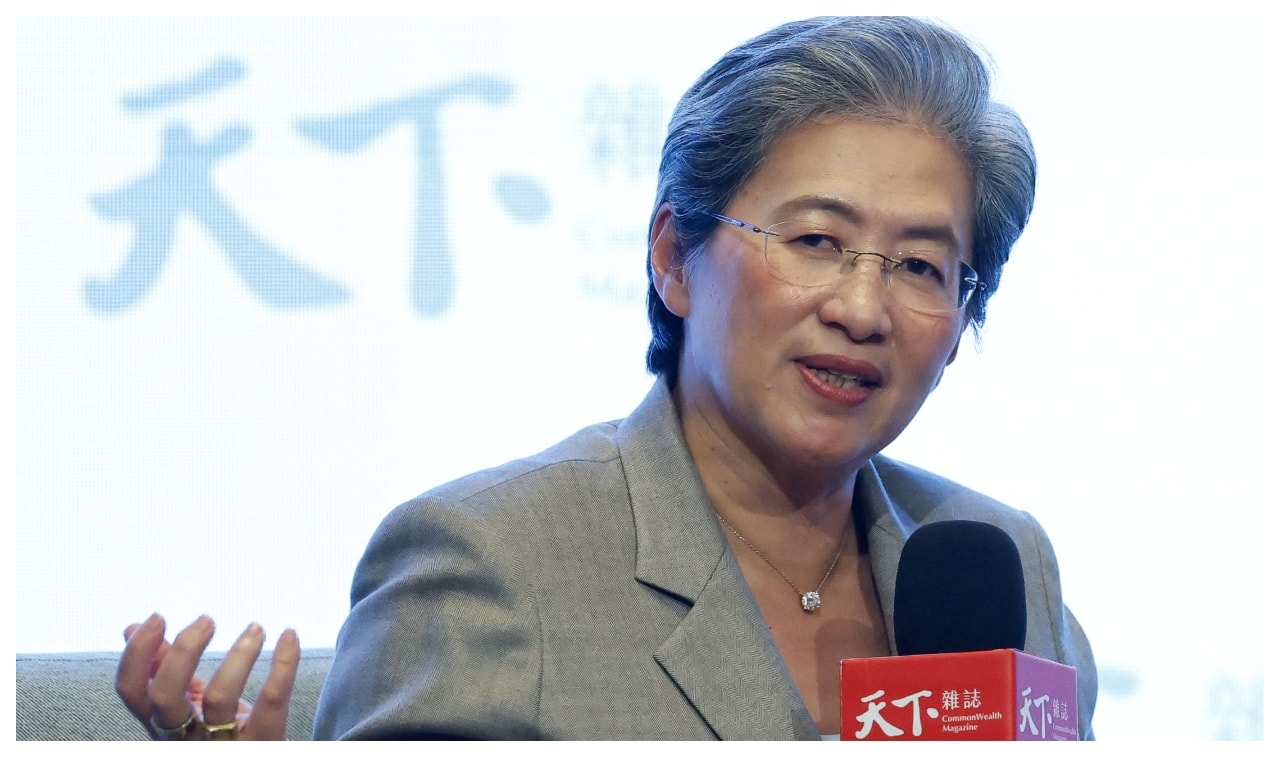 Pulse · moneycontrol.com
Fourth-quarter revenue will be $17 billion, plus or minus 3%, the chipmaker said in a statement Tuesday. That easily topped the average analyst estimate of $16.3 billion, helping send the shares up about 7% in late trading.
Read more Pulse · pymnts.com
CrowdStrike plans to make two acquisitions that will add artificial intelligence (AI) observability and automated AI security testing to the CrowdStrike
Read more Pulse · techgig.com
Soket Labs and ZenteiQ have launched indigenous artificial intelligence foundation models under the IndiaAI Mission. This initiative marks another step in India's push to build homegrown AI capabilities.
Read more Pulse · richtv.io
Binance disclosed that hackers conducted a multi-stage operation that leveraged fake job interviews to gain access to its internal systems and wallets. The...
Read more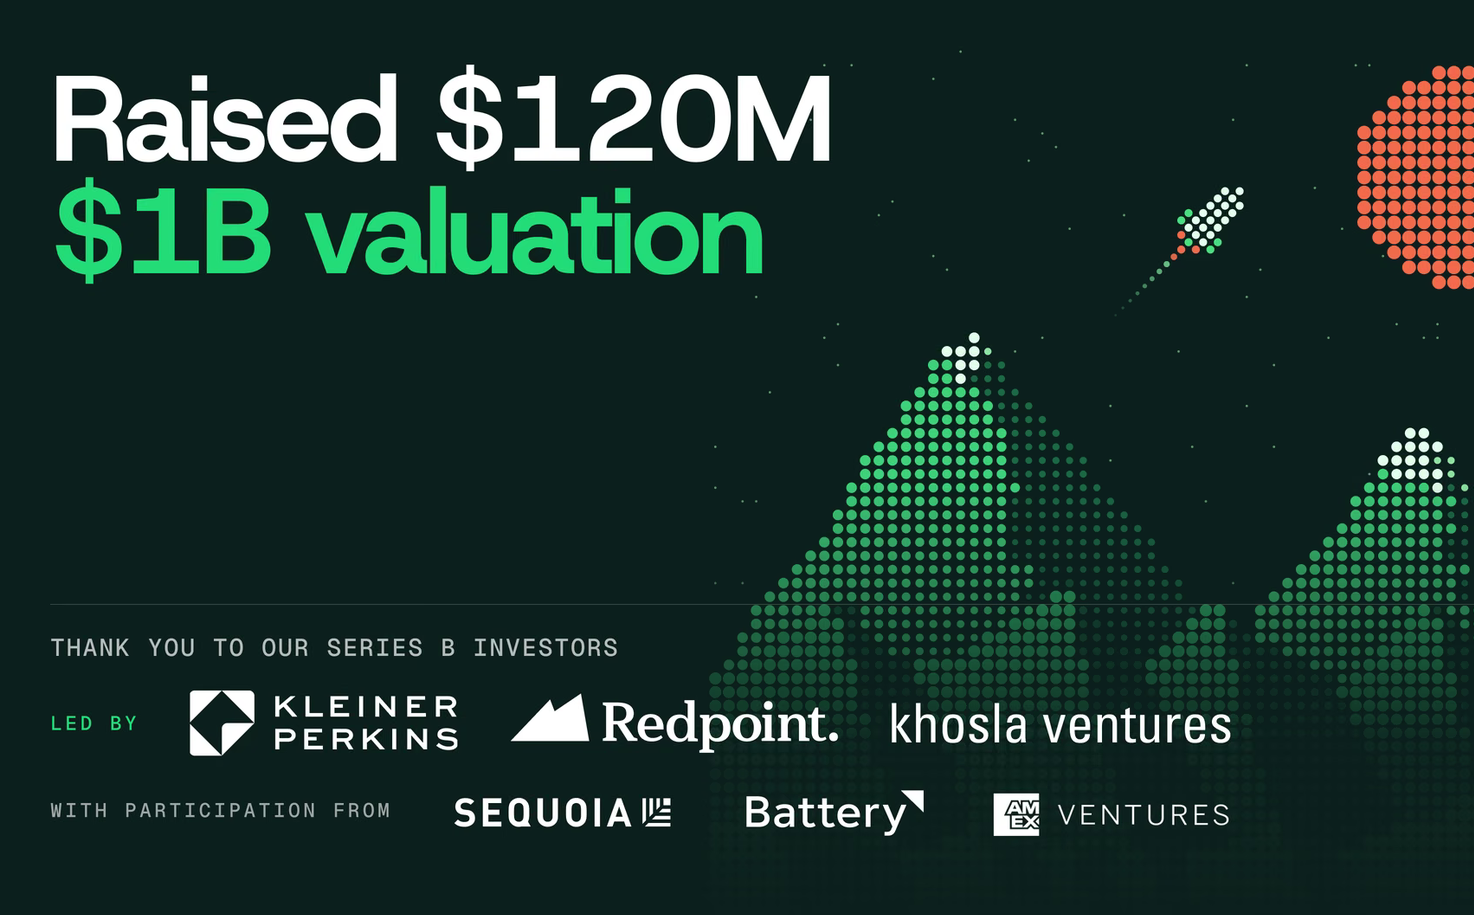 Pulse · siliconangle.com
Autonomous site reliability engineering startup Traversal bags $120M in funding at a $1B valuation - SiliconANGLE
Read moreWe study online learning with directed weakly observable feedback graphs and propose a Follow-the-Perturbed-Leader (FTPL) policy that achieves best-of-both-worlds guarantee with nearly linear expected time complexity. To preserve the simple structure of FTPL, we develop a novel graph-based loss estimator that combines forced exploration, conditional geometric resampling and adaptive learning rates with surrogate probabilities. Our policy achieves $\tilde{\mathcal{O}}(δ_*^{1/3} T^{2/3})$ regret for adversarial regimes as well as $\tilde{\mathcal{O}}(δ_* \log T / Δ_{\min}^2)$ regret for stochastic regimes, where $δ_*$ and $Δ$, respectively, denote the fractional weak domination number and the suboptimality gap. These results show that refined guarantees for problems with minimax regret of $Θ(T^{2/3})$ can be obtained through appropriately designed adaptive learning rates and loss estimators without sacrificing the simplicity of FTPL.
Camera object detectors lose recall in rain, fog, snow and sand, and the confidence threshold at which a detector is deployed decides how many objects it misses and how many false alarms it raises. We study how a frozen detector should make this decision in adverse weather. We first reproduce SeqCRC, a conformal object detector whose first step calibrates the confidence threshold by conformal risk control (CRC), and use that step, calibrated separately in each weather condition, as our baseline. With YOLOv8x it keeps the held-out miss fraction within a 20% budget in every DAWN weather bin, where a single global threshold fails in fog, but the false alarms it needs are an output rather than a choice: from 1.6 to 117 per image across DAWN and BDD100K conditions. We then propose a calibrated trade-off dial. One setting, $λ$, the number of false alarms accepted to avoid one missed object, selects the expected-cost-optimal decision rule: either one score threshold, or a per-detection rule that keeps a box when its calibrated probability of being a real object, estimated by gradient-boosted trees from the detector's own per-box outputs, is at least $1/(1+λ)$. F-score preferences map…
In-image machine translation (IIMT) replaces text in an image with its translation while preserving the surrounding visual context. Existing task-specific models achieve convincing performance but require massive paired training images before and after translation. As advanced text-to-image (T2I) models have reached a practically usable level of multilingual text generation, we argue that this capability can be transferred to IIMT and present FlowTranslator. It is a training-free IIMT framework that first employs an OCR model and an LLM to generate the translation prompt, which is injected into the T2I-based diffusion model. To optimize the accurate and natural generation of translated text, we introduce two trajectory controls: Region Coupling Release (RCR) partially decorrelates target-branch noise inside the text region early in the trajectory, while Coupling Expansion (CE) amplifies the emerging edit displacement mid-trajectory. Under the EasyOCR read-back protocol, FlowTranslator achieves average PRIM BLEU and COMET scores of 20.6 and 57.2, respectively, substantially outperforming the strong training-based baseline UniTranslator. On the more challenging and realistic…
Answering geographic queries over Earth observation (EO) archives requires solving a joint retrieval-and-derivation problem under strict spatiotemporal constraints. Existing LLM agents fail to ground observation items or suffer from search-space explosion. We propose OSGR, a two-stage framework that factorizes this search into offline symbolic concept deduction and online Relation-Conditioned Grounding. OSGR leverages an offline Observation-Support Graph to deduce valid target-to-result support paths at the concept level, and applies spatiotemporal compatibility kernels to instantiate grounded observation-item sets. On Earth-Bench and DisasterM3-Reason, OSGR improves GPT-4o accuracy from 49.3\% to 63.7\% while reducing the execution-step ratio from 2.9 to 2.5.
Long-range 3D object detection remains difficult for autonomous vehicles because LiDAR returns become sparse and camera evidence weakens with distance, while automotive radar keeps returning measurements far beyond both. We present CLOCs-R, an extension of the CLOCs candidate-level fusion framework that adds radar evidence to camera-LiDAR rescoring. Radar returns are accumulated over several sweeps, compensated for ego-motion, and associated with each pre-NMS 3D candidate through a range-dependent gate. Compact features summarizing support, Doppler speed and spread, range residual, and offset are then appended to every camera-LiDAR pair before a lightweight fusion network rescores the candidates. We first verify that our fusion implementation reproduces CLOCs on KITTI. We then evaluate on the daytime clear-weather subset of the aiMotive dataset, reporting distance-binned metrics out to 200 m with frozen SECOND and Cascade R-CNN detectors. Camera-LiDAR CLOCs improves on SECOND up to 50 m but degrades beyond it. A residual scoring variant, introduced post hoc, corrects SECOND's score instead of replacing it and recovers most of this loss. Radar consistently improves BEV AP at 30-50…
Vision-language agents that crop and zoom are trained with rewards that credit a successful tool call, yet a successful call does not show that the model needed to look or used the pixels it received. On our cold-start checkpoint only 10% to 12% of visual calls were both needed…
Triage in the emergency department (ED) is a sequential decision process that unfolds turn by turn. Existing evaluations of large language models (LLMs) for triage use completed retrospective records and report performance close to that of physicians. We implement a methodology…
In this paper, a comparative review of different hybrid models for short-term forecasting of building thermal demand is carried out. Particularly, the assessment tackles the comparison of data-driven models enhanced with other state-of-the-art techniques. At the first step, the…
Large vision-language models (VLMs) enable recognition beyond a fixed class set, but their computational demands prevent them from running on many edge devices. Cloud offload makes this capability accessible, but sending every image consumes scarce bandwidth and communication…