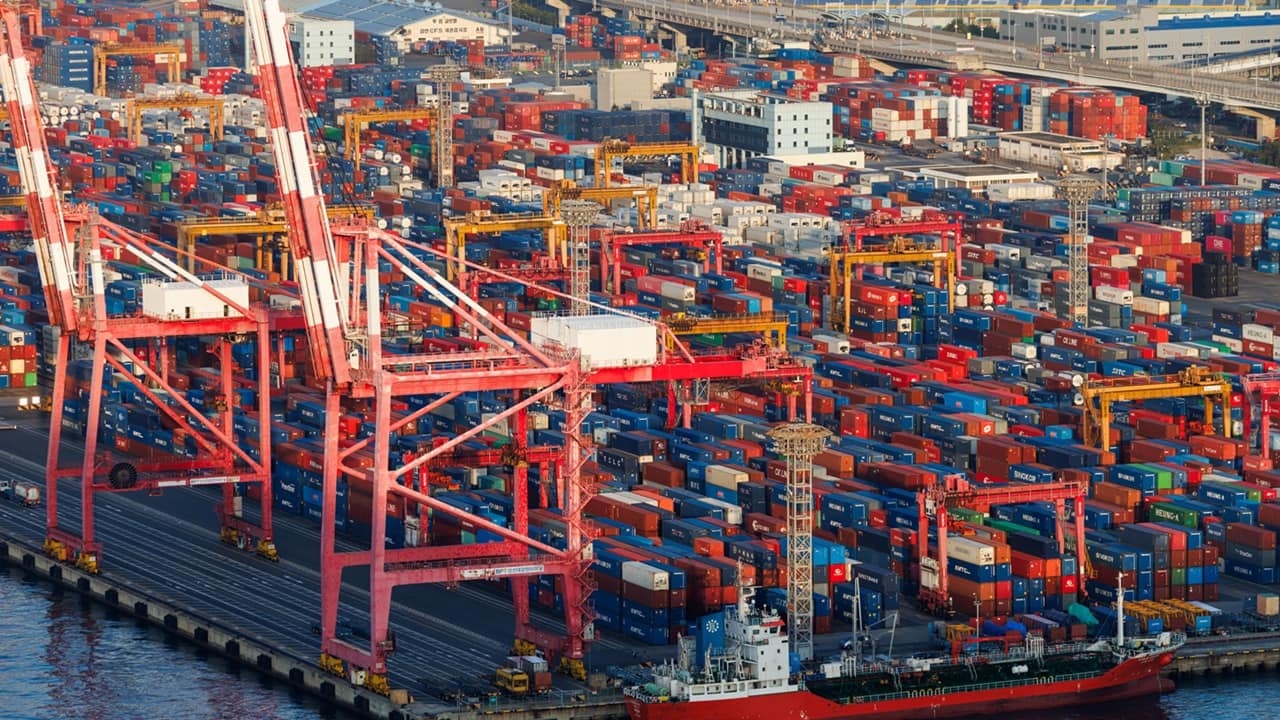
Exports adjusted for working-day differences climbed 76.1% from a year earlier, according to the Ministry of Trade, Industry and Resources data released Sunday
AI drug discovery single-cell datasets now have their first systematic secretome training layer: Parse Biosciences and Nomic Bio launched Cascade, pairing 100 million RNA-seq profiles with matched 1,000-protein secretome reads across 150,000-plus immune perturbation conditions, backed by GSK,
The Spring ecosystem announced the first release candidates for 17 projects, including Spring Boot 4.2.0-RC1 and Spring Framework 7.1.0-RC1. These updates deliver bug fixes, dependency upgrades, and new features across various components. Developers can expect improved performance and enhanced functionalities in these latest releases.
MediaTek (TWSE: 2454) expects to capture about 20% of the global market for application-specific integrated circuits (ASICs) used in AI accelerators next year, Focus Taiwan reported on October 31. Chief Executive Officer Rick Tsai told investors the custom chip should bring in about $16bn in sales in 2027,
Data attribution methods for Language Models (LMs) are typically evaluated using downstream tasks like fact retrieval. However, existing evaluations vary multiple dataset properties simultaneously, making it impossible to isolate exactly why an attribution algorithm fails. To diagnose these failures, we explore the design space of LLM data attribution, with a primary focus on evaluation. We introduce the Controlled Attribution Benchmark (CATT) for fact tracing, in which we fine-tune LLMs on entirely fictitious knowledge, providing unambiguous ground truth for attribution. This synthetic setup allows us to systematically alter one dataset configuration at a time, such as document redundancy and lexical distractors. With this configurable evaluation, we demonstrate that redundancy and distractors consistently degrade attribution performance. Rather than proposing a new estimator, we examine two design choices that are underexplored: the loss used to compute gradients and how per-token attribution scores are aggregated into a document score. We find that the true causal evidence within a training document is highly localized, but standard methods dilute this evidence into noise by…
The prompt is built automatically as "" * num_pages + "Multi page parsing.", and each page is encoded as one global view (base mode). The output contains one per input page, in the same order as image_files.
Federated learning lets multiple parties train a shared model without pooling their data, but a client with far less data than the others can end up poorly served even when the group's average accuracy looks fine. We ask whether the choice of pretrained backbone affects this…
Non-verbal vocalizations (NVVs) carry important paralinguistic information but are often omitted by conventional automatic speech recognition (ASR) systems. The ISCSLP NVVSpeech Challenge requires joint transcription of lexical content and 16 NVV categories under limited and…
Deep learning has advanced automated electrocardiogram (ECG) diagnosis, but the field's most accurate models, foundation models pretrained on millions of recordings, are not decision-pathway auditable: a clinician cannot trace a diagnosis to a physiological pathway or intervene…
Reinforcement Learning with Verifiable Rewards (RLVR) is expanding from tasks with well-defined correctness signals, such as mathematics and code, toward multifaceted quality requirements specified by multi-dimensional rubrics. Since policy optimization consumes one scalar per…