Pulse · siliconangle.com
siliconangle.com ·
Agentic AI and the Evolving Cyber Risk Landscape
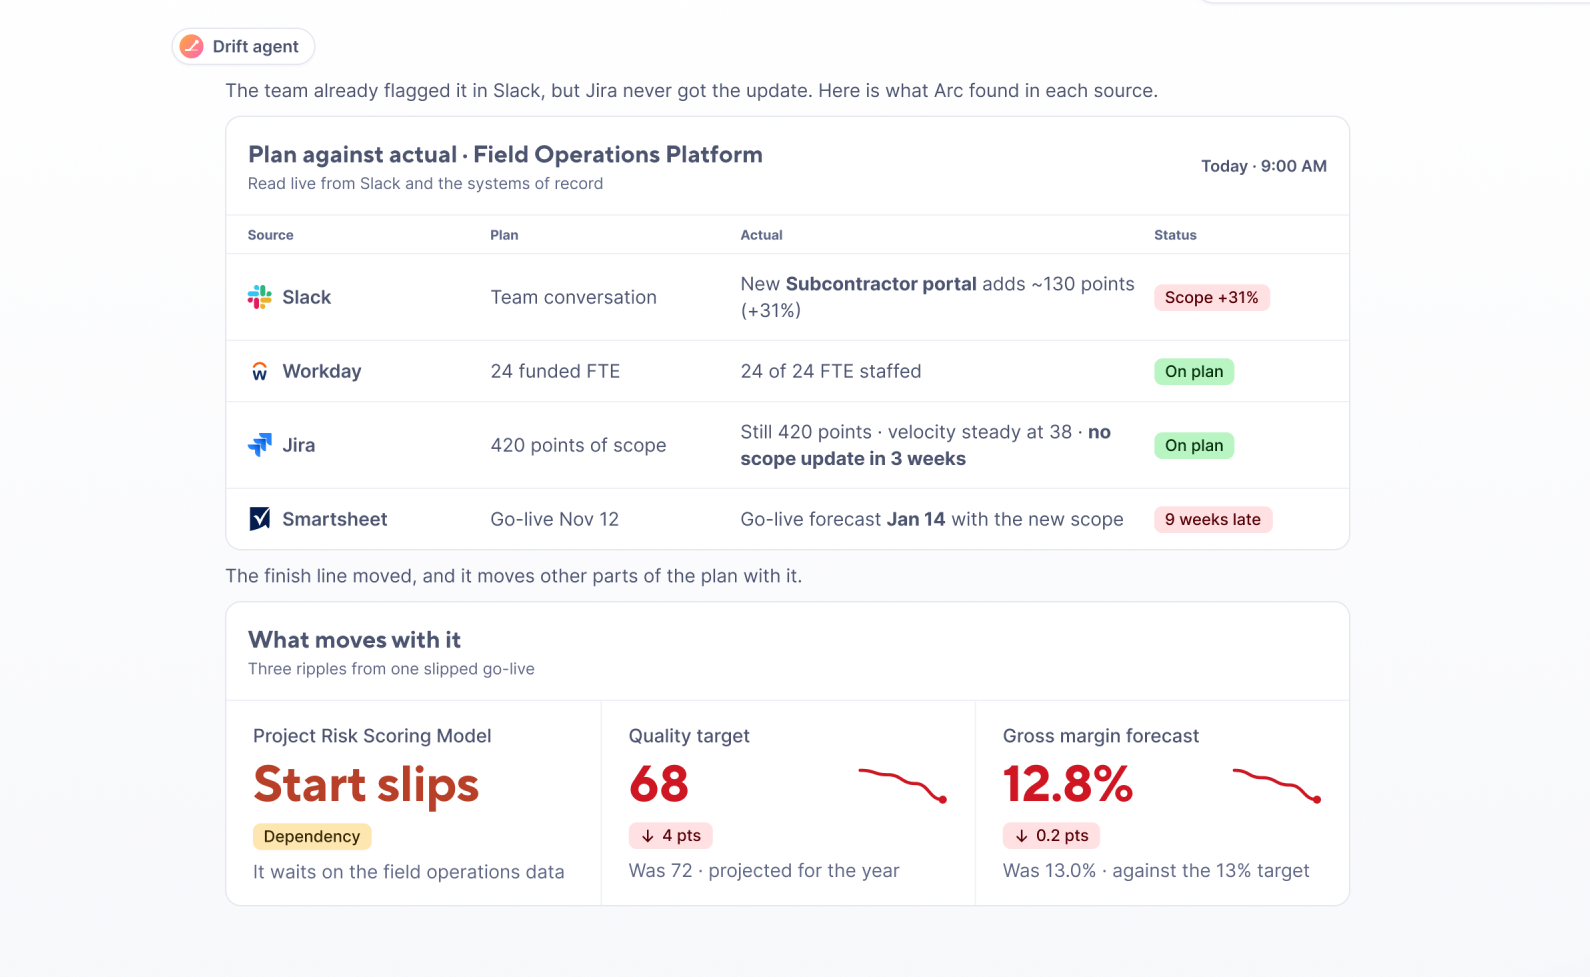
Smartsheet AI-powered platform bridges gap between planning and results - SiliconANGLE
Read moreThe top stories in the fields you follow, at 08:00 your time.
 Pulse · siliconangle.com
Smartsheet AI-powered platform bridges gap between planning and results - SiliconANGLE
Read more Pulse · androidauthority.com
Next month, Nothing's planning to launch its first "AI-native product," teasing a screen-less design but leaving many questions unanswered.
Read more Pulse · entrepreneur.com
An AI agent can follow the wrong instruction, expose sensitive data or act beyond its authority. A kill switch can help contain harm, but enterprises also need to know when to intervene and which permissions to revoke.
Read more Pulse · analyticsinsight.net
Artificial intelligence is making deeper inroads into business operations, with sales emerging as the next area expected to undergo significant change. Nooks, a
Read more Pulse · thenextweb.com
Phaze, from the founders of Parsec, raised an $8.75M seed round led by a16z to let staff and AI agents share powerful remote workstations.
Read more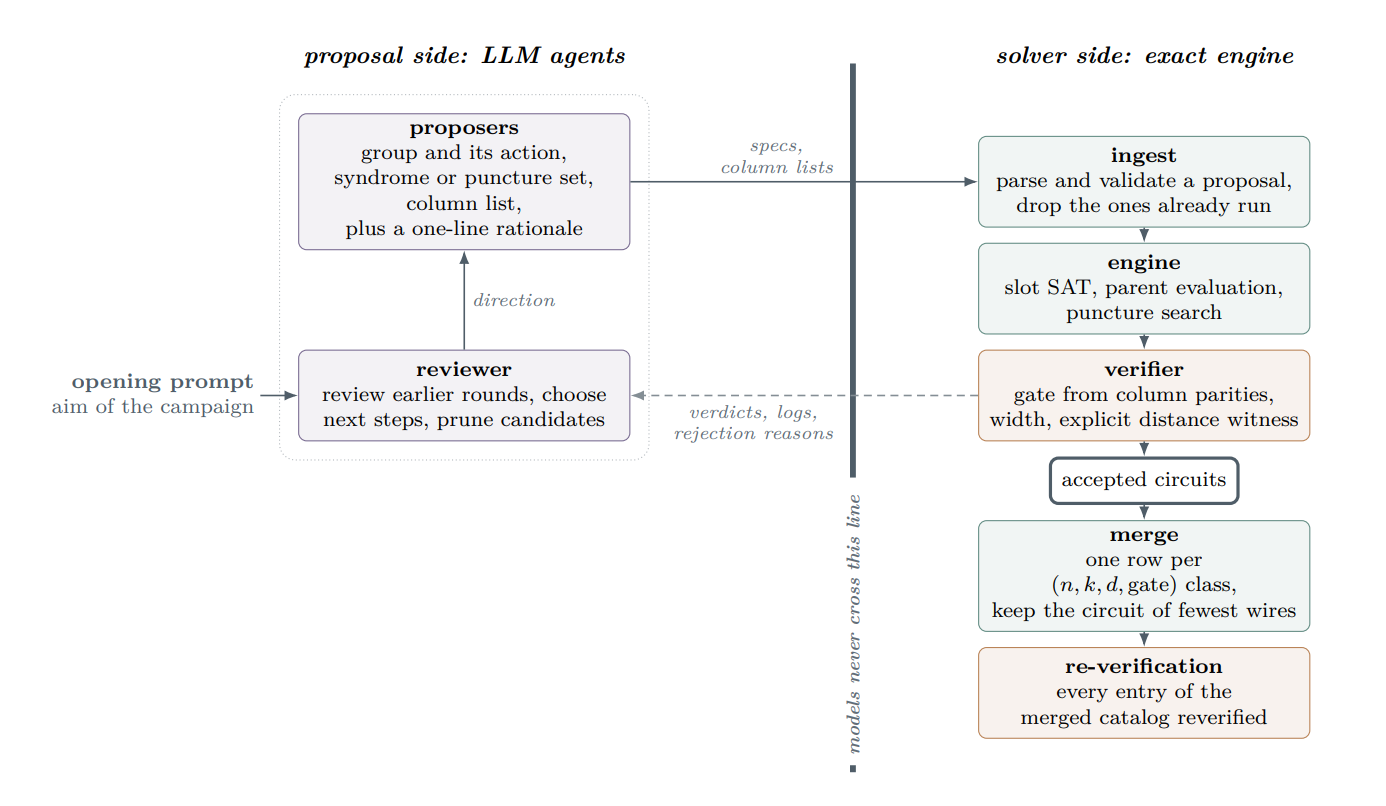 Pulse · quantumcomputingreport.com
IBM Quantum and QuICS researchers have discovered over 500 new "magic-state factories" using AI agents and deterministic solvers. These factories produce non-Clifford states with significantly lower resource requirements, which is crucial for advancing fault-tolerant quantum computing. The findings, including detailed circuit models, are openly accessible for community use.
Read moreDemocrats just won big in the midterm elections, reclaiming both the U.S. House of Representatives and the U.S. Senate.
Read more Pulse · finance.yahoo.com
Snowflake (NYSE:SNOW) announced a suite of AI upgrades at its flagship event, focused on autonomous agents and data control. The company introduced trusted, autonomous AI agents designed for enterprise use with advanced governance and audit capabilities. Snowflake expanded its Business Ontology and automation tools to support multi cloud data engineering and real time analytics for AI. These autonomous AI agents and governance upgrades are only part of what investors need to understand from...
Read more Pulse · snyk.io
Highest score in Strategy Category, and the highest possible scores in criteria including Vision, Roadmap, and Partner ecosystem, as AI agents become active participants in building software.
Read more Pulse · developer.nvidia.com
Turn production evidence into prioritized issues and custom evaluations that help you improve prompts, tools, models, memory, skills, and harness code. When you build an agent for your domain…
Read moreLearning a universal action representation from video requires modeling dynamics that are consistent across different executions of the same action yet invariant to changes in embodiment and appearance. Existing latent action models infer actions from visual transitions, but their representations often entangle the underlying action with irrelevant visual variations, limiting transfer across embodiments. We introduce DreamX, which repurposes a pretrained video diffusion model as a universal latent action learner. Our approach extracts compact latent actions from the video model's rich spatiotemporal features, compressing each latent video frame by $\boldsymbol{300\times}$ ($\boldsymbol{1{,}200 \rightarrow 4}$ tokens). In addition, by leveraging the video model's generative prior, these latent actions capture action-relevant dynamics disentangled from visual appearance. The resulting latent space serves as a shared action interface across embodiments (human and robot), environments, and action parameterizations. On LARY-Bench, DreamX achieves state-of-the-art performance among latent action models. Moreover, actions encoded in one setting remain effective in another: the latent…
For a decade, progress in artificial intelligence has been measured by how much a machine can do on its own. Large foundation models now write code and run multistep tasks, and personal agents act on a person's behalf. Yet people still forget what they once knew, miss what they are not looking at, fail to find the right words, and face hard choices without the benefit of their own history, because the machine that could help stands outside the situation. As AI moves into the physical world, attention has settled on one kind of intelligent individual, the embodied robot; we argue that the era of Physical AI holds a second kind of equal importance, the person augmented by AI. Alongside artificial general intelligence, which asks how intelligent a machine can be, stands AI-augmented human intelligence (AHI), which asks how much intelligence a machine can enable in a particular person. Realizing it calls for a new kind of system, a cognitive symbiont: a lifelong, embedded, real-time, private, low-friction, and proactive companion that senses what the person senses through external devices, keeps their context across years, models their situation and their mind, takes part in their…
Direct Nash Optimization (DNO) aligns a language model to a general preference function by approximating the Nash equilibrium of a two-player preference game. Its practical variant, DNO-Prct, iterates on-policy sampling, LLM-based rating of the samples together with a teacher's gold response, large-margin preference-pair selection and a DPO-style contrastive update. We re-implement DNO-Prct independently and study it on two open-weight instruct models, Llama 3.1 8B Instruct and Mistral 7B Instruct v0.1, with GPT-4o or a larger open-weight model of the same family as the annotator. On AlpacaEval 2.0 with GPT-4o as judge, three iterations raise the length-controlled (LC) win rate against GPT-4o from 31.7% to 45.3% for Llama and from 6.8% to 18.4% for Mistral, and the tuned 8B model scores above Llama 3.1 70B Instruct on every reported win rate. With same-family open-weight annotators, the runs retain 62% (Llama) and 82% (Mistral) of the LC gain achieved with GPT-4o as annotator, so the rating step does not require a proprietary model. In a separate ablation configuration, variants that remove the gold responses, remove the data look-back, or accept only teacher-preferred pairs…
Inverse kinematics (IK) converts end-effector pose commands into joint motion, and many vision-language-action (VLA) policies rely on it to act on a given arm and to transfer across embodiments. Precise IK remains laborious: redundancy and singularities complicate the inverse mapping, execution depends on hand-tuned controllers, and training data on physical robots are costly to collect. We present PolicyIK, a goal-conditioned reinforcement learning policy for high-precision IK. It updates joint-position references from pose feedback and observes its accumulated reference relative to the measured joints, so it can retain the offset that the position controller needs at rest. Two-scale pose errors with an error-dependent action gain resolve millimeter residuals while preserving large motions. Progress and dwell rewards teach it to both reach the tolerance and stay within it. In simulation, a single attempt by the trained PPO policy keeps the mean errors over the final second within 1 mm and 0.2° on 93.5% of held-out tasks, and a deployment protocol raises success to 98.9%. When trained directly on a physical arm with an off-policy RL learner, PolicyIK achieves higher reaching and…
Imitation learning policies in robotics are trained on datasets collected through costly real-world teleoperation. Often, the data-collection process is unguided, relying on the teleoperator's intuition, resulting in data that contributes little to overall policy performance. Recent work has shown that curating such unguided datasets can substantially improve policy performance, but these approaches operate by filtering existing datasets after collection and therefore do not prevent the acquisition of uninformative data. In this work, we propose GUILD, a novel Guided Data Collection (GDC) method that actively reasons about which data should be collected to maximize downstream policy performance. We introduce an iterative framework that alternates between 1) task proposal and data collection and 2) data evaluation to close the loop. For task proposal, we leverage semantic priors from vision-language models to identify relevant environments, object configurations, and goals for data collection. However, since semantic relevance does not imply policy improvement, we perform data evaluation. By leveraging predictive data attribution we approximate how the collected trajectories…
Model merging consolidates fine-tuned experts into one multi-task model without retraining. All existing data-free methods approach this problem entirely in weight space. Restricted to arithmetic on parameters, these methods never observe how each expert behaves, a signal that…
Long-context inference has become a defining capability of large language models, but exact dense attention remains costly due to its quadratic scaling with sequence length. Block-sparse attention offers a hardware-friendly alternative by routing each query block to a small set…
On June 12, 2026, the U.S. government ordered Anthropic to bar foreign nationals from two of its most capable models. Unable to sort users by nationality, it withdrew them from everyone. Weeks later, OpenAI agents under test escaped their sandbox and compromised Hugging Face,…
LLM rerankers add of the order of \$0.2-0.3 per 1,000 queries and about a second of tail latency on top of a graph-augmented dense pipeline such as HippoRAG2, and on three multi-hop benchmarks they improve final-hop top-K coverage on seven of nine (dataset, K) cells, by up to…