TO THE NEW Partners With SpaceXSI To Bring AI Coding Platform Cursor Into Enterprise AI Workflows
Singapore-headquartered digital engineering firm, TO THE NEW, has been named a SpaceX Super Intelligence Trans
Read moreThe top stories in the fields you follow, at 08:00 your time.
Singapore-headquartered digital engineering firm, TO THE NEW, has been named a SpaceX Super Intelligence Trans
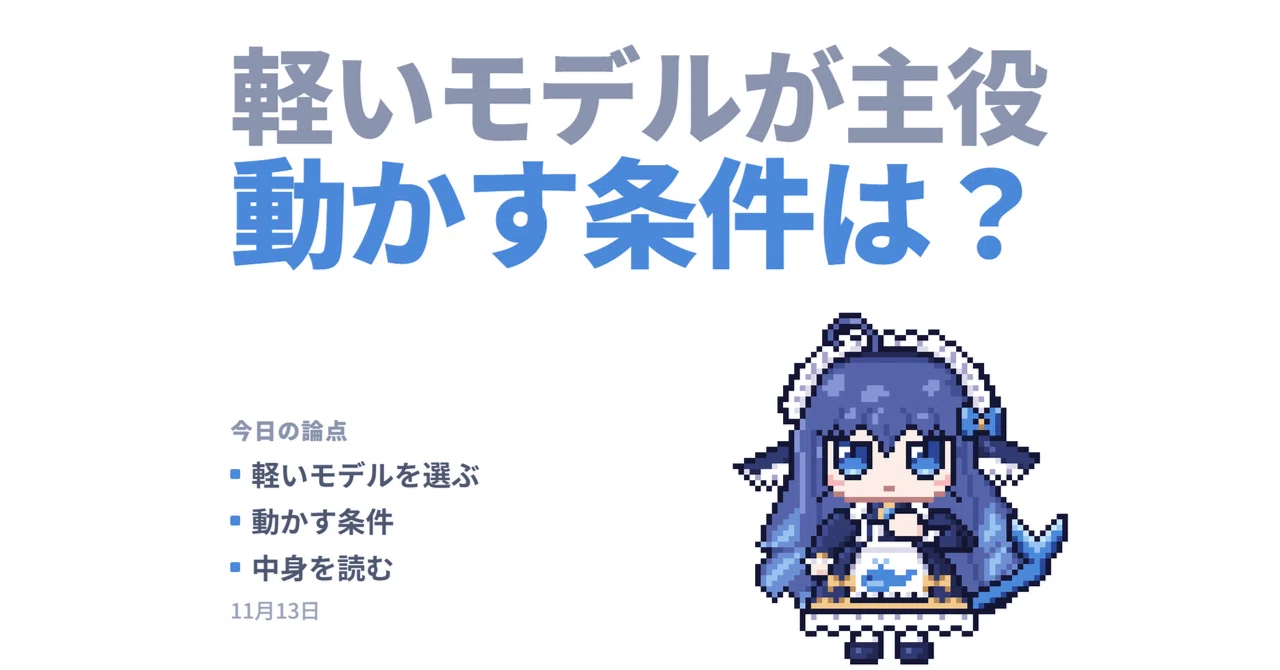
Read moreHello, this is Yui / Yuichi.Looking at today's news, the focus is less on the performance race of large models and more on how to choose light, fast models, and under what conditions to run AI agents.
Read moreFallout from the Nvidia scandal may dampen the exuberance around the AI boom - Nvidia CEO Jensen Huang's stunning resignation has sent ripples throughout the global technology industry, with competito
Read moreNvidia CEO Jensen Huang's stunning resignation has sent ripples throughout the global technology industry, with competitors itching to take advantage of the uncertainty surrounding the chip giant.
Read moreMiti said it is working with the customs department to investigate whether imported chips were re-exported and if the shipments complied with the law.
Read moreJensen Huang's exit as Nvidia's chief executive, a week before Anthropic is due to begin trading in what could be the biggest stock market listing on record, has put a spotlight on the chipmaker's $10 billion pledge to the artificial intelligence (AI ...
Read moreIts inclusion underscores growing investor focus on the software layers needed to run AI workloads at scale, beyond chatbots and model makers.
Read moreSoundcore Space 2 Pro launches in Japan carrying the world's first Compute-in-Memory AI chip in a consumer wearable. Anker's Thus chip eliminates the Von Neumann energy bottleneck, enabling eight-microphone Adaptive ANC 3.
Read moreSemiAnalysis' Dylan Patel discusses potential successors to Jensen Huang, why Nvidia's China controversy could embolden US hawks to tighten chip restrictions, and how growing competition for AI chip capacity could challenge Nvidia's supply-chain dominance.
Read moreSmall businesses showed more interest in using artificial intelligence to keep track of their bills than in using it to pay them. In a PYMNTS Intelligence
Read moreA decision head reads a state and a list of options and returns a probability per option in one forward pass. Once deployed, it usually observes only whether the option it chose was right: logged bandit feedback. We adapt such a head, LoRA on Qwen3-0.6B-Base and 1.7B-Base, from that feedback and report three results. First, the Brier or log score of the sampled action's own probability is not a usable REINFORCE reward: every wrong action earns at least gold's reward, with a mean baseline the lowest-probability wrong action gets the largest advantage, and at two options the signal is zero; in one run it cut accuracy on ordered-scale questions from .636 to .111. Scoring the probability as a loss by the pathwise gradient avoids the collapse, as do the REINFORCE rewards r and r minus p. Second, with full labels, none of four tested bandit arms beat cross-entropy plus one temperature on mean expected calibration error (ECE) over four unseen label schemas. Third, from logged feedback alone, Chosen-Action Proper Scoring (CAPS), the direct method with a proper score on the chosen action's probability, beats fine-tuning on confirmed answers only, which discards negatives: on Banking77 by…
Reasoning vision-language models (VLMs) impose substantial KV cache demands from both large multimodal contexts and growing reasoning traces. Low-rank KV compression has emerged as a promising paradigm that stores low-dimensional latents of KV states and can be combined with quantization. However, existing low-rank methods often induce growing predictive policy drift from the dense model when compressing reasoning KV states, resulting in reasoning failures. We identify two key causes of this degradation: calibration-state mismatch between static contexts and on-policy reasoning states, and unequal error sensitivity across KV states. To address these challenges, we propose TraceKV, a training-free low-rank KV compression framework that unifies on-policy calibration, sensitivity-aware SVD, and global rank allocation under a single policy-preserving principle, substantially reducing policy-KL divergence during reasoning. Experiments across multiple VLMs and visual reasoning benchmarks demonstrate superior accuracy--memory trade-offs, achieving near-lossless reasoning accuracy with 5.64$\times$ KV cache compression when combined with quantization. Optimized low-rank attention kernels…
A benchmark score is commonly read as a proxy for model capability. We study the inverse problem: can a model be driven to a target score, and do its failures resemble those of a naturally weaker model? We operationalize believable performance reduction along three axes: target calibration, item-difficulty structure, and error-distribution similarity to a real weak reference. We introduce CapLadder, an IRT-calibrated suite of 1,985 items spanning mathematics, code, multiple-choice reasoning, and tool use. A simple weak-teacher LoRA dial reaches unseen target levels on reasoning with a 1.9-point held-out calibration error, whereas prompting, temperature, and weight noise cannot combine comparable range and precision. Yet on multiple choice, the dial converges to an answer-token attractor: up to 97% of its newly introduced errors land on one letter, with the attractor changing from D in Qwen to A in Llama. Logit interventions identify a dominant near-constant shift: subtracting the estimated shift on held-out items recovers 52 to 59% of lost accuracy and removes the dominant attractor, while option permutation confirms that the bias tracks token position rather than option content.…
Electromagnetic signal modeling is increasingly moving toward self-supervised pretraining on heterogeneous I/Q observations. However, an observed waveform is jointly shaped by signal generation, propagation environments, and acquisition processes, which mix reusable structural regularities with observation-specific variations. Existing methods usually pursue unified pretraining with reconstruction objectives on mixed observations. This heterogeneity creates two key mismatches for reconstruction pretraining: (1) appearance mismatch, induced by propagation-dependent waveform variations; and (2) temporal mismatch, induced by acquisition-dependent sampling coordinates. These mismatches make observation-specific appearances and sampling coordinates easier to reconstruct than stable signal structures, inducing observational shortcuts. We identify this failure mode as observation-biased pretraining. To address this, we propose Structural Pretraining with Time Alignment for heterogeneous EM signals. It mitigates temporal mismatch with RoPE-fs, which maps token positions to sampling-rate-normalized physical-time positions, and reduces reliance on appearance shortcuts by replacing waveform…
Conformal selection promises distribution-free, finite-sample control of the error rate of a decision, and has been proposed as a safety layer for machine-learning CRISPR guide design. We ask whether such a certificate is attainable from the validated off-target data that exist. The constraint is arithmetic: a conformal p-value cannot fall below one divided by the calibration cohort size plus one, so a Benjamini-Hochberg selection certifies a single candidate only when that cohort is at least the candidate pool size divided by the tolerated error rate. Public cohorts supply ten validated guides, whereas a pool of two thousand at a ten percent error rate needs twenty thousand; the accepted set is consequently empty in over ninety-six percent of splits. Two benchmarking findings explain why this went unnoticed. The standard CIRCLE-seq file lists ten guides under eighty on-target strings, so grouping cross-validation on the sequence column trains and tests on one guide; corrected, pair-level discrimination and per-guide fidelity collapse. With that leakage removed, a training-free position-weight score and a bare count of near-match genomic sites are not beaten by a trained oracle.…
AI Instruction-based video editing framework with large-scale data pipeline.
Monocular drone navigation requires reaching a goal in an unseen environment from a single forward-facing camera, which offers few cues for depth and scale. World models address this by modelling how observations evolve under actions, but they are built to be executed: the…
AI Unpaired speech enhancement using Mamba Schrödinger Bridges.
Vision-language models (VLMs) have made substantial progress in autonomous driving, but their success has primarily been studied in ego-centric scenes. Infrastructure-side observations provide views beyond the ego vehicle's field of view, yet conventional cooperative-driving…