Kimi K3.1 Pro is an open-weight, natively multimodal agentic model, and our most capable 3T-class model to date. Post-trained from Kimi K3 with large-scale joint reinforcement learning across hundreds of downstream domains, it is the first model in the K3.1 series. With a…
Token Pass credit now applies automatically to included model usage through AI Gateway , whether a request authenticates with an API key, OIDC token, or fx login. No dedicated Token Pass API key is required, though you can still create one from the dashboard or the CLI for keys…
The Nasdaq Composite ended sharply lower on Thursday, notching its deepest one-day drop in 19 months and confirming it was in a correction, as chipmakers sank on fears of tougher AI regulation after Democrats won control of the US Congress.
Among the many gifts that Donald Trump bequeathed to Democrats ahead of the midterms was allowing them the exclusive political use of the AI backlash. Now that Democrats have decisively won control of Congress,
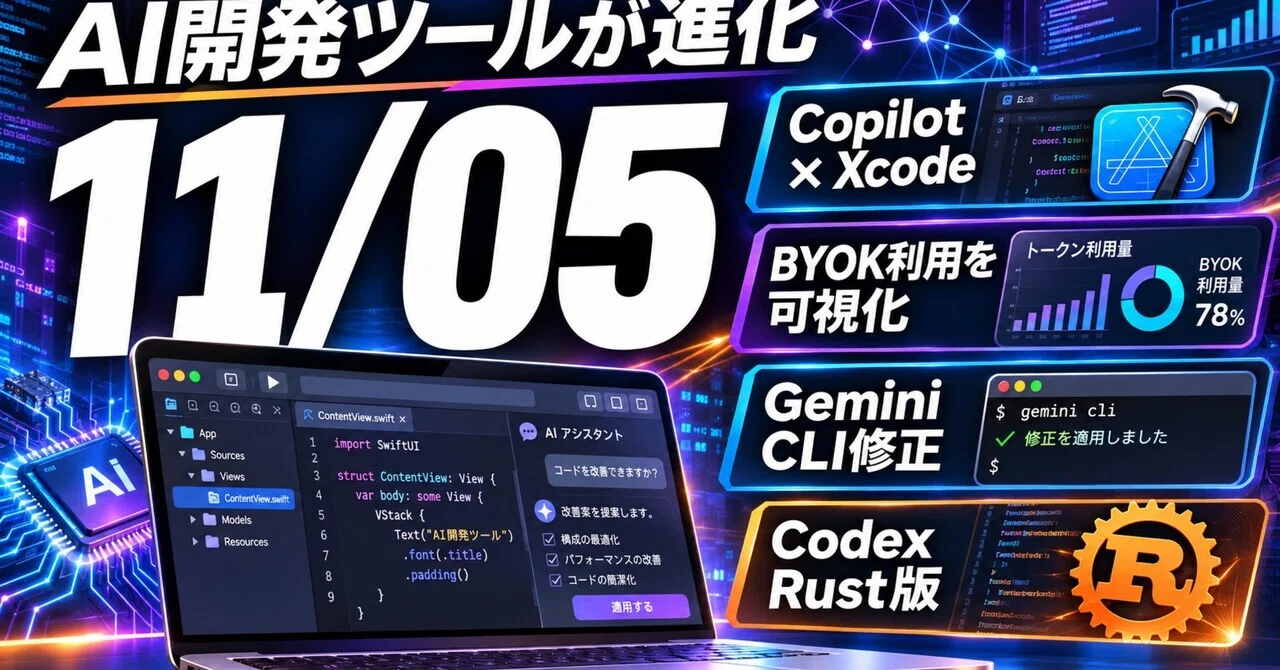
GitHub Copilot now supports Xcode coding assistanceStarting with Xcode 27.3 beta, you can now use Copilot within the standard Xcode coding assistant. It can be connected via the settings screen and is available for all Copilot plans.
3D reconstruction from a lengthy video stream input poses a dilemma for feed-forward reconstruction models (FFRMs), that a whole-stream inference context cannot be retained under limited GPU memory.Recent studies seek to resolve this problem via a trade-off between the…
In a decentralized multi-robot team under partial observability, the fact that decides a robot's next action is often visible only to a teammate. Existing decentralized methods communicate kinematic information, such as position or planned trajectory, which cannot convey what…
Blind image deconvolution (BID) is a prominent research topic in the field of imaging sciences, given its significant practical applications. Most existing model-based BID methods focus on natural images, incorporating appropriate prior knowledge about both the underlying image…
The visual modality, i.e., images, plays a key role in multi-modal entity alignment (MMEA). Existing approaches often directly fuse the image with other modalities to align different entities. Although simple, such strategies overlook the potential noise in the images and their…