Pulse · taekim.substack.com
taekim.substack.com ·
Sound Ecosystem & Scenario Innovation: 7 RISC-V China Summit Sub-Forums Uncover New AI Opportunities
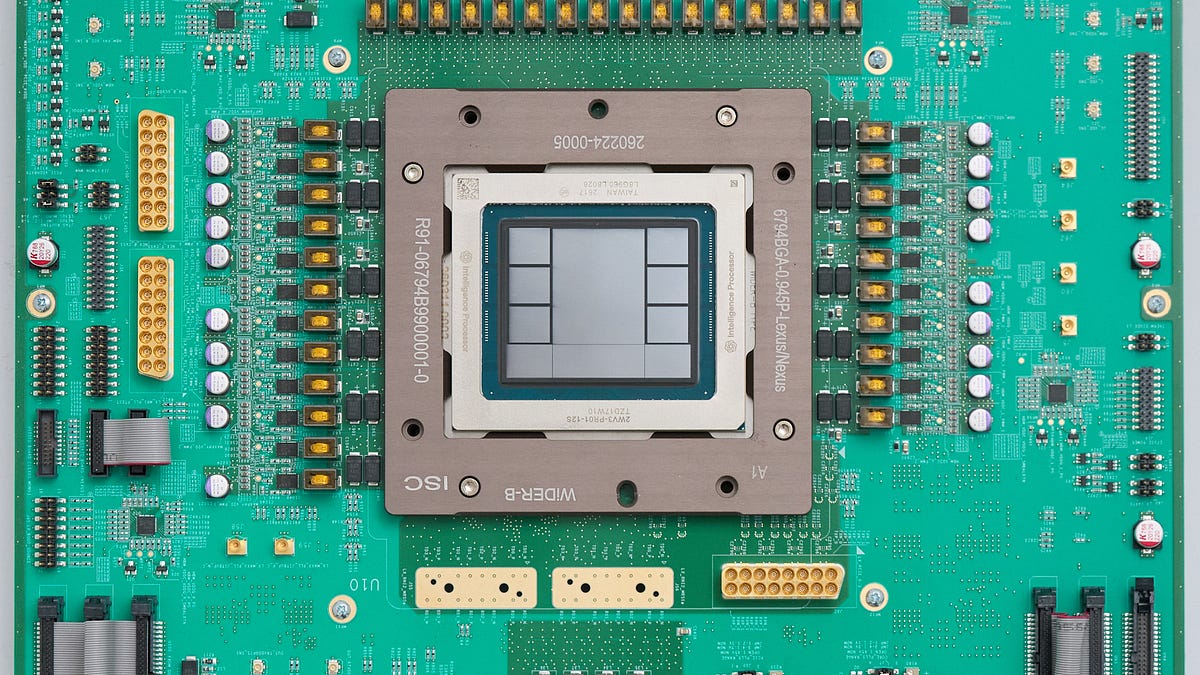
OpenAI’s spicy chip looks good.
Read moreThe top stories in the fields you follow, at 06:00 your time.
OpenAI’s spicy chip looks good.
Read morePost-training is crucial for improving text-to-image models, yet existing pipelines typically rely on manually curated training data and fixed training distributions. We introduce APT (Agentic Post-Training), a fully automated framework that adaptively post-trains a base model…
We introduce LensErase, a general-purpose mask-based Erase Anything foundation model designed to cover a broad spectrum of real-world erase scenarios. LensErase supports diverse objects, visual text, watermarks, associated visual effects, multiple-object removal, and a wide…
Effective collaboration among large language model (LLM) agents in multi-agent systems requires sharing relevant evidence, requesting missing information, and incorporating teammates' contributions into decisions. Training these behaviors is challenging because final task…
DeepSeek-V4.1-Flash-1017 is a minor update to DeepSeek-V4.1-Flash, delivering substantial improvements across reasoning, coding, agentic tasks, and visual benchmarks. Alongside these gains, the model reduces task execution time and output length, enabling users to complete…
Model · diffusion-single-file · 1.3M downloads · 338 likes
Agents built on vision language models (VLMs) now compete with learned policies on robot manipulation leaderboards. We ask how far a coding agent can go when it controls a robot instead of a computer, and where it stops. Our system, HexaShell, keeps the harness thin: it only…
Can large language model (LLM) agents deliver expert-level operations research (OR) solutions directly from original client materials, without prior expert reformulation? Existing OR benchmarks typically begin with self-contained descriptions or predefined optimization tasks,…
Flint is Recursive’s mixture-of-experts language model for coding agents, with 39.8 billion total parameters and approximately 2.5 billion active per token. It is designed to investigate codebases, fix bugs, implement features, and write tests.