Pulse · korben.info
Latest in AI and developer tools
The top stories in the fields you follow, at 08:00 your time.
 Pulse · fool.com
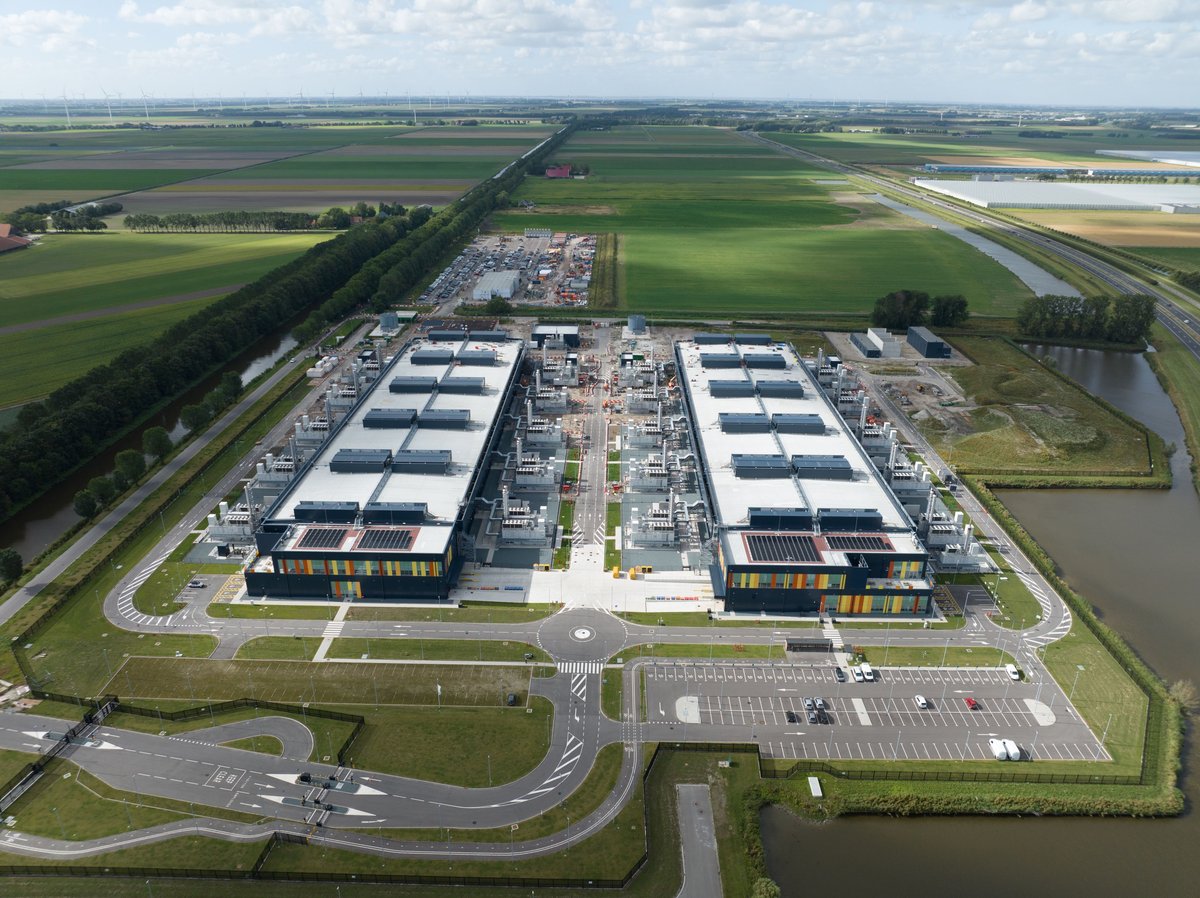
When most people think about investing in artificial intelligence, they think of chip stocks, hyperscalers, or the upcoming IPOs of the massive companies that produce AI models. But building AI capacity requires much more than the processors and models that millions of people use in their daily lives.
Read more Pulse · startupfortune.com
Qwen4 nears launch as Alibaba faces doubts over its open-source pledge after Qwen 3.7 shipped closed following a leadership exodus at the Qwen team.
Read moreAmazon is investing in cross-border logistics, faster delivery networks and localized marketplace features across Europe, Asia, and Latin America, positioning it to capitalize on areas where digital retail penetration remains comparatively low.
Read more Pulse · blockchain.news
Google recapped October AI launches led by Gemini 4 Argon and Gemini 4 Carbon, alongside Genie 4, SynthID expansion and other research updates.
Read more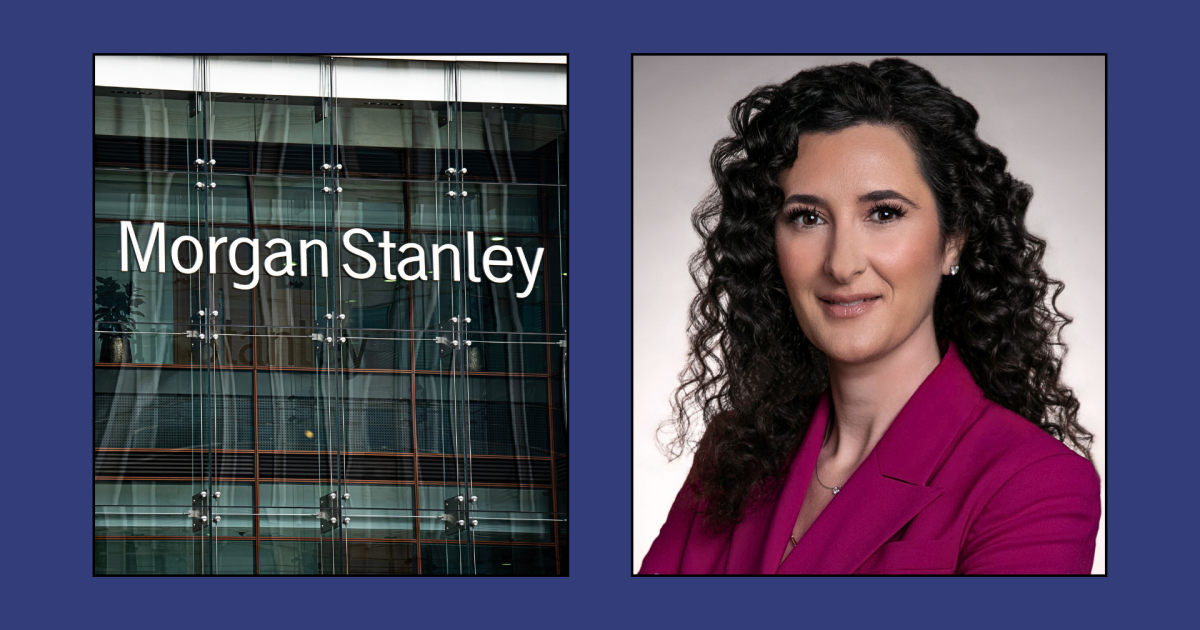 Pulse · financial-planning.com
Morgan Stanley's head of AI for its wealth management division said advisors have so far 'curated' nearly 50,000 AI agents. It's a hands-on approach not common at large wealth managers.
Read moreFrom answering sales emails to monitoring finances, entrepreneurs are building businesses with AI teams instead of traditional employees.
Read more Pulse · cryptobriefing.com
Arena.ai's Agent Arena found top AI agents process about 93 input tokens per output token, making prompt caching the key driver of costs.
Read more Pulse · felloai.com
ChatGPT Plus is $20 a month and Pro is $100, $200 or $500. Compare the models, usage tiers and Codex access, and see when upgrading is a waste of money.
Read moreRadiologists' visual attention can supervise medical image learning, but how reader panel composition affects its value remains untested. We evaluated GazeRIB (Gaze-guided Radiologist-Informed Blackout), which masks unviewed regions during training and uses unmasked images at inference. Eight experts repeatedly read the same 80 chest X-rays (CXRs). We compared individual readers with three-, five- and eight-reader panels across seven architectures and 10 seeds, evaluating 910 models on a separate 2,897-CXR cohort for four-class severity prediction. Every panel improved macro F1 over the no-gaze baseline by 5.33-7.47 percentage points (pp; Bonferroni-adjusted p < 0.007); no individual reader reached significance on this endpoint. Three readers captured 73-80% of the eight-reader gain in macro F1, the area under the receiver-operating-characteristic curve (ROC-AUC) and the area under the precision-recall curve (AU-PRC). On external validation without retraining, all four panels improved ROC-AUC on SIIM-FISABIO-RSNA by +1.93 to +4.24 pp (p <= 0.004); on MIMIC-Eye no panel differed significantly from baseline, whereas the single-reader average declined (-1.40 pp, p = 0.008). Reader…
Unified Multimodal Models (UMMs) achieve remarkable success on diverse multimodal understanding and generation tasks, yet they still struggle to effectively leverage language-based chain-of-thought reasoning for image generation. As a result, existing reasoning-augmented UMMs often fail to inherit the test-time scaling and fine-grained controllability observed in large language models. We attribute this failure to a fundamental modality mismatch: reasoning is performed in a discrete token space, whereas image generation operates in a continuous space. To bridge this gap, we introduce a Latent Reasoning framework in Continuous space (LARC), which alleviates the token-level bottleneck by reasoning over continuous hidden states. Specifically, the training framework consists of two stages: (i) curriculum supervised fine-tuning (SFT), and (ii) information-gain reinforcement learning (RL). First, the curriculum SFT stage gradually converts token-level reasoning into latent reasoning. Subsequently, the information-gain RL stage self-evolves latent reasoning without ground truth supervision. Experiments across diverse text-to-image generation benchmarks show that LARC consistently…
Decision models such as Jev have emerged as a highly promising paradigm for LLM agent systems, providing lightweight and reliable categorical reasoning for rapid System One execution. However, existing generation-oriented inference engines fail to support these workloads effectively, suffering from severe prefix recomputation overheads or distorted output probabilities. To address this challenge, we propose Flide, an efficient and exact inference engine that decouples the logical tree structure of a decision request from its physical execution within a single flattened token stream. Through ForkAttention, Flide navigates request dependencies using GPU-resident indices across both standard attention and recurrent Gated DeltaNet layers, guaranteeing in exact arithmetic that every query branch evaluates identically to an isolated forward pass. By expressing branch topologies directly in GPU-resident metadata, Flide accommodates diverse request mixtures with a compact set of pre-recorded execution graphs while enabling expanding agent histories to resume from checkpoints saved in earlier passes. Extensive evaluations on public hybrid and decision models demonstrate that Flide answers…
Agentic workflows are increasingly shifting towards long-horizon tasks, such as open-ended scientific work, where models benefit from long context windows. However, at ultra-long context (above 1M tokens), full attention is prohibitively expensive. A promising approach is sparse attention, in which a dedicated indexer selects a subset of keys for the attention. Yet current methods of indexing either still have quadratic cost in context size or lose accuracy at ultra-long context scale. We address this with Latent Sparse Attention (LSA), an efficient attention method that maintains accuracy at ultra-long context. In LSA, keys are hierarchically clustered in a learned latent space, and queries score the hierarchy of clusters instead of scoring every key, making prefill, decode and training faster at long context. We propose two variants, Distilled-LSA (D-LSA), which can be applied to pre-trained models via distillation, and Native-LSA (N-LSA), which is trained natively on the next-token loss alone. On GLM-5.3-FLASH (QWEN-3.8-27B) at 10M tokens, D-LSA speeds up one attention layer by 22.7x (72.4x) in prefill and 4.6x (42.5x) in decode over its original sparse attention (full…
Planning with world models enables test-time adaptation for embodied agents, offering superior generalization over direct policy learning. However, long-horizon tasks remain hindered by cumulative errors and search complexity. Existing hierarchical methods often use rigid macro-actions or latent skills, leading to brittle representations and limited fine-grained control. We introduce ID-WM (Implicit Dynamics World Models), a hierarchical world model that decouples state-space reachability from local control. Our framework utilizes a high-level model to sample feasible transitions across the state manifold and a low-level world model as an inverse dynamics solver to ground these transitions into precise actions. This allows the planner to identify reachable subgoals without being constrained by low-level execution details. By prioritizing local physical feasibility over global behavioral patterns, ID-WM synthesizes novel long-horizon plans from short segments, transcending the specific behavioral modes seen during training. We demonstrate its effectiveness across three navigation and manipulation suites, achieving a 38.5% improvement over state-of-the-art policy and…
Interpretable Transformers often perform well in domain specific settings but lose effectiveness beyond that. Achieving ViT-like broad applicability requires models with consistent performance across domains. Recent works on Interpretable Transformers, INTR and Prompt-CAM, were…
AI research agents can propose, execute, and improve programs that solve machine learning tasks. However, executing each candidate program requires training and evaluating ML models, limiting how many candidates an agent can explore at each step. We introduce MLE-World, a world…
Variational inference with normalizing flows provides a flexible posterior approximation for Bayesian model calibration, but struggles when the posterior has several modes separated by regions of low probability mass. We study this behavior in a two-parameter twin experiment…
In finance, the answer that matters is usually the current one: prices, rates, and disclosures hold only as of a given day, so retrieving up-to-date facts is a core capability of a financial agent. Yet most financial benchmarks overlook timeliness. They fix each answer at…