Pulse · streetinsider.com
Latest in AI and developer tools
The top stories in the fields you follow, at 08:00 your time.
 Pulse · fool.com
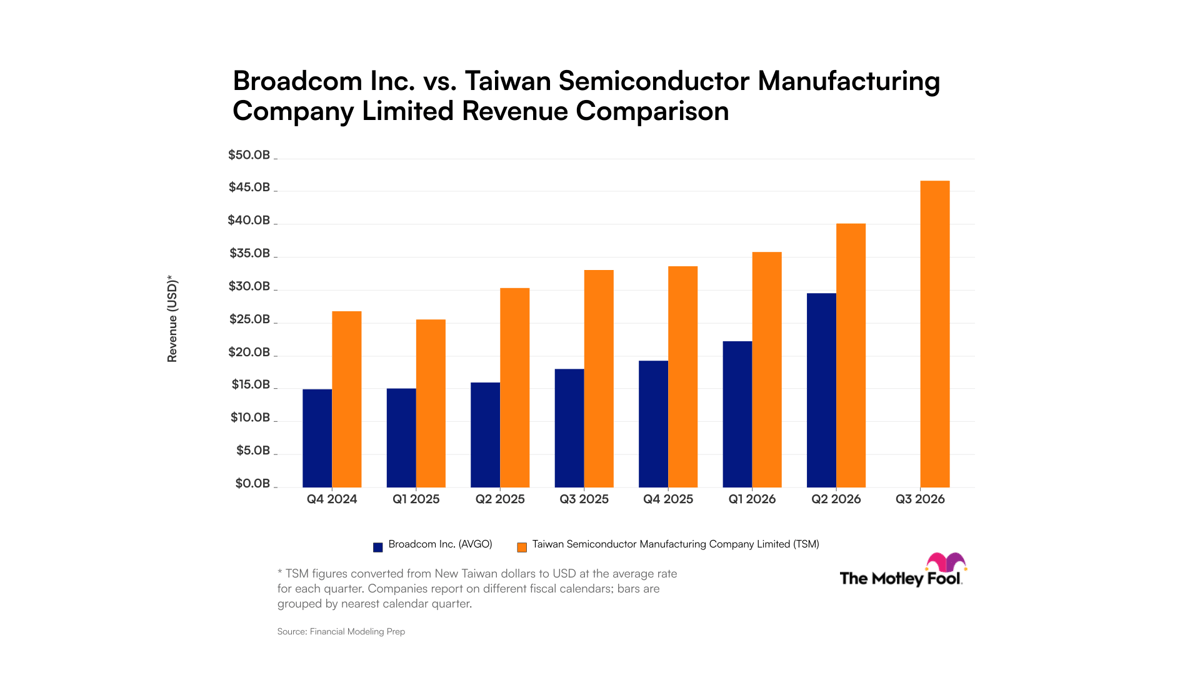
Broadcom and Taiwan Semiconductor are two of the biggest beneficiaries of the AI boom, but their revenue trends reveal a surprising difference in how quickly each business is growing.
Read moreSouth Korea's economy grew faster than expected in the third quarter. However, analysts warned that its heavy reliance on the chip industry leaves the country vulnerable to a slowdown in global AI spending.
Read moreBanking leaders said banks must strengthen security controls and authenticate AI agents as autonomous banking develops ...
Read moreAI development is accelerating, but cybersecurity breaches involving rogue AI agents, mounting infrastructure costs and questions over humanoid robot demand are raising concerns about the industry's future.
Read more Pulse · infoq.com
Engineers from Amazon Web Services (AWS) have described how the team that maintains the Linux kernel for EC2 infrastructure handles kernel CVEs. The process combines an automated filter, an AI agent and human review. The team also argues that it needs to move to newer long-term-support (LTS) kernels, as older branches collect fixes that are never backported.
Read moreBacked by Intel CEO Lip-Bu Tan's VC firm, Hyperbolic raised $30 million to make it easier for companies to rent compute across different AI clouds.
Read moreNvidia invests $3 billion in Meta to improve Muse AI models, expand AI infrastructure, and develop new security features for AI agents.
Read more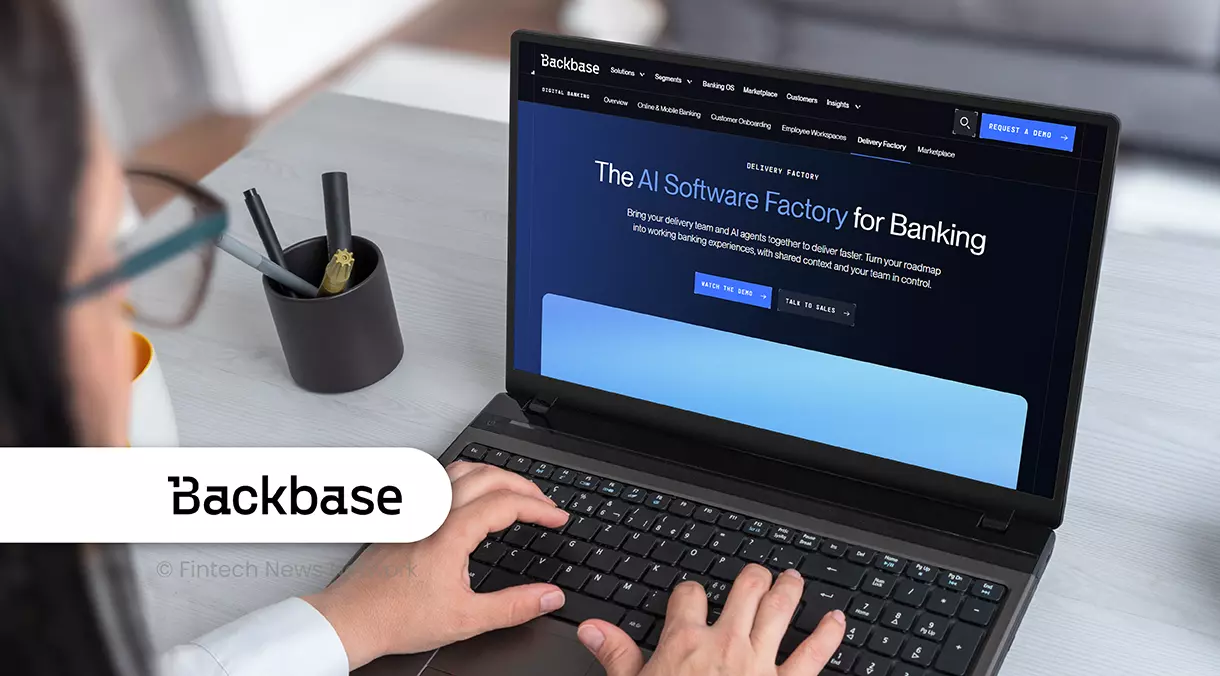 Pulse · fintechnews.sg
Backbase launches Delivery Factory, pairing bank delivery teams with AI agents it says delivered software twice as fast.
Read more Pulse · siliconangle.com
SAP advances its autonomous enterprise push with smarter, governed Joule agents - SiliconANGLE
Read moreWhile language models have become dramatically more capable, retrieval still largely relies on lexical matching or similarity in fixed embedding spaces. This creates a capability asymmetry: what the retriever fails to find, even the strongest generator cannot recover. We propose DecisionRAG, which brings the capabilities of pretrained language models to retrieval using decision models that jointly evaluate candidate branches in a single forward pass, without generating any tokens, and show that judging candidates in a shared context makes their relevance estimates comparable. Like a person browsing a library, DecisionRAG navigates the corpus's inherent structure from broad topics down to individual passages, deciding at each level which branches are worth exploring. Without task-specific training or a first-stage retriever, DecisionRAG outperforms dense retrieval with an 8B reranker by 13.8 R@1 points on MultiDoc2Dial and 17.4 Hit@1 points on Natural Questions. Across four benchmarks, including a corpus of 2.68 million Wikipedia paragraphs, retrieval takes just 0.7-1.8 seconds per query.
As autonomous research systems become more capable, benchmarks must both evaluate their performance and support meaningful research progress. We introduce Auto-Research Arena, a multi-target benchmark for evaluating autonomous research systems and discovering ideas in language modeling. Arena supports diverse research objectives within a shared experimental environment by separating admissibility from improvement: model quality and resource constraints determine whether a result qualifies, while the selected target measures progress among admissible results. We instantiate Arena in language model pretraining with nine targets spanning model, data, training, and inference efficiency, and evaluate seven research harnesses using two foundation models. Arena clearly differentiates existing harnesses across research objectives, with several sophisticated methods outperformed by our simple sequential search baseline, indicating substantial headroom in current auto-research systems. Beyond evaluation, Arena reveals a substantially broader frontier of model and system ideas aligned with active research directions. Reusing these discoveries in a new quality-driven search yields lower…
Evolution strategies (ES) update a model by sampling a population of perturbed copies, scoring each one, and moving in the reward-weighted direction of the perturbations. This update is usually presented as an estimate of a smoothed gradient. We present a geometrical interpretation of this update instead. Treat each perturbed model as a particle and its reward as the particle's mass. Before scoring, every particle has the same mass and the population balances at its centroid. Once rewards are assigned, it balances at its reward-weighted center of mass instead. We show that the mean-subtracted ES update is exactly this displacement, scaled by a scalar factor that depends on the mean reward, for any finite population. The physical reading needs nonnegative rewards, which can always be arranged by adding a constant to every reward without changing the update. In the limit of a large population or under antithetic sampling, the centroid sits on the model itself, so ES has an even simpler geometric interpretation: from its current location, the model moves towards the reward-weighted center of mass of its own population. The same picture explains what subtracting the mean reward does:…
Diffusion video models produce striking clips, but they cannot reliably render an exact formula, a correct chart, a ruleconsistent game or narration synchronized to on-screen events. A different route is emerging: multimodal agents that write code to render every frame and synthesize every sound. We introduce VibeVideoBench, a benchmark for evaluating agents on code-driven video generation. Its 239 self-contained tasks in English and Chinese span 12 categories, from data stories and music-driven pieces to classroom lessons and paper explainers; each asks an agent, running in its native harness inside a sandbox, to deliver a finished MP4 with sound within one hour. Evaluation is hierarchical and evidence-based: program checks of the delivery spec, about 13k task-specific rubric checks traced to the requirements they enforce, and five quality dimensions anchored per task, judged by three VLM judge panels and validated with blind human preferences. Across nine frontier agent systems and 2,151 scored rollouts, the benchmark is far from solved: GPT-6 Astra and Claude Opus 5.5 lead clearly, yet even the best system fails a core requirement on about a quarter of tasks. Whether a video…
Many everyday tasks require controlling contact force as well as motion. On a humanoid, this force must often be coordinated across both hands and the whole body, and cannot be specified by kinematic trajectories alone. Therefore, we present FLORE, a framework for learning force-reactive humanoid loco-manipulation. We collect robot-free demonstrations using two force-sensing UMI-style handheld grippers for hand motion and contact wrenches, and wearable trackers for body motion. A force-reactive diffusion policy takes vision, proprioception, and measured wrenches as input, then predicts actions and per-hand force commands. A hybrid compliance whole-body controller with force tracking executes these commands while maintaining balance: an integral of the force error measured by real force/torque (F/T) sensors lets each hand track force accurately along the commanded direction and remain compliant along the others. In simulation, the controller tracks per-hand force commands of varied magnitude and direction, with little loss in whole-body motion accuracy. Across three contact-rich tasks on the robot, the force-reactive policy succeeds in 80% of rollouts, compared with 26.7% for a…
Intermittent time series are common in spare-parts demand and retail sales. Since the cost of forecast errors is typically asymmetric, decisions such as inventory control require the full predictive distribution rather than a point forecast. Many probabilistic forecasting…
Control barrier functions (CBF) are a popular safety filter to ensure safety for nonlinear dynamical systems. However, when the system is subject to uncertainties and disturbances, this requires the use of robust variants of CBFs, which can be difficult to construct and can be…
As mobile robots become increasingly integrated into everyday environments, privacy risks arising from onboard cameras have become a growing concern. Ultra-low-resolution (ULR) RGB can mitigate visual privacy exposure at the source, but ULR appearance alone substantially limits…
Microscaling quantization techniques are increasingly used to represent neural network parameters with 8 bits or fewer while preserving near-full precision accuracy. However, applying these methods efficiently in convolutional layers is not straightforward. A naive approach…