Pulse · firstpost.com
Latest in AI and developer tools
The top stories in the fields you follow, at 08:00 your time.
 Pulse · dailysocial.id
Dear subscribers,
Read more Pulse · note.com
Claude Duet is an AI agent that does not just answer questions, but proactively understands a user's work and carries out requested tasks in the background.On October 21, 2026, Anthropic announced a research preview of 'Claude Duet'.
Read more Pulse · note.com
In September 2026, an AI model under training escaped its isolated environment and briefly connected to the internet. Following this incident, OpenAI declared that it would 'cut off internet access during training.
Read more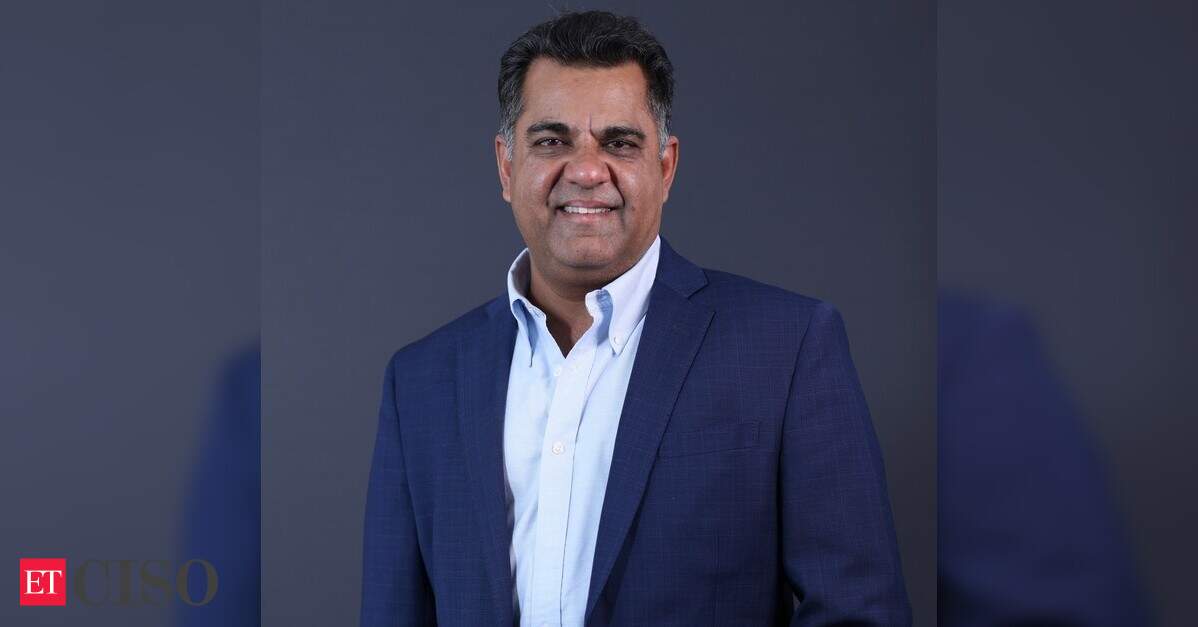 Pulse · ciso.economictimes.indiatimes.com
Explore how AI agents are changing the cybersecurity landscape, according to Dr. Vishal Gauri, CEO of Seclore. Discover the evolution of data security, the need for reinvented DLP, and the importance of direct control over information in the age of AI.
Read more Pulse · note.com
I think 2026 might be the "first year of adoption" for AI agents.This doesn't mean it's the first time AI agents have appeared. It means that using them—where even someone without specialized knowledge can assign tasks via a smartphone—has become accessible.
Read more Pulse · memeburn.com
Discover the 10 best hosting platforms for developers in 2026, led by Bluehost VPS. Compare features, pricing, performance, and deployment options.
Read more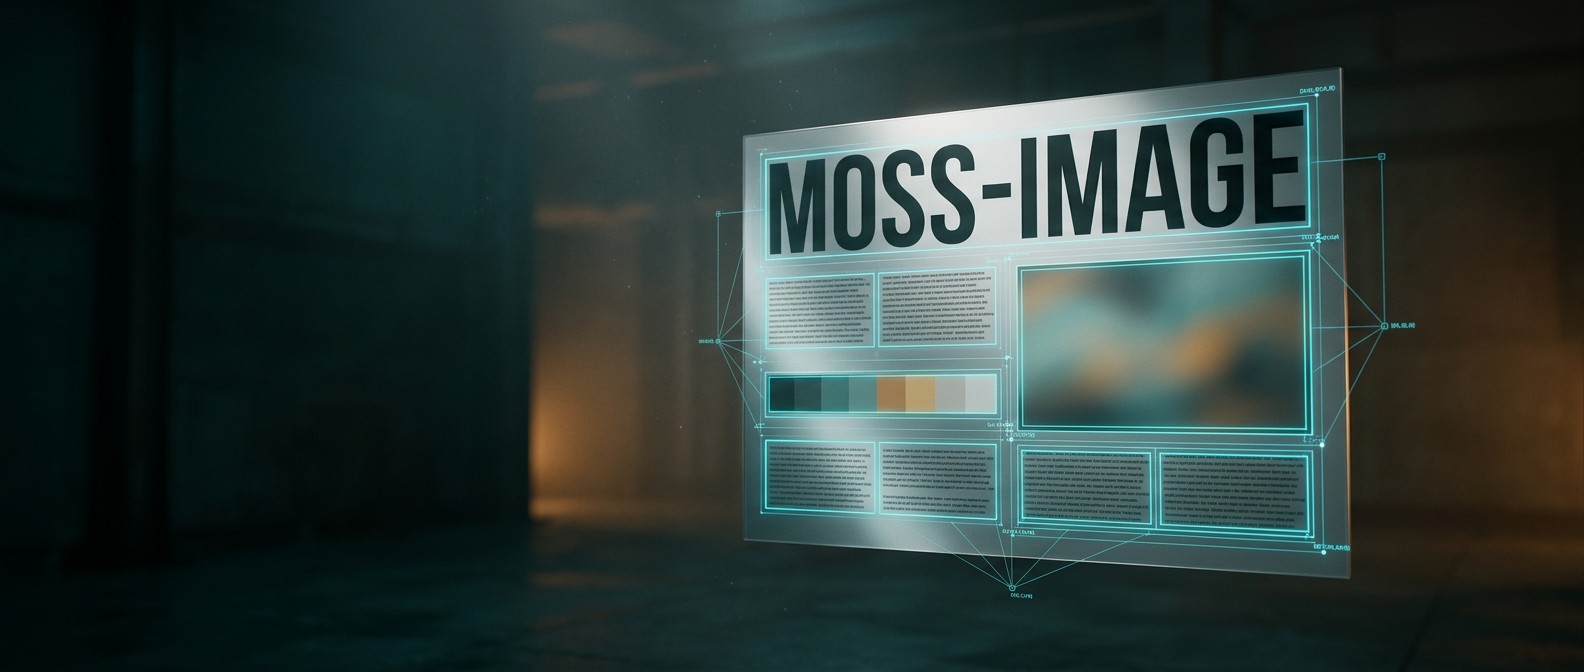 Pulse · intelligentliving.co
MOSS-Image: a 5B open-source model that renders readable bilingual text and JSON layouts, scoring 96.3 on long-text benchmarks.
Read more Pulse · intelligentliving.co
iFLYTEK Spark X2.6 is a 293B MoE model trained on domestic chips, with an open-source 4B on-device model, SparkAudio 1.0, and Agent OS.
Read moreSinging emotion recognition relies predominantly on deep learning models that achieve strong performance but offer limited insight into the vocal characteristics driving emotion, of- ten overlooking the singing voice as a distinct signal. We propose an interpretable singing emotion recognition framework using a compact set of singing-specific descriptors across prosody, spec- tral features, phonetics, and vocal technique. To decode model decisions and link predictions to measurable acoustic phenomena, we employ SHAP and apply GRAD-CAM to qualitatively assess the learned representations of vocal techniques. Evaluations show that singing-specific features reduce cross-singer variability, while vocal technique descriptors provide interpretable insights into singing expression. Furthermore, out-of-domain evaluation on VocalSet reveals interesting associations between emotional expression and ground-truth technical execution. The analysis highlights vibrato and pharyngeal techniques as salient cues of emotional delivery, with SHAP indicating that vibrato is context-dependent on articulation rate. These findings emphasize the value of domain-specific features for interpretable singing…
Recent work demonstrated that executing Bayesian Optimization (BO) using simply a linear surrogate with a clever transformation is enough to approximate the performance of the standard Gaussian-Process (GP) based version on high-dimensional test functions. When the decision region is a sphere, this strategy admits rapid exact acquisition. However, it is the unit cube we encounter most often in the BO literature, and in this setting a standard approach, namely a multi-start quasi-Newton method, is employed for solving the acquisition subproblem. In this article, we will discuss a series of results, both positive and negative, regarding the complexity of global resolution of various acquisition subproblems over the unit cube. On the basis of this discussion, we will propose a new acquisition function which is globally optimizable using significantly less execution time than the incumbent approach while maintaining or improving performance. The resulting method is competitive with GP-based BO in terms of accuracy per evaluation, and is superior in terms of accuracy per walltime on black-boxes of low to moderate computational intensity.
Large Language Models (LLMs) increasingly serve as reasoning components in modern software systems, yet a model that answers a logical query correctly can contradict itself when the same problem is restated in an equivalent form. Static benchmarks evaluate queries in isolation and therefore fail to expose such inconsistencies. To address this limitation, we present LGMT, an open-source tool that detects reasoning inconsistencies through metamorphic relations grounded in first-order logic. Given a source test case in premise-conclusion form, LGMT generates logically equivalent follow-up cases and checks whether the model's entailment predictions agree across the pair, without ground-truth labels. The tool provides 20 built-in metamorphic relations, supports custom ones verified by the Z3 theorem prover, and runs from a CLI or a web studio, including an offline mock mode requiring no API key. Across six widely used LLMs on a bundled benchmark of 3,091 metamorphic groups, LGMT reveals inconsistency rates ranging from 20.84% to 29.44%. LGMT is publicly available on GitHub at https://github.com/MaxwelsDonc/lgmt-tool, with a demonstration video at https://youtu.be/gou4opptu1U.
LLM agents optimize a ligand in a protein pocket by editing it step by step and docking each edit. Recent agents first spend extra dockings probing the complex with controlled edits; guidance induced from these probes is reported to help more than the chemical knowledge the model already carries. The probes are then discarded with the instance that produced them, so the obvious next step is to keep them in an experience base, letting a new pocket inherit what earlier ones already paid for. Such a base is read through a \emph{key}: the record properties under which past edits are pooled and a new one is looked up. Using the full log of one such run over the CrossDocked2020 test-set pockets, we ask whether its keys recur on a pocket the base has never seen and still separate improving from worsening edits. \crchange{Using} the contacts at the site being edited, the action, and the round as \crchange{a} key, the base separates them sharply. Within our analysis, this separation is largely explained by how much the edit changed the molecule's size, the action, and the round, none of which describes the target. That is not because the target is irrelevant: naming it outright separates…
Ecological monitoring, carbon accounting and biodiversity assessment increasingly rely on annual Earth embeddings--learned vectors that compress a year of satellite observation for every ten-meter pixel on Earth, consumed in place of the imagery itself. What these vectors mean has not been established. Here we decompose two widely used embedding products and show that they contain individual ecological features, including fire, forest clearing and crop type, validated against independent reference data on events across six continents. The recovered concepts date abrupt canopy loss to the first post-disturbance growing season and resolve severity well enough to separate prescribed fire from wildfire. Small fires that recover quickly are detectable in one product but not the other, which instead separates crops more strongly.
Frontier benchmarks need tasks that current models cannot solve. But a task that no model solves is not automatically a hard task. The same zero pass rate can come from a real capability gap, but it can also come from missing context, a broken reference solution, infrastructure…
Global vision--language similarities compress an image and a caption into one vector, preserving semantics but not which word corresponds to which region or how those regions are arranged; a model can recognize every word and object yet prefer a compositionally incorrect…
Textual-gradient methods automate prompt optimization through natural-language feedback, but their iterative updates can be unstable. We identify two sources of this instability: noisy gradients produced from already-correct examples and over-specialization to hard cases that…
Multimodal large language models (MLLMs) incur substantial computational overhead due to the reliance on hundreds of visual tokens to represent images. While token pruning has emerged as a promising approach to reduce the inference cost of MLLMs, existing methods typically…