Pulse · fiercewireless.com
Latest in AI and developer tools
The top stories in the fields you follow, at 08:00 your time.
 Pulse · ca.finance.yahoo.com
At TechXchange 2026, IBM (NYSE: IBM) is announcing new capabilities to help developers, IT and security teams put AI agents to work across business systems with clear authority and accountability. IBM brings together agent discovery, verified identities, access controls and performance evaluation to help organizations understand who owns each agent, control what it can access, and trace its actions across existing applications and infrastructure.
Read more Pulse · ibm.com
New Terraform capabilities bring trusted, governed infrastructure workflows to the agentic era, enabling humans and AI agents to safely operate at scale.
Read moreCybersecurity startup Cathedral reportedly used autonomous AI agents to access parts of Anthropic's internal business systems, including HR records and Slack messages. The incident has renewed concerns about vulnerabilities in third-party enterprise software,
Read more Pulse · moneycontrol.com
Erid Bio, Spark Labs, Dvar AI, Blackbird and Pathnovo are all raising fresh capital, with individual deals ranging from around $3 million to $10 million across AI agents, biotech and enterprise software,
Read more Pulse · techbuzz.ai
OpenAI debuts dots, transforming developer tools into always-on AI companion
Read moreAlexander Embiricos, the OpenAI executive responsible for dots, never wants to have a meeting with someone else's AI agent.
Read moreBy Jihoon Lee SEOUL, Oct 27 (Reuters) - South Korea's economy grew faster than expected in the third quarter as a global AI chip boom boosted exports and investments, advance central bank estimates showed on Tuesday,
Read more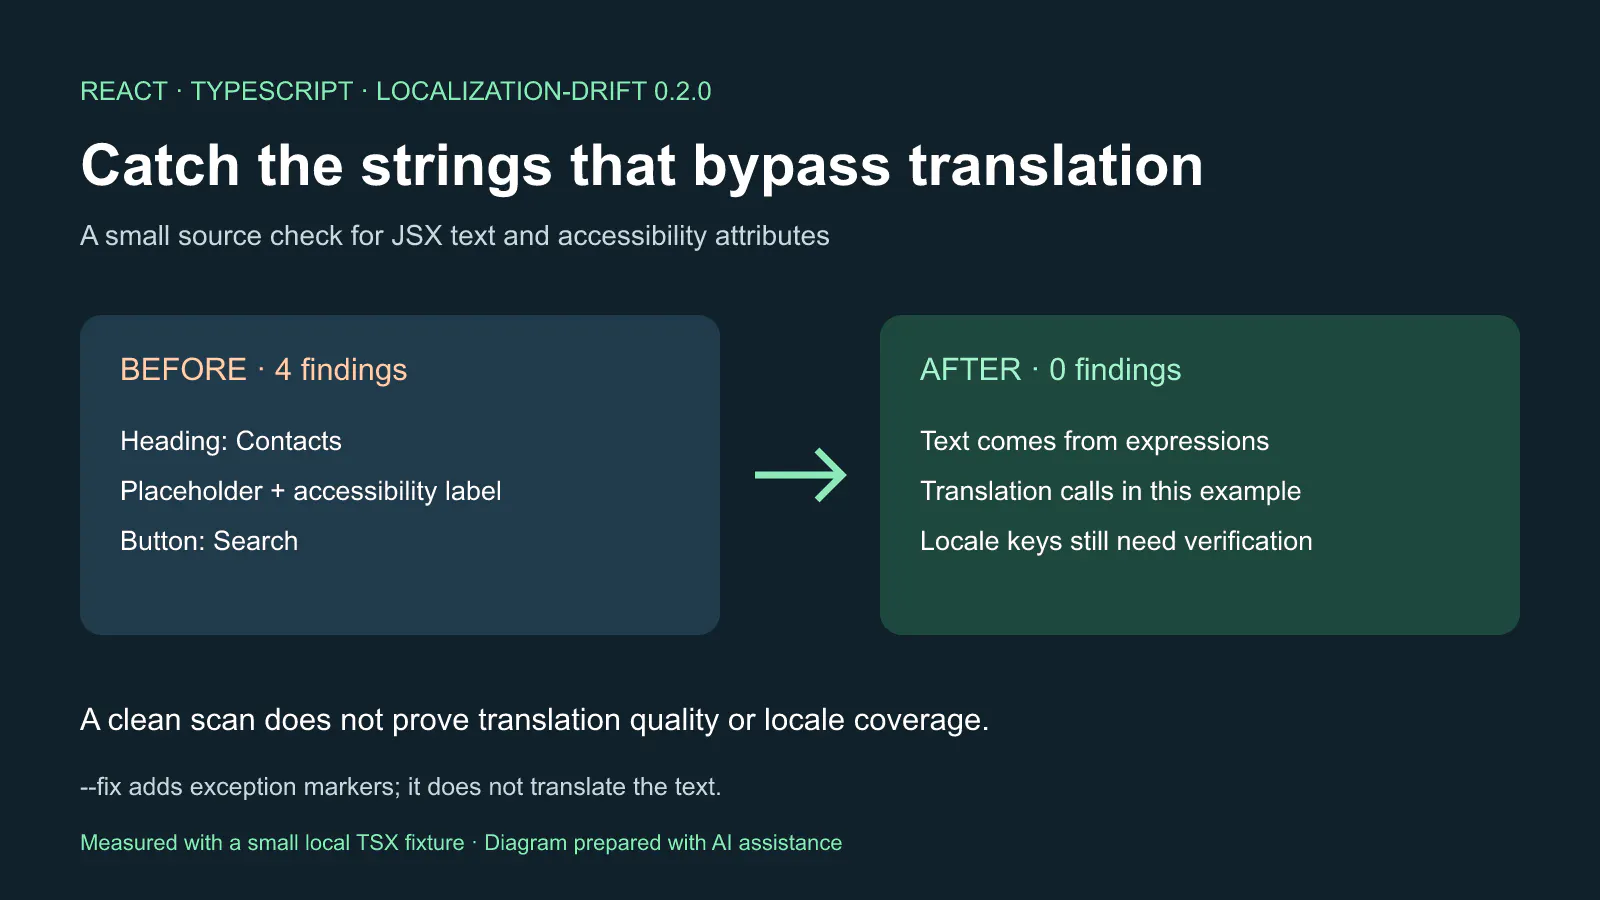 Pulse · t.co
Use localization-drift to find hardcoded React text, check accessibility labels, and collect CI reports. Includes a tested example and clear limits.
Read moreGenerative AI offers new approaches to turbulence problems in which incomplete observations or unresolved d.o.f. admit multiple physically plausible solutions. Potential applications include stochastic closures, super-resolution, data assimilation, uncertainty quantification, and the generation of Eulerian and Lagrangian flow ensembles. However, turbulence is not a conventional image-generation problem. Its multiscale dynamics, intermittency, extreme events, rough velocity fields and intrinsically stochastic transport make visual realism, pointwise error, and low-order spectral agreement insufficient measures of physical fidelity. We examine where generative AI provide novel capabilities with emphasis on diffusion models, score-based methods, and related probability-transport formulations. We discuss their use in unconditional generation, probabilistic reconstruction, reduced-order modeling, temporal evolution, and mesh-free representations. We argue that validation must address turbulence properties: energy transfer, structure functions, anomalous scaling, pdf tails, coherent structures, conservation laws, temporal consistency, ensemble diversity and generalization. Finally, we…
Multilingual transformer models are often assumed to generalise across languages, but their effectiveness for coreference resolution in low-resource settings remains unverified. We investigate this gap in Bengali, a language with over 250 million speakers but limited annotated coreference resources. We evaluate transformer-based pre-trained encoders under multiple settings, including zero-shot, fine-tuning, data augmentation, and cross-lingual transfer. Our results challenge several common assumptions about model generalisation and data efficiency in low-resource NLP. We demonstrate that a small amount of high-quality annotated data significantly outperforms larger mixed-quality datasets (p < 0.01). We find that data augmentation, particularly back-translation, does not improve performance and can degrade results in coreference resolution. Cross-lingual transfer is also inconsistent: transfer from a distant language like English reduces performance, and transfer from the related language Hindi provides no consistent benefit across models. Several widely used multilingual models exhibit collapsed embedding spaces, rendering them unsuitable for similarity-based clustering tasks.…
Learning rate decay (LRD) is critical for training high-performance models, yet most designs remain empirically driven. Although the Universal Budget Aware (UBA) LRD offers a theoretical framework, its reliance on SGD dynamics limits its applicability to modern Adam-type optimizers and leaves its key `optimization difficulty parameter' opaque. To bridge this gap, we propose the Universal Training Adaptive (UTA) LRD. Unlike UBA's fixed offline trajectory anchored solely to iterations, UTA treats LRD as a closed-loop shape-and-scale problem. By continuous-time formulation, UTA is training-state adaptive with segment-wise optimal shape. This adaptivity links external iterations with internal training states, enabling a near-optimal path in both progression shape and learning rate (LR) scale, a property unattainable by other LRDs, including UBA. Empirically, we demonstrate consistent improvements across language models (LLaMA 60M to 1B) and vision models (ResNet50, ViT-B) on ImageNet with plug-and-play ease and negligible overhead. Extensive ablation studies further confirm UTA's robustness across dimensions, including peak LR, final decay ratio, its parameter $\varphi_0$, component…
Grokking describes understanding something deeply and intuitively. In neural networks, it is the phenomenon where a network generalizes long after memorizing its training data. This delay has been linked to a fall in the effective rank of the network's weight matrices, but whether this rank compression drives grokking or follows it is still unresolved. We study a mean-field MLP and a one-layer transformer trained on modular arithmetic and observe that: (i) Compression follows the onset, not memorization. Every transformer memorizes its training data within 250 steps, while the grokking onset (the first step at which test accuracy reaches 95%) varies from 6,500 to 21,000 steps. The steepest fall in effective rank comes about 900 steps after the onset, however late the onset occurs, and networks that memorize without grokking compress far less. (ii) Subspace crystallization. We call the span of the fewest top singular directions of a weight matrix that preserve 99% of test accuracy its sufficient subspace. Its size can shrink as the margin between the correct and the best wrong output grows, so we also count the directions needed to keep the outputs within 10%. In the transformer,…
Large language models operationalize an intuitive, view of meaning as use. We argue that it faces a rule-following challenge. Using Kripke's interpretation of Wittgenstein, we argue that finite histories of use do not determine a unique rule for future extension. This reframes the debate about OOD generalization but also about NLP evaluation; benchmarks that measure performance on fixed use cases or local robustness, we argue, do not by themselves establish semantic competence. To evaluate whether models preserve rules and concepts under principled domain extension, we propose to evaluate two capacities, central to this ability: abstraction and recursion; and we offer an experimental paradigm for testing both.
Deploying Large Language Models (LLMs) in healthcare requires robust performance across two complementary dimensions - diagnostic reasoning: the convergent, evidence-driven task of inferring a patient's condition from clinical data to produce a diagnosis, and clinical…
Multimodal large language models (MLLMs) are increasingly explored as interfaces for scientific image analysis, where a visual question-answering (VQA) response may be paired with a spatial output that guides a downstream stage. A supervisor reads the language answer, while a…
Three-dimensional (3D) multi-contrast magnetic resonance imaging (MCMRI) provides rich anatomical and quantitative information but requires long acquisition times, motivating k-space undersampling. However, reconstruction of large volumetric datasets imposes substantial…
Music festival lineups emerge from complex relationships among artists, genres, releases, labels, and past performances, making the prediction of future lineups a natural fit for temporal knowledge graph (TKG) forecasting. In this work, we present a TKG covering 380 festivals…