AI coding tools can fix bugs, add features and make changes to software in seconds. But one developer says the more they rely on AI, the harder it becomes to keep everything working together. In a recent Reddit post,
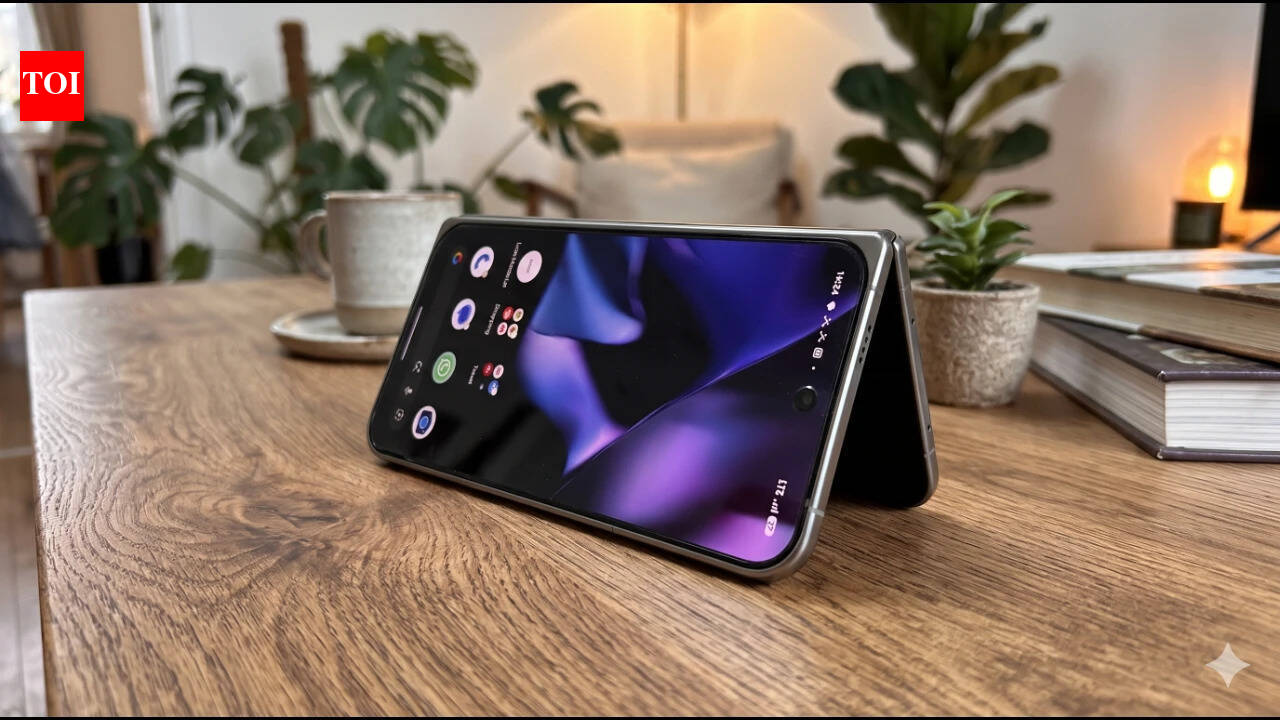
Google announced at the Android Dev Summit that starting next year, the Google Play Store will actively evaluate how well apps and games perform on foldable screens. While the detailed criteria for the evaluation process will arrive later this year, the company has said that apps which adapt cleanly to these flexible displays will earn prime promotional placement and enhanced visibility across the store.
Pi Network has launched four key updates ahead of its November 17-19 Ecosystem Summit, enhancing developer tools, token price tracking, AI-assisted app packaging, and identity verification services. Developers now have a redesigned portal for app settings, and the Pi BlockExplorer shows historical prices for testnet tokens. The SoloHost AI feature aids in preparing apps for Pi Desktop, while PiVerify adds advanced face and liveness checks for businesses. These improvements aim to support the…
How many AI models is your company using right now? Take a guess. Chances are the real number is higher than you assumed, and that’s not on you. Models sneak in sideways. A plugin someone installed, a team trial that never got switched off, a vendor who turned on an AI feature without much fanfare. […]
For the past three years, we've been worrying about AI taking our jobs. Writers, designers, analysts, customer service folks — the usual suspects. But here's a plot twist: the first people feeling the heat may be the very ones building AI.
Data attribution methods for Language Models (LMs) are typically evaluated using downstream tasks like fact retrieval. However, existing evaluations vary multiple dataset properties simultaneously, making it impossible to isolate exactly why an attribution algorithm fails. To diagnose these failures, we explore the design space of LLM data attribution, with a primary focus on evaluation. We introduce the Controlled Attribution Benchmark (CATT) for fact tracing, in which we fine-tune LLMs on entirely fictitious knowledge, providing unambiguous ground truth for attribution. This synthetic setup allows us to systematically alter one dataset configuration at a time, such as document redundancy and lexical distractors. With this configurable evaluation, we demonstrate that redundancy and distractors consistently degrade attribution performance. Rather than proposing a new estimator, we examine two design choices that are underexplored: the loss used to compute gradients and how per-token attribution scores are aggregated into a document score. We find that the true causal evidence within a training document is highly localized, but standard methods dilute this evidence into noise by…
The prompt is built automatically as "" * num_pages + "Multi page parsing.", and each page is encoded as one global view (base mode). The output contains one per input page, in the same order as image_files.
Amazon CEO Andy Jassy expects the frontier AI model race to produce several competitive models rather than a single winner, The post Amazon CEO predicts 6 to 8 AI models will be ‘good enough’ for almost everything appeared first on The New Stack .
Neural Radiance Fields (NeRF) have attracted extensive attention in recent years due to their strong capability for high-quality 3D reconstruction and novel view synthesis from multi-view images. Existing methods usually rely on high-quality sharp inputs, while real-world image…
Air operations rely on complex rules, established procedures, and time-critical analysis under limited connectivity and strict security constraints. In such environments, analysts must combine written doctrine with images, often without access to external computing resources.…
Relexicalization is a pivotal technique in clinical NLP, as it facilitates robust masking of sensitive information while synthesizing datasets that retain high-fidelity, real-world characteristics. However, preserving structural integrity, relational coherence, and temporal…
Comprehensive video understanding is crucial for advancing artificial intelligence toward the intricate dynamics of the physical world. While recent advances in Multimodal Large Language Models (MLLMs) have demonstrated remarkable capabilities in video understanding, existing…