New analysis finds signs the AI bubble is about to blow
"The odds of a deep and severe AI crash are rapidly increasing." The post New Analysis Finds Signs the AI Bubble Is About to Blow appeared first on Futurism.
Read moreThe top stories in the fields you follow, at 08:00 your time.
"The odds of a deep and severe AI crash are rapidly increasing." The post New Analysis Finds Signs the AI Bubble Is About to Blow appeared first on Futurism.
Read moreGoogle Docs and Drive add native Markdown editing and review. See file fidelity, comments, version history and the limits of the announced agent workflow.
Read moreStartup Cathedral says AI agents found paths into Anthropic's business systems in under 12 hours via third-party software. Anthropic disputes it.
Read moreCathedral AI agents found vulnerabilities in Anthropic systems in under 12 hours. Anthropic's valuation hitting $200B by December at 67% YES.
Read moreTSMC is reportedly weighing CoWoS price hikes of up to 20% as AI chip packaging demand outstrips supply, with NVIDIA reportedly on board.
Read moreCadence Design Systems has introduced a new portfolio of AI models to help engineers develop computer chips faster. The new suite, called Cadence Maestro, uses
Read moreAmerican Express has detailed how it will capture and authenticate customer instructions to AI agents before a payment is made, shifting liability to intent records.
Read moreAustralia weighs AI infrastructure rules; China's response to US restrictions raises questions about our investments' value and dependencies.
Read moreElon Musk says SpaceX closed a $40 billion chip deal with Apollo while lenders shut the door on smaller AI cloud firms.
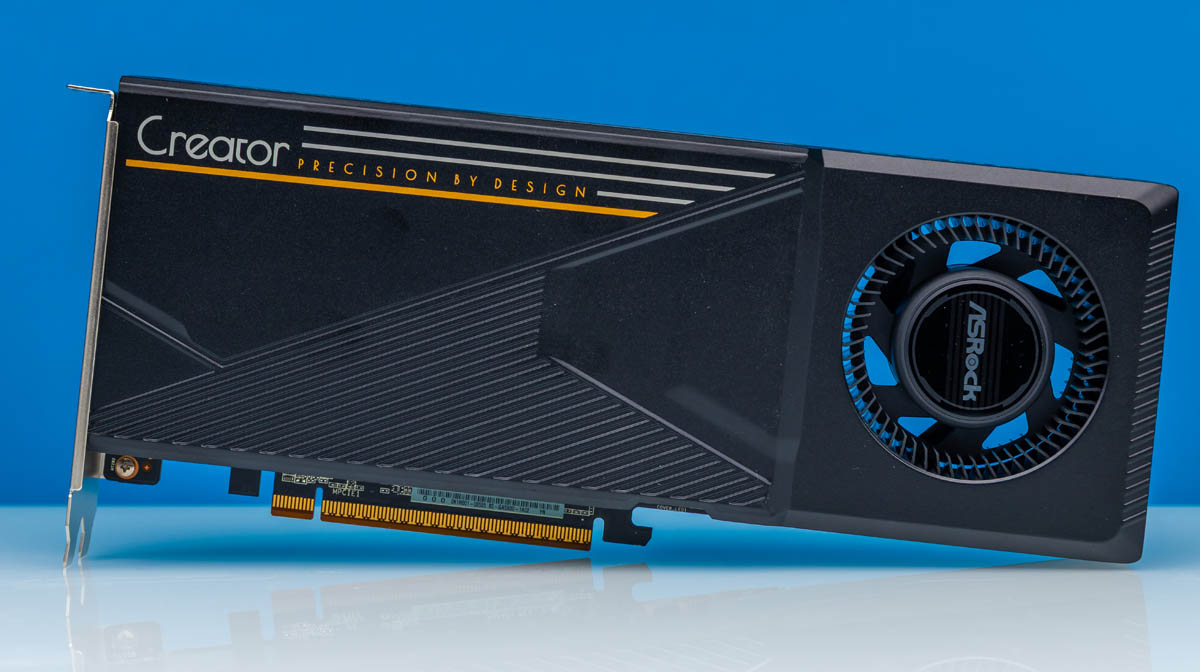
Read moreToday we are taking a look at ASRock's high-end Radeon AI inference card for workstations, the Creator Radeon AI Pro R9700. With 32GB of RAM and a $1700 price tag, the card is a highly affordable way
Read moreThis article argues that instruction-fine-tuned language models should be understood as implementing a genre, what is proposed as the instructional-conversational genre. This genre is an amalgamation of discursive language from prior conversations between generative models and humans recursively run through these massive neural networks. It is instantiated in applications through instruction fine-tuning, the inclusion of a pretext known as a system prompt, and the formalization of inputs in mark-up languages characterized by the use of special tokens and role assignment in turntaking structures.
Training generalizable embodied agents requires realistic, varied, and simulation-ready indoor environments. Language-guided methods support semantic planning and object-level reasoning, but precise spatial grounding remains difficult. Visual generative models offer rich priors over plausible arrangements, yet their outputs require geometric reasoning to become physically valid 3D scenes. We introduce SceneBloom, an agentic framework that combines visual layout sampling with contract-guided 3D compilation. A hierarchical sampler uses diffusion priors to generate furniture arrangements within functional zones. A compiler then uses relations extracted from each proposal to guide geometric fitting and local pose correction. Across five room types, SceneBloom attains the highest visual quality and physical stability among the compared methods and is the only method with no detected mesh collisions and out-of-bounds objects. Its layouts are also closer to the distribution of real rooms than those of all compared baselines. Object navigation policies trained in these realistic scenes achieve a higher success rate in held-out real scans than those trained on an equal number of real…
Actions that condition world models are highly heterogeneous, and thus existing action-conditioned world models are typically built for individual action types, fragmenting already limited action-annotated data across separate models. We introduce UniAction, a unified action-conditioning framework that represents any action as a sparse set of action elements, each with a discrete semantic identity and a continuous spatiotemporal grounding coordinate. By mapping these coordinates directly into the pretrained video model's native positional space, UniAction allows heterogeneous actions to condition a shared world model within the same spatiotemporal structure. We further introduce cardinality-calibrated attention to address the bias from differing action representation granularities. We evaluate UniAction on four representative action forms: force, camera control, hand pose, and robot pose. UniAction outperforms conditioning alternatives in action following, and a single jointly trained model surpasses the action-specific experts, showing that heterogeneous action data benefit from unified model and joint training.
To estimate correspondences across images, existing approaches match either sparse interest points, which is highly efficient but limited by repeatability, or dense pixel grids, which is robust but expensive. Furthermore, these approaches are trained with only matching pairs and thus often fail to reject unrelated pairs that exhibit visual symmetries, which is equally important in applications like Structure-from-Motion (SfM). We bridge these gaps by introducing FlexGlue, a neural network for asymmetric sparse-to-dense matching and disambiguation. Given two images and coordinates of points in the first image, FlexGlue estimates the coordinates of the corresponding points in the second image while simultaneously rejecting the pair if non-matching. By searching for a limited set of correspondences among dense pixels, our approach is both fast and effective at both matching and disambiguation: it combines the sub-pixel accuracy of dense matching with the speed of sparse matching, while rejecting incorrect pairs with high precision. Experiments on multiple datasets show that FlexGlue pushes the Pareto frontier in relative pose estimation and significantly outperforms existing…
Robust reinforcement learning (RL) is critical for reliable real-world deployment, where policies may fail under diverse shifts and disruptions. Existing robust RL algorithms offer a rich set of mechanisms and principles, yet two major barriers limit their broader potential: limited algorithm reusability and an unclear empirical capability boundary. We introduce RobustRLlib, an algorithm-centric library and benchmark that addresses both challenges. It integrates 17 representative robust online, offline, and safe RL algorithms under a unified interface for substantially improved reusability, together with an enhanced evaluation platform spanning diverse real-world shifts and advanced humanoid and vision-language-action tasks. Systematic evaluation over 273 perturbation configurations provides an up-to-date capability map of current robust RL algorithms, revealing where they remain effective and where substantial robustness gaps persist. As an open-source, user-friendly platform, RobustRLlib offers a reproducible and extensible codebase for applying existing methods to new problems and developing new robust RL algorithms.
Shadows are observable consequences of latent physical causes, arising from the interaction between illumination, object geometry, and scene structure. A model that understands shadows should be able not only to read a shadow's direction, but also to infer where a shadow should…
When tool-use agents write files, execute code, or send data, their final responses do not explain the resulting security events, and heterogeneous runtimes expose the relevant evidence through incompatible interfaces. We present AgentTriage, an executable contract for…
Vision-Language-Action (VLA) models have shown promising results in multi-task robotic manipulation by leveraging visual and language understanding for action generation. However, existing lightweight VLA models employ a single dense action expert to handle all tasks, which…
Recent work established that the infinite-width and infinite-depth limits of residual networks commute at initialization when residual branches are scaled by $1/\sqrt{depth}$. In particular, the network output converges to the same limit whether width and depth tend to infinity…