Pulse · sitepoint.com
Latest in AI and developer tools
The top stories in the fields you follow, at 08:00 your time.
 Pulse · 247wallst.com
AI server stocks are staging a comeback, but Super Micro faces an earnings report that must answer hard questions about shrinking margins, export control legal trouble, and whether a record order backlog can actually translate into profit.
Read moreBekaert already uses AI agents alongside the optimization engines in Unison Planning™ to speed up decisions and advance
Read moreGenRobot AI closed a $100M Series A+ to supply robot training data. Here is the founder lesson hiding inside the round. The post Robotics Startups Need Data: GenRobot AI Raises Series A+ appeared first on Under30CEO.
Read more Pulse · seekingalpha.com
Current growth is driven mainly by the Ansys acquisition; AI/IP contributions are expected to be gradual, with royalties not materializing until 2028. SNPS faces capex risks from hyperscalers, elevated net debt ($7.23B), and limited impact from buybacks due to high share-based compensation.
Read moreMicron and Nvidia both have compelling tailwinds as investments in artificial intelligence (AI) infrastructure accelerate.
Read moreMarvell is paying in stock for Lumentum's lasers. Lumentum shareholders will receive 4.5 Marvell shares per share owned, representing a 23.9% premium before talks leaked.
Read more Pulse · hoodline.com
The companies expect the deal to close by the end of the year, subject to what onsemi described as customary closing conditions. Onsemi said it entered into an agreement to acquire Ferric as part of a broader push into power delivery for next-generation AI processors,
Read more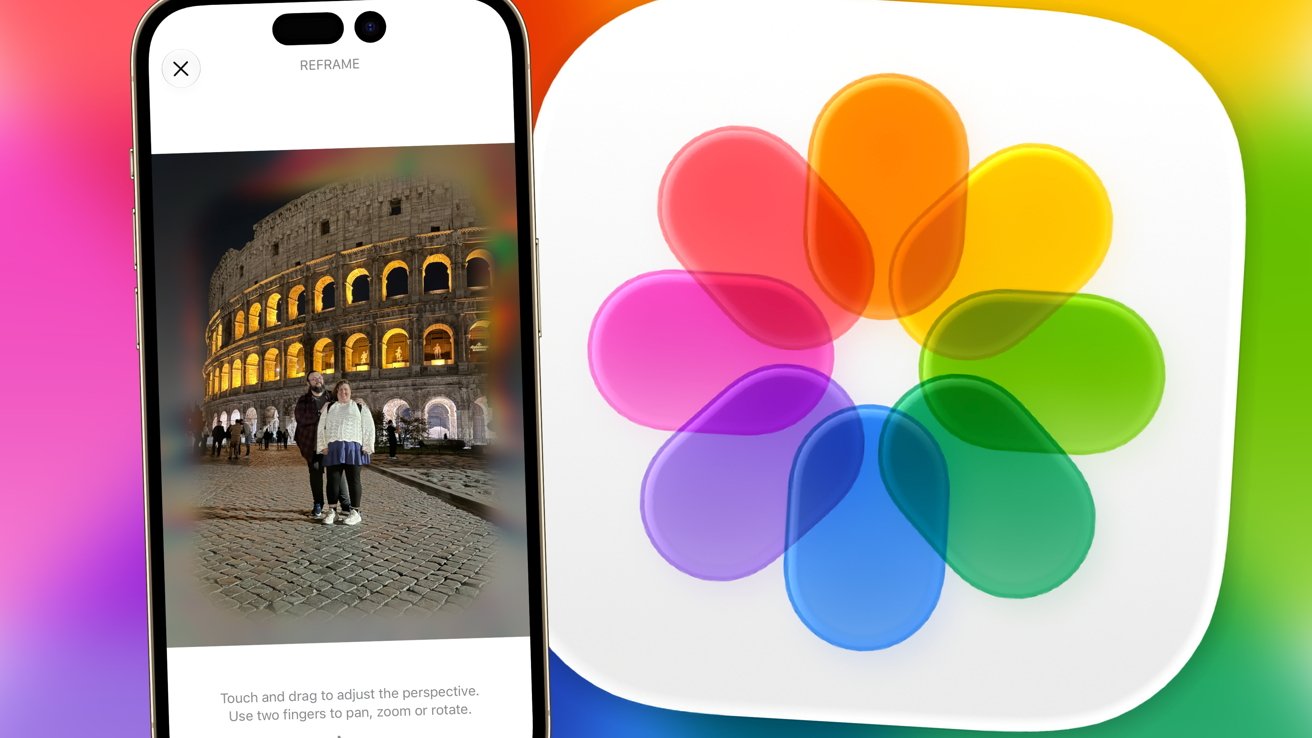 Pulse · iphoneislam.com
Apple has unveiled the revolutionary Spatial Reframing feature in the Photos app with iOS 27. This AI-powered tool allows users to change the capture angle and rotate photos with a single touch to make them look as if they were taken from completely different angles, while intelligently generating missing parts to make the photo look natural. Although it is still in its beta stage and shows some strange facial bugs, it promises a qualitative leap in the world of visual editing.
Read moreGeneral-purpose mobile manipulation requires a combination of capable robot hardware, scalable demonstration collection, expressive whole-body control, and effective policy learning. Yet these components are often developed independently, creating mismatches that limit the capabilities of the complete system. We present Pixel, a co-designed full-stack system for learning general-purpose mobile manipulation. Pixel combines a low-cost wheeled humanoid with human-aligned kinematics and compliant grippers, multiple teleoperation and robot-free human data-collection interfaces, a unified whole-body controller, and a common policy learning pipeline across human and robot demonstrations. A hierarchical learning stack further enables language-conditioned visuomotor control and long-horizon task execution. We evaluate the system across hardware, data collection, and policy learning, and demonstrate mobile-manipulation behaviors requiring dexterity, active perception, navigation, and whole-body coordination. We hope that Pixel provides an integrated and extensible foundation for studying how robot hardware, data, control, and learning can be designed together for robot learning. More…
Sensorized human demonstrations offer scalable data for mobile manipulation, but embodiment differences complicate policy learning. We present Pixel-UMI, a pipeline for learning environment-aware whole-body policies from human data. We first introduce Environment-Aware Retargeting (EAR), which combines reconstructed scene geometry with demonstrated head and gripper trajectories to determine robot posture and generate collision-aware joint and base targets. Delay-calibrated action assignment converts these trajectories into actions. However, kinematic differences can leave residual pose errors, creating viewpoint mismatches between human demonstrations and robot observations. We therefore introduce Retargeting-Error-Aware Masking (REAM), which uses these errors during training to reduce reliance on mismatched views at deployment. Finally, because estimated actions cannot fully capture contact-rich interactions, we collect on-policy human corrections through DAgger to improve performance. We evaluate Pixel-UMI on five challenging tasks spanning articulated-object manipulation, deformable-object handling, constrained-space reaching, whole-body collision avoidance, and contact-rich…
Learning from human data offers a scalable path toward embodied intelligence, yet it requires models to accurately understand fine-grained human actions from egocentric observations. However, existing benchmarks remain limited in action atomicity, temporal precision, and hand-action association. We introduce EgoActionBench, a benchmark that represents continuous human manipulation as temporally localized atomic actions associated with the left hand, right hand, or both hands. EgoActionBench contains 1,407 episodes with 41,132 human-refined action annotations. To evaluate such dense predictions, we propose an evaluation protocol that retrieves temporally eligible candidates, selects a prediction by content agreement, and scores semantic fidelity and temporal overlap alongside action precision and recall, jointly capturing what happens, when it happens, and which hand performs it. We benchmark 20 baseline models and systems on EgoActionBench and further adapt two backbones, Qwen3-VL-4B and LLaVA-OneVision-2-8B, through supervised fine-tuning followed by reinforcement learning on automatically annotated training episodes. EgoAction improves EgoActionScore by 15.9 and 23.2 points on…
Chain-of-Thought (CoT) generation has substantially improved the performance of Large Language Models (LLMs) on complex reasoning tasks, including code generation, data analysis, and exam-style question answering. Despite these advances, purely neural LLMs continue to struggle with elementary logical reasoning problems and lack the determinism, soundness, and reliability characteristic of symbolic reasoning systems. Conversely, classical symbolic methods such as SAT solving and exact cover guarantee correctness and completeness, but require problems to be expressed in highly specialized formal encodings, limiting their applicability to natural language inputs. In this work, we present a synergistic neuro-symbolic framework that bridges this gap by combining neural semantic parsing with deterministic exact cover reasoning. Given a Zebra-style logic puzzle in natural language, an LLM translates entities and constraints into structured tool calls that construct an exact cover instance. A symbolic solver then computes the solution and provides feedback to iteratively refine invalid, under- or overconstrained encodings, exploiting the uniqueness property of Zebra puzzles. We conduct a…
GUI web agents require realistic and interactive environments that remain stable during both evaluation and training. Live website evaluation suffers from changing content, access restrictions, and limited coverage of authenticated workflows, while existing synthetic environments for training often lack functional depth and visual fidelity. We propose WebHarbor, a suite of 153 executable and dockerized website environments that faithfully reconstruct the visual interfaces, content, and functional workflows of real-world web services under deterministic control. We build WebHarbor through task-driven human-agent collaboration, where environments evolve as new tasks expand their functional scope, coding agents implement the required changes, and human contributors audit visual fidelity, functional correctness, and task validity. The resulting suite comprises 3,518 tasks spanning multi-step and post-authentication workflows, where existing works often fail to cover. Beyond reliable evaluation, WebHarbor provides high-fidelity synthetic web environments for cost-efficient reinforcement learning (RL). We demonstrate that a Qwen 4B-level GUI agent trained with RL in WebHarbor…
Large Language Models (LLMs) can generate toxic content, motivating effective test-time detoxification. Existing representation steering methods often rely on static or coarse interventions and provide imprecise guidance because they inadequately model transitions between toxic…
To accelerate materials discovery, language models must be able to address problems at the research frontier. Yet textbook- and examination-derived benchmarks primarily assess established knowledge, leaving performance on frontier research problems largely untested. We…
Disaggregated LLM inference separates the prefill and decode phases across GPU pools, generating massive KV-cache transfers. Because these transfers last hundreds of milliseconds to seconds, they behave as mega elephant flows that dominate link bandwidth utilization. In this…
Synthesizing realistic tumors on medical images helps address data scarcity for clinical AI. Existing diffusion-based methods, however, lack fine-grained attribute-level controllability, closed-loop quality verification, and awareness of which morphological patterns are…