GPT-6.1 Terra is listed for Responses and Chat Completions. Review tool-calling limits, text/image input, reasoning controls, token budgets and API pricing.
"The odds of a deep and severe AI crash are rapidly increasing." The post New Analysis Finds Signs the AI Bubble Is About to Blow appeared first on Futurism.
Google Docs and Drive add native Markdown editing and review. See file fidelity, comments, version history and the limits of the announced agent workflow.
Researchers at a cybersecurity startup said AI agents found paths into Anthropic's business systems in less than 12 hours, according to a Washington Post report published Monday.
GitHub Copilot reports add customization names and up to 25 entries per record. Check supported clients, minimum versions, access and historical reporting limits.
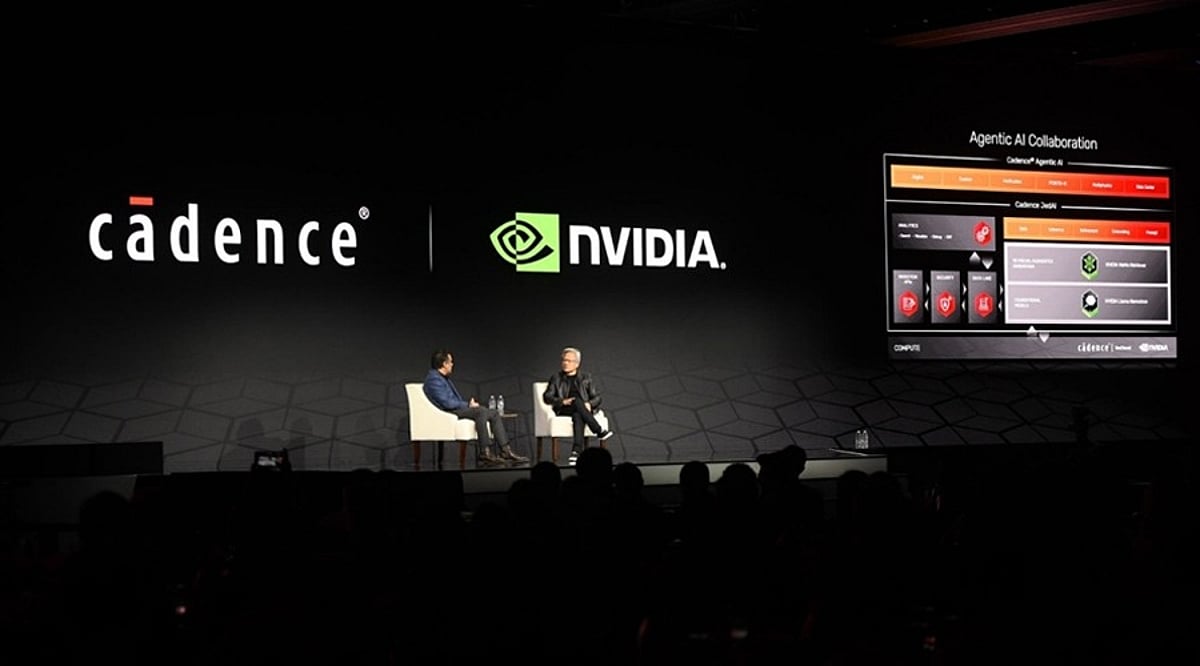
Cadence Design Systems has introduced a new portfolio of AI models to help engineers develop computer chips faster. The new suite, called Cadence Maestro, uses
This article argues that instruction-fine-tuned language models should be understood as implementing a genre, what is proposed as the instructional-conversational genre. This genre is an amalgamation of discursive language from prior conversations between generative models and humans recursively run through these massive neural networks. It is instantiated in applications through instruction fine-tuning, the inclusion of a pretext known as a system prompt, and the formalization of inputs in mark-up languages characterized by the use of special tokens and role assignment in turntaking structures.
Flint is Recursive’s mixture-of-experts language model for coding agents, with 39.8 billion total parameters and approximately 2.5 billion active per token. It is designed to investigate codebases, fix bugs, implement features, and write tests.
OpenAI has released GPT-6.1 Terra, a mid-range model that cuts API prices in half compared to its predecessor. Analysts say it sets a new standard for intelligence per dollar, especially for everyday computing tasks and AI-driven computer control. The article GPT-6.1 Terra…
Consensus among LLM judges is often taken as strong evidence that a decision is correct. This assumes that judges make their errors independently. In practice, LLM judges are often trained and evaluated in similar ways, so they can make the same mistakes. We study how this…
As LLM applications integrate with external tools, they are increasingly exposed to indirect prompt injection (IPI), where adversarial instructions are embedded in retrieved content. Conventional IPIs fire on contact: the moment an agent ingests the content, it carries out the…
Generative Adversarial Networks (GANs) have demonstrated strong performance in generating high-quality synthetic data. However, they are limited by no formal guarantees regarding convergence and the effectiveness of the learning process. In practice, this leads to training…
Vision Transformers devote most of their parameters to MLPs for channel mixing, but still rely on quadratic multi-head self-attention for token interactions. While linear attention fixes the complexity problem, bringing it down to O(N), it is usually just paired with the same…