AI server stocks are staging a comeback, but Super Micro faces an earnings report that must answer hard questions about shrinking margins, export control legal trouble, and whether a record order backlog can actually translate into profit.
GenRobot AI closed a $100M Series A+ to supply robot training data. Here is the founder lesson hiding inside the round. The post Robotics Startups Need Data: GenRobot AI Raises Series A+ appeared first on Under30CEO.
Current growth is driven mainly by the Ansys acquisition; AI/IP contributions are expected to be gradual, with royalties not materializing until 2028. SNPS faces capex risks from hyperscalers, elevated net debt ($7.23B), and limited impact from buybacks due to high share-based compensation.
Marvell is paying in stock for Lumentum's lasers. Lumentum shareholders will receive 4.5 Marvell shares per share owned, representing a 23.9% premium before talks leaked.
The companies expect the deal to close by the end of the year, subject to what onsemi described as customary closing conditions. Onsemi said it entered into an agreement to acquire Ferric as part of a broader push into power delivery for next-generation AI processors,
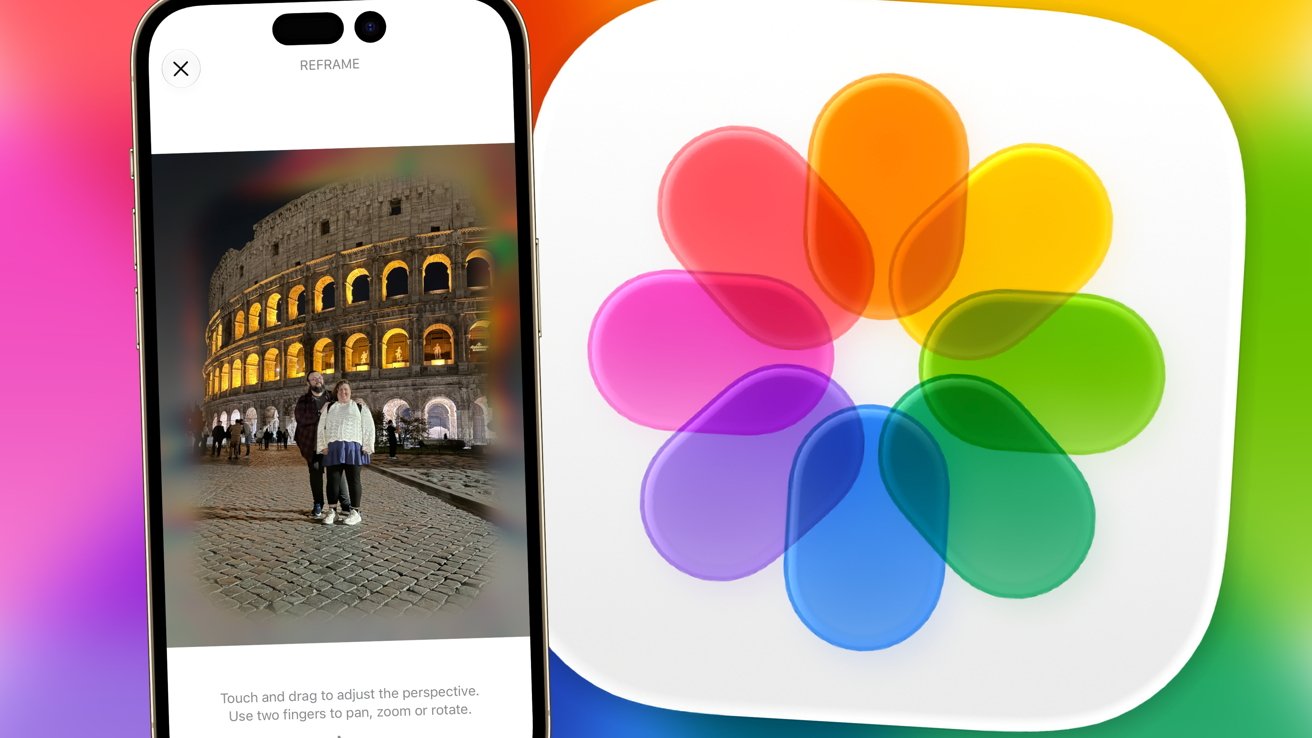
Apple has unveiled the revolutionary Spatial Reframing feature in the Photos app with iOS 27. This AI-powered tool allows users to change the capture angle and rotate photos with a single touch to make them look as if they were taken from completely different angles, while intelligently generating missing parts to make the photo look natural. Although it is still in its beta stage and shows some strange facial bugs, it promises a qualitative leap in the world of visual editing.
General-purpose mobile manipulation requires a combination of capable robot hardware, scalable demonstration collection, expressive whole-body control, and effective policy learning. Yet these components are often developed independently, creating mismatches that limit the capabilities of the complete system. We present Pixel, a co-designed full-stack system for learning general-purpose mobile manipulation. Pixel combines a low-cost wheeled humanoid with human-aligned kinematics and compliant grippers, multiple teleoperation and robot-free human data-collection interfaces, a unified whole-body controller, and a common policy learning pipeline across human and robot demonstrations. A hierarchical learning stack further enables language-conditioned visuomotor control and long-horizon task execution. We evaluate the system across hardware, data collection, and policy learning, and demonstrate mobile-manipulation behaviors requiring dexterity, active perception, navigation, and whole-body coordination. We hope that Pixel provides an integrated and extensible foundation for studying how robot hardware, data, control, and learning can be designed together for robot learning. More…
Idol turns one picture of an object into a 3D Gaussian splat. Give it a render, a generated image or a photo: it removes the background, frames the object and generates up to 1,048,576 Gaussians, written as a standard 3DGS .ply. It runs on consumer GPUs, using 7.2 GB of VRAM…
Demand for advanced chips is rising. The processes to build them are getting more complex. And the margin for error is shrinking. For engineers, understanding how a process change will behave, how a material will interact with a new step, how a defect maps back to a root cause…
AI agents combine language models with external data and tools that can modify files, call APIs, or execute code. Security failures can arise when adversarial content changes an agent's tool use or when the surrounding software contains vulnerabilities such as path traversal or…
Unobserved common causes are pervasive in real-world time series and can induce spurious associations that causal discovery methods mistake for direct edges. We propose LUCID (Learning Under Confounding for Inference and Discovery, a regime-adaptive deconfounding layer that…
Cytopathology detection requires open-vocabulary recognition because cellular categories are fine-grained, long-tailed, and continuously evolving across different organ systems. However, existing cytology detectors are mostly single-domain and closed-set, and there is still no…
Vision-Language-Action models (VLAs), while showing strong potential for robot control, require massive amounts of high-quality imitation learning data. Moreover, the absence of an explicit world model casts further doubt on their control capabilities. In this concept paper, we…